DHH argues that hand-written production code is becoming economically obsolete and that engineers increasingly program by describing outcomes in natural language. He presents 37signals' move toward agent-generated native apps and Rust as evidence that AI changes the economics of implementation. This is the primary material for the two responses below.
Jared Norman responds directly to DHH's keynote. He questions generated lines of code as a productivity metric, challenges the idea that generated code rarely needs to be read, and asks what DHH's new direction means for Rails itself.
Alex Ewerlof argues that cheaper code generation does not solve software engineering because production systems still require understanding, reliability, security, maintenance, and accountability. The central point is ownership: AI can generate code, but humans still bear the consequences when the system fails.
Git has two useful ignore mechanisms beyond repository .gitignore: .git/info/exclude for private rules specific to one clone, and a global ignore file for machine-wide clutter. .git/info/exclude is particularly useful for personal agent plans, scratch files, and other repository-local artifacts that should never be committed.
A programming-language parody built around extreme British politeness. Mutation requires an apology, commands become courteous requests, exceptions become "Regrettable Circumstances," and even concurrency has etiquette. It commits to the joke all the way through the language design.
In September 2026, OpenAI announced that an internal AI system had produced a proposed solution to the Navier-Stokes existence and smoothness problem, including a Lean formalization. The problem had remained unresolved for roughly 90 years. OpenAI says its construction shows smooth fluid dynamics developing a finite-time singularity and says it does not intend to claim the Millennium Prize. OpenAI
So apparently one AI system can attack a 90-year-old Millennium Prize Problem. This provides useful context for the next breakthrough.
Two weeks later, Anthropic tackled another famously stubborn computer-science problem: reading a Markdown file. Claude Code v2.1.277 officially added AGENTS.md support, so when a project has no CLAUDE.md, Claude Code can read AGENTS.md instead. GitHub
Unfortunately, the local-file-reading breakthrough had an implementation detail: the reporter found that support was gated by a remote Anthropic feature flag. With non-essential traffic disabled, or in some gateway, Bedrock, or Vertex-style environments, the gate could fail and Claude Code would silently not read the local file. Navier-Stokes: apparently tractable. AGENTS.md: distributed systems problem. GitHub
If the solution to cloud AI is obviously "buy an enormous Mac," this is the machine. Federico Viticci tests an M5 Ultra Mac Studio as a host for persistent local agents and finds that its large unified-memory pool and much faster prompt processing make long-running local agent loops genuinely practical. The tested machine had 256 GB of RAM; Apple increased M5 Ultra memory bandwidth to 1.2 TB/s, and Viticci reports substantially better long-context agent performance than on his M3 Ultra. MacStories
A broad set of skills and engineering principles for making coding agents investigate before changing code, choose an appropriate workflow, verify their work, and avoid low-quality high-throughput coding. /poteto-mode routes work across debugging, features, refactoring, performance, architecture, autonomous runs, and other workflows.
A composable collection for moving engineering work from fuzzy requirements through specification, tickets, implementation, TDD, debugging, review, and architecture. Useful when you want individual workflows that can be combined rather than one monolithic process.
An opinionated development workflow that stops an agent from jumping directly from request to code. It pushes work through design, planning, isolated implementation, TDD, debugging, review, and final verification.
A larger operating setup for coding agents combining skills, specialized agents, hooks, rules, memory, security, orchestration, and verification. Its main value is treating those pieces as one engineering workflow rather than unrelated prompts and plugins.
Gives agents a "lazy senior developer" rule: first ask whether anything needs to be built, then look for existing code, standard-library functionality, native platform features, or an installed dependency before adding custom code.
The compact decision policy behind Ponytail. Minimal implementation is the default, while security, accessibility, data integrity, and other real requirements are explicitly protected from over-aggressive simplification.
Reviews a change specifically for unnecessary complexity: code that can disappear, wrappers that add no value, functionality that should be reused, or custom implementations that native features can replace.
The original Ponytail discussion, including practical debate about the central tradeoff: reducing unnecessary code without accidentally deleting important safety or readability.
Inserts a decision gate before non-trivial implementation: Free vs. Build vs. Buy. Existing projects are supposed to be checked for licensing, maintenance, source quality, and dependency risk rather than accepted because they have many GitHub stars.
The launch discussion captures the motivation well: AI makes producing new code feel nearly free, while ownership, debugging, maintenance, and edge cases remain expensive.
Creates a behavioral PRODUCT.md before implementation. It focuses on what users can do, expected behavior, edge cases, and invariants, while leaving types, modules, algorithms, and other implementation choices for a separate technical specification.
A controlled-language standard for technical documentation. It reduces ambiguity through explicit writing rules, stable terminology, simpler sentence structures, and restricted meanings for words. It is a stronger foundation than simply telling an LLM to "write clearly."
A practical writing standard for RFCs, README files, design documents, PR descriptions, and commit messages. It emphasizes concrete developer language, stable terminology, useful structure, and low reader effort.
Removes recurring LLM prose habits without flattening the intended voice. It targets filler, stock AI vocabulary, vague attribution, canned contrasts, and inflated phrasing through explicit rules.
Colin Breck argues that AI can make writing cheap for the author while making reading expensive for everybody else. His preferred workflow is human-authored prose with AI used for verification, omissions, citations, editing, and simplification rather than outsourcing the thinking performed through writing.
Treats maintainability as the amount of work required to understand a system. It tries to reduce how many abstraction layers a reader must trace and how much hidden or mutable state they must hold in working memory.
A small collection of agent skills containing show-me and related HumanLayer workflows. Useful as the parent repository for installation and discovery.
Helps agents choose a compact visual representation instead of explaining everything through prose. Depending on the problem, it can use pseudocode, call trees, component trees, diffs, Mermaid diagrams, or focused HTML.
Discussion around the practical value of giving coding agents a visual explanation vocabulary instead of letting them default to long textual explanations.
Changes the interaction style of coding agents so the action is easy to find: lead with the next step, keep lists bounded, suppress tangents, make progress visible, and avoid unnecessary preambles and repeated summaries.
Addy Osmani explains why mature codebases require more agent discipline: the repository does not contain all of the historical, operational, and organizational constraints of the real system. He recommends codebase archaeology, durable context, characterization tests, independent verification, and scaling autonomy according to blast radius and recoverability.
After fixing one bug, bug-echo derives the broken pattern from the change and searches the repository for similar instances. The useful idea is to turn a real defect into a temporary codebase-specific static-analysis rule.
The discussion where bug-echo was introduced. The most useful part concerns false positives and the pre-fix validation step used before searching the whole repository.
Gives agents persistent memory that is explicit, sourced, correctable, and shareable across agent environments. Important facts become controlled data that can be searched and revised instead of disappearing with a conversation.
Protects the active context window from huge tool outputs. Large files, logs, command output, and fetched data are processed or indexed outside the model, and only the useful result comes back into context.
The core rule is essentially "think in code": when an agent needs to inspect a large amount of information, write a small computation to analyze it instead of loading all the raw data into the LLM.
The original Hacker News discussion around Context Mode and the problem it targets: agent tools can permanently consume huge parts of the context window with output that was useful only once.
Browser automation designed for agents rather than traditional UI-test code. It uses persistent sessions, structured snapshots, compact element references, and CDP-based interaction so agents can navigate sites without repeatedly consuming full DOMs or screenshots.
Turns a SaaS URL into a structured product and platform investigation covering interfaces, user journeys, integrations, business signals, and other evidence. Its strongest idea is provenance: claims are distinguished as directly confirmed, externally reported, or inferred.
A searchable directory and installation layer for reusable agent skills from many repositories. It gives skills a common discovery and installation path across different agent environments.
OpenClaw's registry for publishing, versioning, finding, installing, updating, and moderating skills and plugins. It is closer to a package registry for agent capabilities than a static prompt collection.
Cursor's official plugin repository and the upstream source for pstack. It is useful both as a distribution mechanism and as the canonical place to inspect the actual skills, agents, manifests, and supporting files.
The author once overrode the author's own website blocker for 444 minutes. After that the author stopped relying on willpower and started making the internet boring: app deletions, LeechBlock, grayscale mode, and a custom userscript.
The author think many people misunderstand the purpose of code review. The purpose of code review is not for the reviewer to find bugs, and certainly not for them to ensure that the code is bug-free. Anyone who depends on code review to find bugs is living in a fool's paradise. As everyone should know by now, it is not in general possible to find bugs by examining the code. The primary purpose of code review is to find code that will be hard to maintain. The reviewer looks at the code and tries to understand what it is doing and how. If they can't, that means it will be hard to maintain in the future, and should be fixed now, while the original author is still familiar with it.
It’s also been ported to many other editors and terminals; the most complete list is probably here. If your editor is not on the list, try searching for it by name—it might be built-in already! I always wondered where these color themes come from, and now I became an author of one (and I still don’t know).
Feel free to use Alabaster as is or build your own theme using the principles outlined in the article—either is fine by me.
As for the principles themselves, they worked out fantastically for me. I’ve never wanted to go back, and just one look at any “traditional” color theme gives me a scare now.
I suspect that the only reason we don’t see more restrained color themes is that people never really thought about it. Well, this is your wake-up call. I hope this will inspire people to use color more deliberately and to change the default way we build and use color themes.
Applying human ergonomics and design principles to syntax highlighting
Engineers often complain that visibility should be their manager’s job. In other words, they think engineers should be able to focus on the code, while their…
Architecture decision record (ADR) examples for software planning, IT leadership, and template documentation - architecture-decision-record/architecture-decision-record
Nicolae Vartolomei · 2017/11, updated on 2022/09 A selected list of timeless and influential papers in distributed systems that shaped the research in the field. 1985. Distributed snapshots: determining global states of distributed systems.https://doi.org/10.1145/214451.214456 Michael J.
What if retries could know when they’re helping, and when they’re making things worse? Uber Engineering built error ownership to prevent and contain retry storms.
C Language Enum Tips & Tricks is a broad guide covering The Basics, Name Strings, Enum Size, Smaller Storage Classes. Later sections move through Summary, with the page serving as a practical reference rather than a single-idea essay.
Everything I wish I knew when learning C is a broad guide covering General resources, Good projects to learn from, Compilation, linking, headers, and symbols, Undefined behaviour (UB). Later sections move through Do not use these functions, Arrays aren’t values, Essential compiler flags, Three types of memory, and when to use them, with the page serving as a practical reference rather than a single-idea essay.
Intrusive Data Structures is a broad guide covering From: Crate intrusive_collections, From: Data Structures in the Linux Kernel - Doubly linked list, Gemini Definition, Who is responsible for freeing the object?. Later sections move through From: Boost - Intrusive and non-intrusive containers, From mgaunard, Gemini:, C, with the page serving as a practical reference rather than a single-idea essay.
a bunch of stuff i used to not know about K&R C is a broad guide covering wait hang on real quick before i get started here's a thing i thought about, void is an ansi invention, apparently, different floating point types, some more interesting stuff with type specifiers. Later sections move through different behavior for integer promotion, unsigned integer constants, 8 and 9 were valid digits in octal constants, missing escape sequences, with the page serving as a practical reference rather than a single-idea essay.
A straightforward implementation in C looks like this: If the numbers are randomly distributed, the result of the ‘if’ condition becomes unpredictable for the CPU’s branch predictor. the authors can avoid this problem by using a branchless approach: While this version introduces an unconditional store (writing to memory even if the condition isn’t met), its cost is typically far lower than the heavy penalty of a branch misprediction. *Performance Comparison** To get meaningful results, the authors run both routines for 1000 iterations using 100,000 random numbers.
Everyone Should Know SIMD is a broad guide covering Background: What Is SIMD?, The Common Shape, A Real Example, Step 1: Broadcast Constants. Later sections move through Step 2: Loop One Vector at a Time, Step 3: Perform the SIMD Operation, Step 4: Reduce the Vector Result, Step 5: Finish with the Scalar Tail, with the page serving as a practical reference rather than a single-idea essay.
Abstract: SQLite is a C-language library that implements a self-contained, in-process relational database engine supporting full-featured SQL, an advanced query planner, and ACID transactions. By many estimates, SQLite is the most widely used software library in the world today.
Over its 26-year history, SQLite has gained a reputation as software that "just works". This talk goes over the design choices and development practices that have, at least in the opinion of the lead developer, resulted in that reputation.
The author is about as pro-AI as you can be, but this is becoming a pet peeve of the author's (and the author is not alone). That's why the author love the AI;DR acronym as the author's new solution for ignoring the walls of slop.
Two rules keep an LLM from pasteurizing your writing: never take a word it suggests, and never let it encourage you. Then hand it all the tedious work.
E-ink bird frame for Raspberry Pi - real-time bird detection by audio, fully local AI, rendered as real, hand-cut 1800s bird illustrations. - arnegiacomo/fugleramme
Just a few years ago, realistic local speech generation seemed unimaginable. Today, its quality is exceptional and, crucially, it delivers these results without compromising privacy.
Data Compression Explained is a broad guide covering About this Book, 1. Information Theory, 2. Benchmarks, 3. Coding. Later sections move through 4. Modeling, 5. Transforms, 6. Lossy Compression, Conclusion, with the page serving as a practical reference rather than a single-idea essay.
Fintech Engineering Handbook is a broad guide covering Principles, Representing money, Recording money: the ledger, Executing money flows. Later sections move through The external world, Controls and access, Testing,
Know your domain, with the page serving as a practical reference rather than a single-idea essay.
Time is where application code meets uncertainty: clock skew, wall-clock corrections, ambiguous ordering, late schedulers, and business-calendar boundaries.
The author get asked fairly often what people need to know to be hireable as a graphics programmer. the author figured it was time to make a page to link instead of re-typing it each time. the authors are in a strange time w…
The author is happy to announce the release of Box3D, an open source 3D physics engine. It is now available on GitHub. Box3D repository You can think of Box3D as a fork of Box2D, extended with many features needed for 3D games. Some additions: Triangle mesh collision Height-field collision Baked compound collision The core architecture of Box3D remains almost identical to Box2D. C API All library source is C17 Sub-stepping solver Continuous collision Graph coloring for large islands Wide SIMD contact solver Multi-threading hooks Optional internal scheduler Large world support with doubles for position Cross platform determinism Recording and replay If you want to see Box3D in action, watch this video:
If you are having trouble figuring out how to do these assignments without help, then the author's book with videos “Learn Java the Hard Way” will explain things a lot better. (Especially if you have never coded before!) Or if you have finished most of these assignments and are ready for the object-oriented side of Java, “Learn Object-Oriented Java the Hard Way” is the book for you! If you've ever tried to teach yourself programming and couldn't quite get going, then these assignments are for you.
The first batches of Quake executables, quake.exe and vquake.exe were programmed on HP 712-60 running NeXT and cross-compiled with DJGPP running on a DEC Alpha server 2100A. the authors moved to Intergraph hardware running Windows NT right after shipping Quake. - John Carmack[1] The next versions of Quake, winquake.exe, glquake.exe, and QuakeWorld (qwcl.exe and qwsv.exe) were all developed and compiled on Windows NT with Visual C++ 4.X.
The first step in building the author's text editor is to implement the core API. If you’re wondering why the author want to do this, the original article is here.
2026-07-26 Zig by Example { zigbyexample.neocities.org }
Zig by Example is a broad guide covering Getting Started, Basic Types, Functions and Errors, Control Flow. Later sections move through Compound Types, Standard Library, Command-line Programs, Async/Await and I/O, with the page serving as a practical reference rather than a single-idea essay.
Some thoughts deserve more time. Writing by hand slows them down. A place for authentic thinking. No algorithms or feeds or likes. Just your pages, published as…
Ride the Yamanote line through a voxel Tokyo synced to Japan's real clock, weather, and seasons. A lofi bed plays while N5 sentences are read aloud and drift by as subtitles — an ambient Japanese study room you just press play into.
How to Make a Nintendo 64 Game in 2026 is a broad guide covering The Engine, N64 Hardware and Platform Library, Dev Environment, The Game. Later sections move through Rendering, Sound & Music, Publishing & Sales, Resources, with the page serving as a practical reference rather than a single-idea essay.
Just for the pleasure, a selection of vintage control rooms dating back to the Soviet era! A beautiful collection of control rooms filled with large buttons and analog dials, long before the democratization of computers and screens.
Modern programming languages are full of violence, vulgar abbreviations, and naked imperatives. Bespoke is a statically typed alternative in which exceptions are regrettable circumstances, mutexes ...
An if statement is an accusation: this condition is true, now do as I say. Bespoke instead places a hypothetical question before the court.
Should it please the court to consider whether carriageCount is strictly greater than 10,
    Dear Output Console,
    Kindly convey to the standard stream the Textual Passage "Capital progress, indeed!".
    Thank you kindly.
Or, should the contrary prove true,
    Dear Output Console,
    Kindly convey to the standard stream the Textual Passage "A modest showing, regrettably.".
    Thank you kindly.
Thus concludes the matter.
For a given truth value, the choice of branch is deterministic. The court is ceremonial and cannot be lobbied by either side.
Closings follow a register: ordinary requests may use any approved expression of thanks, including Much obliged and Ever grateful; Cheers is accepted only in local scopes, while public library APIs require Yours faithfully. Compiler flags can tighten this under --deference=white-tie. Reports of misfortune and invitations to retire have their own approved valedictions.
Loops are permitted, though repeatedly asking the computer to do the same thing can try its patience. Returning carriageCount to 0 requires another apology; the loop then explicitly recognises the burden of repetition:
Dear Compiler,
If it causes you no undue hardship, might we trouble you to update the value
of carriageCount to 0?
Much obliged.

Dear Compiler,
Whilst it remains Quite True that carriageCount is strictly less than 3,
might we impose upon your patience to execute the following:
    Dear Output Console,
    Pray convey to the standard stream the value of carriageCount.
    Thank you.

    Dear Compiler,
    Would you mind terribly advancing carriageCount by the value 1?
    Cheers.
We are deeply indebted for your forbearance.
Functions as Diplomatic Proposals
A function does not seize control and return a value. It proposes a small, bounded collaboration:
To Whom It May Concern,
I hereby propose a diplomatic procedure designated calculateFare,
accepting as input:
    An Integer Number known as distanceInMiles,
    A Truth Value known as isFirstClass,
and ultimately returning An Integer Number.

May we respectfully undertake the following:
    Should it please the court to consider whether isFirstClass is Quite True,
        I humbly submit that the appropriate return value is distanceInMiles multiplied by 4.
    Or, should the contrary prove true,
        I humbly submit that the appropriate return value is distanceInMiles multiplied by 2.
    Thus concludes the matter.
Thus concluded.
Yours faithfully.
The verbosity has a practical advantage. Nobody has ever opened a Bespoke code review and complained that the function’s contract was unclear. They have complained that it was twelve pages long, but that is a separate metric.
Regrettable Circumstances
The phrase throw an exception is needlessly aggressive. In Bespoke, a component reports an awkward predicament and humbly raises it for gracious consideration:
Dear Host Environment,
I am dreadfully sorry to report an awkward predicament:
A Regrettable Circumstance designated LedgerMissingMisfortune has arisen,
specifically: "The parchment could not be located in the archives."
Might I humbly raise this for your gracious consideration?
With profound regret.
Nor does another component catch the poor thing. Contingency handling is a discreet attempt followed by a compassionate reception:
May we venture to attempt the following, with the greatest discretion:
    Dear Host Environment,
    Kindly inspect the ledger at "parchments/annual_audit.csv".
    Thank you kindly.
Should our modest enterprise regrettably miscarry,
and A Regrettable Circumstance designated LedgerMissingMisfortune be raised:
    Dear Output Console,
    Pray whisper to the standard error:
        "A dreadful pity; we shall brew fresh tea instead.".
    Much obliged.
In any eventual outcome, whether triumph or tragedy:
    Dear Host Environment,
    Would you be so exceptionally good as to restore the desk to an orderly state?
    Yours faithfully.
Thus concludes our contingency.
This is structurally equivalent to try, catch, and finally, but it gives the filesystem room to retain its dignity.
Better Icon and Label Alignment is a broad guide covering Table of contents, The icon in the markup, Icon as a pseudo-element, Outro. Later sections move through The Layout Maestro, Join my mailing list, with the page serving as a practical reference rather than a single-idea essay.
HTML has been gobbling up swathes of what used to be JavaScript’s remit. This page lists a bunch of dynamic functionality that the authors can now achieve with just HTML.
Jq is a great tool. the author use it frequently, but this recent article from Sequoia McDowell still has some great tips in it. Well worth a read. One thing that stood out to the author from this post was the snippet
If you don't know the shell, it's more difficult to tell a computer to do things.
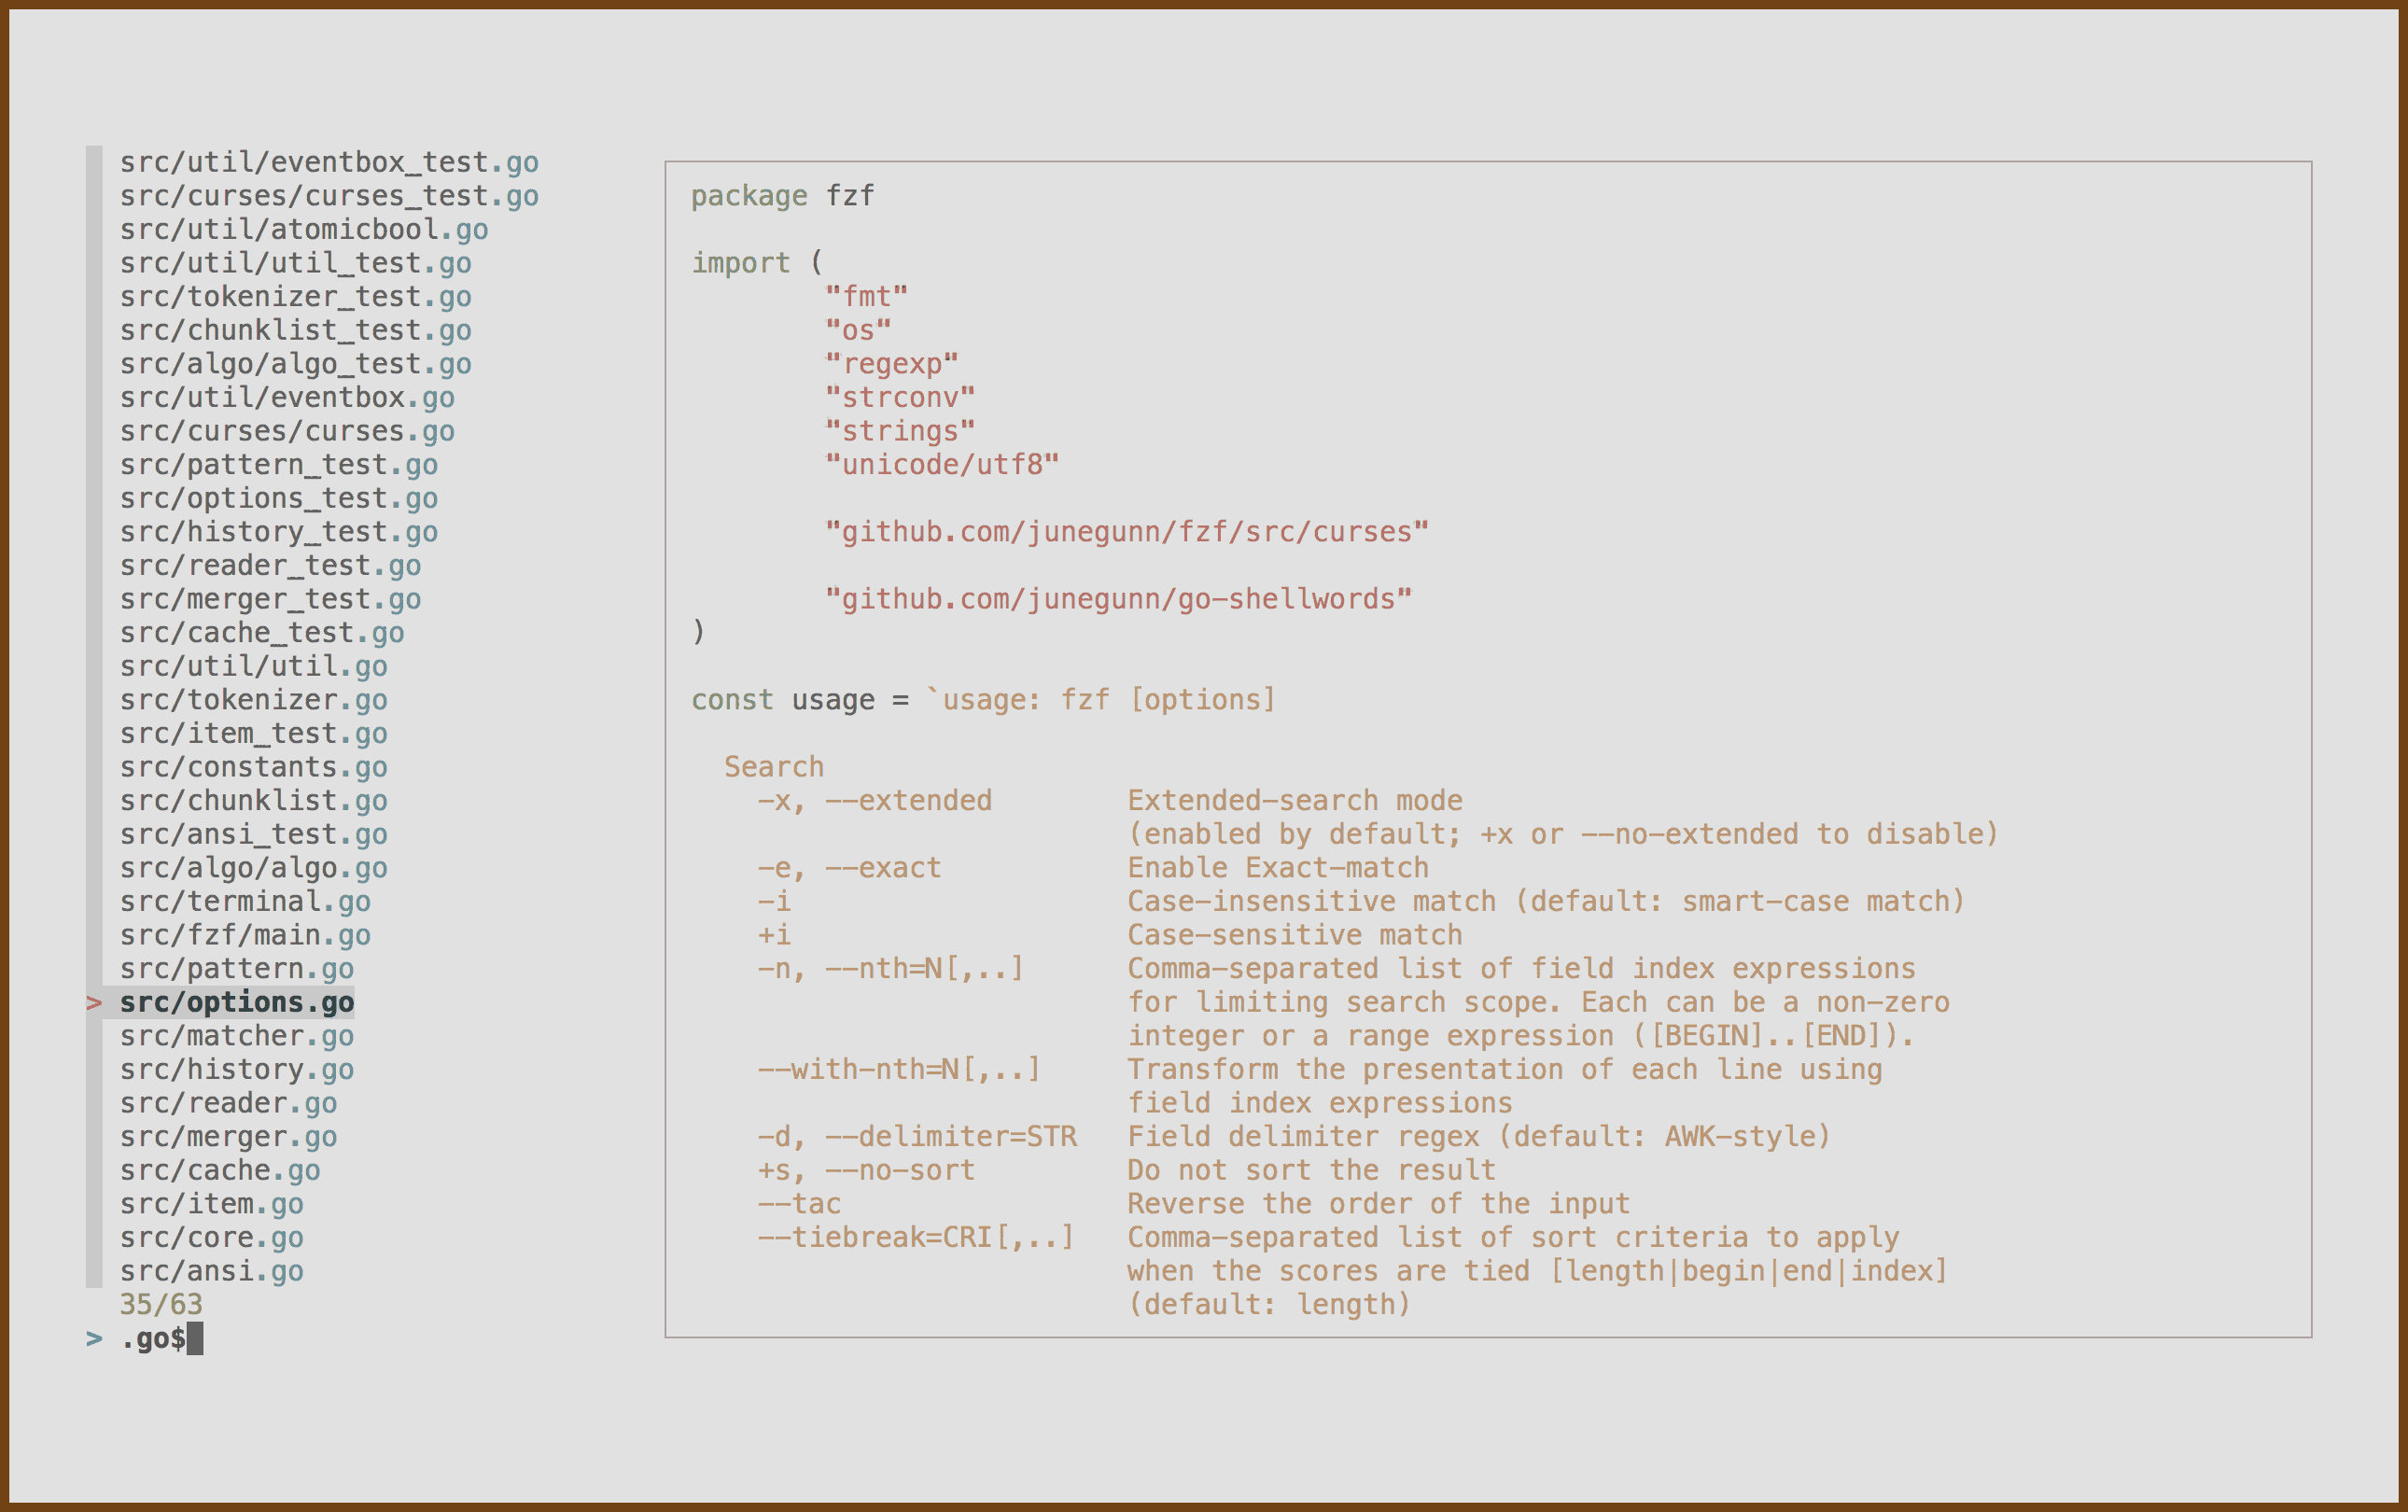
If you know fzf, you can build quick utilities with interactive fuzzy-searching. (Example: git checkout $(git branch --sort=-committerdate | fzf) will let you fuzzy-choose a branch.)
If you know tldr or eg, you can pull up usage examples for any other command in this list
If you know rsync, you can copy changed files on to a faster remote server to run something heavy and slow
If you know xargs, you can build up commands incrementally and parallelize work
If you know sed -i or ast-grep, you can quickly rewrite complicated patterns across a bunch of files
If you know direnv, you can make sure the right environment variables are set for everyone who runs commands in a codebase.
If you know duckdb, you can write SQL to query CSV and JSON files locally as part of a larger script.
If you know gh, you can build scripts to check on your PRs and open up new PRs from the cli.
If you know ngrok, you can quickly serve a local port to test something out on a different machine.
SSH port forwarding explained in a clean and visual way. How to use local and remote port forwarding. What sshd settings may need to be adjusted. How to memorize the right flags.
japanese verbs are awesome. you can take the dictionary form of a verb (for example, "taberu", to eat) and turn it into many forms: taberu ("eat"): tabemasu…
Part 2: Converting Pomera DM250 to Linux and Creating a Slack Bridge is a broad guide covering About This Article, What I Wanted to Create, What Was Created, Rough Specifications of pomelax. Later sections move through What I Did, Troubleshooting: Common Problems on the Pomera Side, Troubleshooting: Common Slack Problems, Distribution and Current Status, with the page serving as a practical reference rather than a single-idea essay.
Pomera DM250をLinux化してSlackブリッジを作成した話 前編 is a broad guide covering この記事について, 最終的に作ったもの, 動機:なぜ2年半放置したポメラを今さら改造するのか, 準備段階. Later sections move through 1発同期できるような仕組みが欲しい、ものぐさ, クラウドストレージでの運用案, テキストをSlackに貼り付ければよくね?, with the page serving as a practical reference rather than a single-idea essay.
You will not become a programmer by absorbing syntax from a crash course; the craft develops through years of deliberate practice. Build substantial programs, study other people's code, work with programmers both stronger and weaker than you, and learn languages from several paradigms so that each changes how you think. Keep stretching just beyond your current ability, seek feedback, and understand the machine beneath your abstractions.
Separate the accidental difficulties of tools and notation from the essential difficulty of constructing precise conceptual systems. Better languages, environments, and hardware can remove friction, but no single invention can erase the complexity, conformity, changeability, and invisibility inherent in software. Improve by buying rather than rebuilding, prototyping requirements, growing systems incrementally, and cultivating unusually strong designers.
Regard a program as the visible residue of a theory held by the people who built it: an understanding of how the problem, its constraints, and the chosen solution fit together. Source code and documentation alone cannot fully preserve that theory, which is why maintenance becomes brittle when no one who understands the original reasoning remains. Preserve software by transferring understanding through close collaboration, explanation, and continued participation—not merely by preserving artifacts.
Abstractions make routine work easier, but their underlying machinery still surfaces through failures, performance limits, and unusual cases. A network API may resemble a local call until latency or disconnection matters; a database may hide indexes until a query becomes slow. Learn at least one layer below the interface you use, because abstractions save labor without eliminating the knowledge needed to diagnose reality.
Resist replacing a mature codebase merely because the existing structure feels ugly. Every awkward line may encode a bug fix, performance lesson, or edge case accumulated through real use, and a rewrite silently discards that knowledge while freezing visible progress. Improve the system incrementally, preserving behavior as you reshape it, unless you can justify the exceptional cost and risk of starting over.
Attack complexity by reducing mutable state and the control logic that determines when state changes. Separate essential domain data and rules from accidental mechanisms, express derived values declaratively, and keep the remaining state visible and constrained. A functional core paired with a relational model makes behavior easier to understand because fewer facts depend on execution history.
Your choice of problem determines much of what your work can become, so look for questions that are both consequential and open to attack. Develop courage, tolerate ambiguity, protect sustained thinking time, and communicate results clearly enough that others can use them. Luck matters, but preparation, working conditions, persistence, and the choice of problem determine how often luck can help you.
Favor designs that are simple to implement, ship, and port when that simplicity lets a system spread and improve through use. A theoretically cleaner design can lose to one that places fewer demands on implementers, even when the latter compromises interface consistency or completeness. Judge elegance alongside adoption dynamics: a small, viable system can acquire quality, while an immaculate system that never propagates cannot.
Follow the chain of trust below source code and notice that every compiler, assembler, loader, and piece of microcode can influence the program you finally run. A compiler can learn to insert a backdoor into both a login program and future versions of itself, leaving no trace in the inspected source. Treat software assurance as a supply-chain and provenance problem, not something source review alone can settle.
A complex-system failure is rarely the work of one careless operator or one isolated root cause. Reconstruct the path through latent weaknesses, defenses, adaptations, and production pressures from what practitioners could see before the outcome was known. Strengthen the system's capacity to adapt and recover, remembering that people continuously create safety while operating an already imperfect system.
Spend novelty deliberately: every unfamiliar database, language, or framework adds operational unknowns and consumes a team's finite ability to learn. Prefer mature components whose limitations and failure modes are already understood, then introduce new technology only when it solves a problem the existing stack genuinely cannot. Count the interactions among choices as part of their cost, because complexity grows faster than the component list.
Protect your limited working memory from complexity, the predator that grows quietly as abstractions, distributed state, and clever machinery accumulate. Start with straightforward code, introduce abstractions only when repeated evidence earns them, and keep boundaries narrow enough to understand locally. Use tests, types, tools, and factoring as aids to comprehension rather than ceremonies that create more concepts than they remove.
A shared abstraction stops helping when it must serve several cases that change for different reasons. Restore the duplicated implementations, make each correct in isolation, and let the true common structure reveal itself over time. Duplication is cheaper than a false abstraction because it keeps future changes local and leaves you free to discover a better boundary.
Convert untrusted input into a type that carries the facts you have established instead of checking a weak value and then forgetting the result. Parsing moves failure to the system boundary and lets downstream functions accept only valid states, replacing defensive rechecks with stronger interfaces. Choose data structures that preserve evidence—such as a non-empty list rather than a list separately asserted to be non-empty—so correctness follows from construction.
Place a correctness function at the endpoints when only the application can know whether that function has truly succeeded. Lower layers may improve reliability or performance, but checks such as complete file transfer still require end-to-end verification because intermediate guarantees cannot cover every failure. Keep the shared substrate simple, and add lower-level mechanisms only when their broad performance benefit justifies the cost.
A remote interaction is not an ordinary local object call, however similar the interfaces appear. Latency, partial failure, concurrency, memory access, and object lifetime make distribution a semantic boundary that applications must confront explicitly. Design interfaces around coarse-grained communication and failure-aware behavior, because pretending location is transparent produces systems that are fragile in precisely the cases that matter.
Divide a system around design decisions likely to change, hiding each decision behind a stable interface. A pipeline-shaped decomposition that mirrors processing steps may look orderly yet force many modules to know the same representation details. Encapsulate secrets such as storage layout and algorithm choice so teams can work independently, changes remain localized, and readers can understand one module without reconstructing the whole system.
Accept that software can exceed the unaided mind's capacity long before it exceeds the computer's. Control that gap through languages, proofs, and structures that let you reason about behavior in compact, composable units instead of relying on testing and cleverness alone. Approach programming with humility: simplify the intellectual task until correctness becomes tractable.
A computation is easiest to reason about when its progress remains aligned with the structure of its text. Unrestricted jumps create arbitrary execution coordinates, forcing a reader to reconstruct history before understanding the current state. Prefer control constructs with constrained entry and exit points so program behavior remains accessible to reasoning and proof.
Treat higher-order functions and lazy evaluation as mechanisms for modularity, not ornamental language features. Higher-order functions separate reusable patterns of computation, while laziness lets producers and consumers be composed without committing to an execution schedule or intermediate structure. Build programs from independently useful pieces whose combination creates new behavior without reopening their implementations.
Recognize the economic and organizational forces that turn systems into sprawling structures of expedient patches, blurred boundaries, and shared state. Such systems persist because local fixes meet immediate needs, architectural knowledge is scarce, and wholesale reconstruction is risky. Preserve habitable regions through continuous refactoring, clear boundaries, and reconstruction in small areas, while treating decay as a pressure to manage rather than a moral failure.
CAP becomes more useful when you replace 'pick two' with decisions tied to particular operations, data, and moments in a partition. Consistency and availability are spectra, and a system may detect a partition, limit the affected work, trade one property temporarily, and recover explicitly afterward. Design the normal and partitioned modes together, including how state converges once communication returns.
Build large distributed applications around independently transactional entities that exchange messages rather than around one global transaction. Once data crosses an entity boundary, accept uncertainty, duplicate delivery, delayed knowledge, and the need for idempotent or compensating behavior. Record durable histories and make business rules tolerate tentative outcomes, because coordination at scale resembles agreements among organizations more than updates inside one database.
Stop treating globally shared, synchronously updated state as the natural foundation of scalable systems. Data observed across distance is inevitably delayed and may be contradictory, so build on stable identifiers, immutable versions, local transactions, and explicit rules for interpreting incomplete knowledge. Make uncertainty part of the data model rather than hiding it behind an interface that promises a single instantaneous truth.
Cheap storage and computation make immutable facts a practical foundation for systems whose current views are derived from history. Append-only logs, snapshots, versioned datasets, copy-on-write structures, and idempotent computation reduce coordination and make retries, replication, and parallel processing safer. Separate semantic immutability from physical representation so you can reorganize data for efficient reads without changing what it means.
Model a stream of changes as an ordered, append-only log, then let consumers maintain their own materialized views by replaying it. The same abstraction explains database commit logs, replication, change capture, messaging, and stream processing, turning data integration into controlled propagation of state transitions. Preserve ordering and position so systems can recover, bootstrap new consumers, and reason about the relationship between historical facts and current state.
Demand a competent single-threaded baseline before celebrating a system's scale-out graph. Compute the configuration that first beats that baseline—the COST, or configuration that outperforms a single thread—because parallel frameworks can spend enormous resources recovering overhead they introduced themselves. Optimize useful work and elapsed time, not merely the ability to occupy more machines.
When a request fans out across many components, even a rare slow response becomes likely to delay the whole result. Reduce variability within services, then use cross-request techniques such as hedged requests, backup work, and latency-aware partitioning to keep outliers from dominating user experience. Apply redundancy selectively so tail improvement does not create uncontrolled extra load.
Expect automation to remove routine practice while leaving the human responsible for rare situations requiring the deepest skill. If operators only monitor a reliable system, their attention fades and their ability to diagnose unfamiliar failures decays precisely when intervention becomes necessary. Design automation to keep people informed, practiced, and able to form an accurate model of the process—not merely available as a last-resort component.
Read the Therac-25 accidents as a systems failure spanning unsafe software, reused assumptions, weak interfaces, inadequate testing, poor incident communication, and misplaced confidence in software reliability. Do not infer safety from the absence of hardware interlocks or from the rarity of reproduced failures; specify hazards and enforce independent defenses. Treat operators' reports as evidence and share incident knowledge promptly, because safety depends on the organization surrounding the code as much as on the code itself.
Build reliability by making every change explicit, reviewed, and traceable. The Shuttle team controlled requirements, kept detailed records, used independent verification, and preferred proven code to unnecessary novelty. Measure the process and study every defect so dependable behavior follows from repeatable engineering rather than individual heroics.
A well-structured monolith gives a new domain room to reveal its boundaries before distribution makes those boundaries expensive to change. Microservices amplify the cost of a mistaken split through remote communication, deployment coordination, and data ownership, while in-process modules are easier to move as understanding develops. Extract services only after experience reveals stable boundaries and the operational benefits outweigh distribution's premium.
Distinguish external quality, which users can observe, from internal quality, which determines how safely and quickly you can change the product. Cutting internal quality may appear faster briefly, but accumulated friction soon raises the cost of every feature and defect repair, reversing the apparent tradeoff. Keep the codebase healthy as an economic investment in future delivery speed, not as an aesthetic indulgence.
Distinguish state-based tests that inspect results from behavior-based tests that set expectations on collaborators; mocks are not merely convenient stubs. A classical style uses real collaborators when practical and substitutes only awkward dependencies, while a mockist style isolates each object and specifies its outgoing interactions. Choose deliberately, because the testing style pushes design toward different collaboration patterns, coupling, and refactoring behavior.
Microservices are an organizational and operational architecture, not merely a collection of small processes. Build independently deployable services around business capabilities, give product teams responsibility for running them, and keep intelligence at the endpoints rather than in elaborate transport infrastructure. Accept the price explicitly: remote calls, distributed data, eventual consistency, and failure-aware automation demand capabilities that a monolith may not require.
Shape your automated test suite as a pyramid: keep a broad base of fast, focused unit tests, add a thinner service-level layer, and reserve relatively few end-to-end UI tests for behavior that genuinely crosses the whole system. A top-heavy suite runs slowly, fails ambiguously, and becomes expensive to maintain. Use the proportions as a heuristic rather than a quota, optimizing for rapid feedback and clear diagnosis.
Examine test-driven development as a collection of design and feedback practices rather than a ceremony that must be defended whole. Ask whether isolated tests, mocks, and a test-first rhythm improve your particular design, and notice when they instead couple tests to implementation or distort architecture. Keep the discipline of short feedback loops while remaining willing to change the technique when its costs exceed its signal.
Twelve concrete questions can expose whether a software team has the basic engineering infrastructure needed to work well. Check source control, one-step builds, daily builds, defect tracking, schedules, specifications, working conditions, tools, testing, usability, and hiring. The score is deliberately crude, but fixing the gaps it reveals removes recurring friction before you reach for elaborate process reforms.
Preserve forward motion when the work feels uncertain, political, or dull: writing code, fixing defects, and shipping small improvements keeps a team’s initiative alive. Competitors and distractions can pin you down by consuming attention even when they do not produce anything better. Turn intimidating projects into the next concrete action and let consistent progress compound.
Learn what string operations and memory access cost beneath the conveniences of a high-level language. A seemingly innocent abstraction can conceal repeated scans or copies, turning straightforward code into an accidental quadratic algorithm. Reason from data representation and operation count first, then choose abstractions with a clear view of the work they perform.
Text is not a bag of bytes whose meaning can be guessed later. Distinguish characters from code points and encoded byte sequences, understand what Unicode and UTF-8 each specify, and carry encoding metadata across every boundary. Decode input deliberately, work with a defined character model internally, and encode explicitly on output so text is not silently corrupted.
Notice how a language’s async model can split otherwise similar functions into incompatible “colors,” forcing the distinction through every caller in the stack. Colored functions are harder to compose because one kind cannot freely call the other, and the burden spreads across APIs rather than staying at the operation that waits. Prefer runtimes and abstractions that hide scheduling mechanics without hiding latency or failure.
Abandon the idea that C is portable assembly for contemporary processors. Its abstract machine omits capabilities modern hardware needs to express—parallelism, rich memory behavior, and provenance among them—while aggressive compilers exploit undefined behavior in ways that break machine-level intuition. Choose a language and intermediate representation that can communicate your intended semantics to both the optimizer and the hardware.
Modern processors often spend more time waiting for data than computing on it, which makes the memory hierarchy part of your design. Understand caches, cache lines, associativity, prefetching, write behavior, NUMA placement, and contention well enough to predict when access patterns will stall. Measure with hardware-aware tools, organize data for locality, and reduce needless movement before tuning arithmetic.
Read a C structure as a layout contract shaped by member sizes, alignment rules, and padding, not merely as a list of fields. Reordering members can sharply reduce memory consumption when millions of instances amplify a few wasted bytes. Verify the ABI and compiler rules you actually target, and use explicit packing only when its portability and access penalties are understood.
Treat floating-point numbers as finite approximations governed by precise rounding rules, not as slightly unreliable real numbers. Learn to reason in relative error and ulps, recognize cancellation and exceptional values, and understand the guarantees supplied by IEEE arithmetic. Reformulate unstable calculations and specify rounding behavior when numerical reproducibility or correctness matters.
A simple action becomes difficult to follow when a design forces it through a ceremonial hierarchy of classes. Turning verbs into noun-heavy command objects, factories, and visitors scatters the operation across excessive structure. Give behavior first-class representation and introduce objects where identity, state, and substitution genuinely earn them.
Make the easiest path through an API the one that produces correct, secure, and maintainable behavior. Documentation and discipline cannot compensate for interfaces whose defaults invite misuse or whose dangerous operations look ordinary. Move invariants into the design so callers succeed by following the obvious route and must work deliberately to escape it.
Begin with direct code that expresses the cases you actually understand, even when that creates duplication. Watch repeated semantics emerge, then compress them into an abstraction that has a stable meaning rather than merely a similar textual shape. Delay generalization until the examples teach you the right boundary, because premature compression stores incorrect assumptions in a form that is harder to undo.
A programming environment can teach by making the program's behavior visible while the learner constructs it. Show values, control flow, time, and relationships; connect code to its output immediately; and let the learner manipulate concrete examples before requiring symbolic prediction. Simplified syntax and motivational games are not substitutes for a medium that supports a correct mental model of computation.
Design information software first as a medium that helps a person understand and decide, not as a collection of controls. Infer context where possible, present relevant relationships clearly, and spend interaction only where the user must genuinely supply information or express intent. Treat graphic design as the organization of meaning, then add manipulation with the same care you would add complexity to a program.
Let a web layout respond to its viewing context instead of assuming a fixed canvas. Combine fluid grids, flexible media, and media queries so proportions and hierarchy survive across widths without maintaining a separate design for every device. Start from relationships among elements, test where those relationships break, and introduce breakpoints around the content rather than around fashionable screen sizes.
The web does not behave like a fixed printed page: readers bring different windows, fonts, devices, preferences, and constraints. Rigid pixel control turns that ordinary variability into failure. Specify enough structure to preserve meaning, then allow the browser and reader to negotiate the final presentation.
Design a URI to outlive the server, framework, file format, and organizational chart that first produced it. Put durable concepts—not implementation details—into public identifiers, and maintain redirects when infrastructure must change. Every broken address transfers your internal migration cost to readers, citations, indexes, and archives that cannot coordinate with you.
Work with the web’s native grain: a fluid vertical flow of text, links, and containers that can adapt across contexts. Begin from the smallest coherent expression, let layout grow from the content, and use frameworks or visual polish only after the relationships are sound. The browser is not an inferior page-composition tool; its flexibility is the material you are designing with.
Page weight and complexity are product decisions with human costs, not harmless implementation details that future bandwidth will erase. A simple document should not require megabytes of scripts, surveillance machinery, and fragile dependencies merely to place text on a screen. Set explicit performance budgets, remove work that does not serve the reader, and make the useful content arrive first.
Design for a mature, constrained web rather than an endlessly accelerating technological future. Hardware, bandwidth, attention, and social tolerance encounter limits, while supposedly obsolete protocols and interfaces persist because they are useful and widely embedded. Build accessible, durable, participatory systems, and ask what human purpose a novelty serves before making the world adapt to it.
Build online systems around human limits: people forget, change, make mistakes, and need private spaces that do not become permanent dossiers. Advertising-funded surveillance and centralized data collection turn ordinary behavior into durable institutional power while offering users little meaningful consent or recourse. Minimize retained data, preserve room for anonymity and forgetting, and make business incentives answer to the people living inside the system.
Faster hardware has not prevented software from becoming slower, larger, and less reliable. Layers of dependencies, background work, and indifferent craftsmanship consume memory, battery, bandwidth, and human attention without proportionate value. Measure responsiveness from the user's machine, reduce the stack you ask them to carry, and treat efficiency as part of correctness.
Model names as user-provided, culturally contingent data rather than as a universal first-name/last-name tuple. People may have one name, many names, changing names, punctuation, unfamiliar scripts, or forms that exceed your chosen length and ordering rules. Store what the domain truly requires, preserve the user’s representation, and avoid validation that encodes your local custom as a law of identity.
Clocks jump, drift, disagree, repeat values, and obey political rules rather than tidy arithmetic. Durations, civil timestamps, time zones, and monotonic ordering are different concepts and should not share an accidental representation. Use monotonic clocks for elapsed time, carry zone context for human schedules, and test the discontinuities your ordinary day conceals.
Accept that production software is assembled atop incomplete knowledge, mutable requirements, leaky abstractions, and systems no one fully understands. Small changes can awaken interactions far beyond their apparent scope, while success often means maintaining a fragile truce among historical constraints. Keep designs comprehensible, investigate failures without pretending the system is simple, and leave the next programmer enough context to continue.
Put a user’s primary copy of data on their own device and make the network an aid to collaboration rather than a gate to basic work. Preserve offline availability, fast local interaction, multi-device synchronization, long-term access, privacy, and user control while using conflict-free replicated data types where concurrent edits must merge. Judge cloud architecture by whether people retain agency when the service is slow, discontinued, or unwilling to cooperate.
At sufficient scale, every observable API behavior becomes somebody's dependency, whether or not you documented or intended it. Performance, error text, ordering, timing, and quirks can harden into de facto contracts. Limit what consumers can observe, measure real usage before changing behavior, and plan migrations as compatibility work rather than assuming the specification defines the whole interface.
Select engineering practices for the mechanisms and evidence that make them effective, not for their resemblance to what successful organizations do. Process becomes cargo cult when a team copies visible rituals while ignoring context, feedback, and the causal work underneath them. Form hypotheses about quality and productivity, measure the outcome, and revise the practice when reality disagrees.
Stop framing quality and delivery speed as automatic opposites. Defects create rework, destabilize schedules, and grow more expensive as they travel downstream, so disciplined prevention and early removal usually shorten the path to release. Invest in practices that expose mistakes close to their source, then use defect and rework data to find the quality level that supports sustained throughput.
Seniority shows up in judgment under uncertainty, not in tenure or the volume of code produced. Build shared context, explain tradeoffs, ask questions that expose hidden assumptions, and help the team recover when systems and plans fail. Exercise influence without needing authority, keep technical depth connected to business consequences, and make the people around you more capable.
Notice the coordination, onboarding, review, and gap-filling work that makes a technical team effective even though it produces little visible code. Choose that work deliberately: make its impact legible, share genuinely non-promotable tasks fairly, and keep enough of your evaluated craft in your workload to grow toward the career you actually want. If you manage others, do not let glowing feedback conceal a widening gap between what someone contributes and what your promotion system rewards.
Staff engineering is not one uniform job. You may guide a team as a Tech Lead, steward a durable technical domain as an Architect, resolve high-stakes ambiguity as a Solver, or extend an executive's reach as a Right Hand. Identify which form of leadership the organization actually needs, then choose work that fits both that need and the way you create leverage.
Treat management as a change of profession, not a promotion or a permanent departure from engineering. Move between the two tracks when the work calls you: management teaches conflict, motivation, and business context, while hands-on engineering renews the technical judgment and credibility that decay away from the code. Do each role fully rather than attempting both at once, since people and difficult technical problems each require sustained attention.
Protect creative work in half-day blocks, because an hour is often only enough time to load a difficult problem into your head. A meeting that looks like one cheap calendar slot to a manager can split a maker's day into unusable fragments and suppress ambitious work before it begins. Cluster appointments into office hours or the edges of the day so coordination remains possible without repeatedly throwing exceptions through someone's concentration.
Employers buy reduced costs, increased revenue, and managed risk—not programming as an identity. Frame your work around those business outcomes, and learn how companies hire, budget, negotiate, and value line-of-business software even when the technical work looks ordinary from inside the profession. Build communication and commercial judgment alongside coding skill so other people can recognize the leverage you already produce.
Negotiate compensation as a consequential business conversation, not as a referendum on your worth or gratitude. Preserve information and optionality: avoid naming the first number, keep multiple opportunities alive, and evaluate the complete offer only after the employer has decided it wants you. Ask calmly for an improvement backed by the value and alternatives you bring; a short uncomfortable exchange can outweigh years of routine raises.
Choose technology for the advantage it gives the product, even when conventional employers would reject it as unusual. A more expressive language can compress implementation, expose better abstractions, and let a small team test ideas faster, while competitors may not recognize the advantage because their own tools constrain what they can imagine. Keep the strategic language choice close to the people who understand both the code and the business rather than reducing it to a standardized hiring decision.
Programming often behaves more like a maker's craft than a process of executing a complete specification. Begin with a working sketch, learn from the artifact, and revise toward a form you could not fully predict in advance. Let language, tools, and taste expand the designs you can think, while preserving enough autonomy and contact with users for iterative discovery to happen.
Train your taste by studying why your earlier choices were worse, not by declaring every preference equally good. Seek designs that are simple, durable, fitted to the real problem, open to recombination, and easy to revise; apparent effortlessness usually arrives only after exacting iteration. Pay attention when expertise makes a tolerated convention look ugly, because that discomfort can identify work worth improving.
Look for problems you know firsthand instead of brainstorming products that merely sound like startups. Start with a small group that urgently needs a solution you can build, choosing a narrow, deep well of demand over a broad audience that feels mild hypothetical interest. Put yourself near a changing frontier, notice what is newly missing, and let a real need pull the company into existence.
Early-stage work often has to be done by hand before you know what deserves to scale. Recruit users manually, give them an unexpectedly attentive experience, and perform whatever the immature product cannot yet automate. That effort teaches you what users need, creates the first momentum for growth, and reveals which processes deserve machinery later.
Define a startup by its pursuit of rapid growth, not by age, size, funding, or the use of fashionable technology. Choose a large reachable market, measure a meaningful growth rate every week, and let that constraint force decisions about product, hiring, and financing. Once growth becomes the compass, many debates become concrete: choose the action most likely to move the rate without destroying the foundations that sustain it.
Examine ideas you reflexively avoid because they involve sales, operations, regulation, payments, or other tedious work. That reluctance is shared by other capable builders, so the unpleasant execution may be the barrier protecting a valuable opportunity rather than evidence that the idea is bad. Separate a truly intractable business from a merely unappealing schlep, then decide whether the avoided work is precisely where you can create leverage.
The more tightly a belief is attached to your identity, the harder it becomes to examine honestly. Disagreement then feels like an attack, and inquiry becomes socially dangerous for everyone involved. Keep your identity small and your ideas available for revision so you can follow an argument past tribal boundaries without having to defend yourself along with the claim.
Guard the problem that occupies your mind when your attention is free, because background thought continues working on it long after you leave the desk. Money disputes, status anxiety, and other unresolved concerns can silently displace the question you most want your best thinking to advance. Audit what appears in quiet moments and change your circumstances when the wrong concern has become cognitively expensive.
Great work usually starts with curiosity strong enough to carry you to a field's frontier. Look for a problem that is important, tractable, and genuinely interesting to you; ambition supplies direction, but sustained interest provides the energy for years of learning and revision. Produce often, seek excellent peers, preserve morale through setbacks, and let discoveries redirect the plan instead of demanding a straight path from the beginning.
Distinguish avoiding all work from postponing a smaller obligation because a harder, more important problem has taken hold of you. Significant work often requires long, apparently unproductive stretches and a willingness to disappoint the endless errands that present themselves as urgent. Ask what you are protecting by procrastinating, then arrange your life so the answer can be a consequential project rather than mere escape.
Create conditions in which exceptional programmers can spend their ability on the product instead of fighting weak tools, office politics, and arbitrary process. Give them hard problems, strong colleagues, autonomy over implementation, and a language expressive enough to keep ideas close to code. Do not confuse credentials, age, or conformity with ability; judge hackers by what they can make and by the clarity of the thinking embedded in it.
Hard work lasts when genuine interest, a worthy aim, and an honest sense of your best effort reinforce one another. Push toward the edge of your capacity while protecting health and the curiosity that makes sustained effort possible, then calibrate yourself against people doing excellent work. Discipline matters most when it keeps you returning to the problem through uncertainty, not when it merely lengthens the visible workday.
Practice politeness as an operational discipline: answer people, arrive when you said you would, remember names, apologize cleanly, and make ordinary interactions easier than they might have been. Assume that other people carry contexts you cannot see, and leave them room to recover from awkwardness or error without turning every lapse into a verdict. Courtesy will not resolve every conflict, but it reduces needless friction and keeps repeated relationships workable.
Give people something concrete to take home: organize a lecture around one memorable point, write for readers rather than prestige, and use clear exposition to discover whether you understand your own subject. Protect time for sustained work, learn the useful tricks of your profession without mistaking them for depth, and treat reputation as the accumulation of what others can reliably associate with you. Choose which obligations to neglect consciously, because a serious intellectual life cannot optimize everything at once.
Leadership requires enough distance from messages, institutional incentives, and other people's finished opinions to form a thought of your own. It means more than executing assigned goals well; you must decide which goals matter, defend a new direction, and resist the conformity that bureaucracies reward. Develop that independence through concentration, reflective conversation, and solitary work that lets your first conventional answer mature into judgment.
Design AI methods to benefit from increasing computation rather than encoding ever more of your own domain knowledge. Across games, speech, and vision, handcrafted insight produced attractive short-term gains but eventually plateaued behind general search and learning methods that scaled. Build mechanisms that can discover useful structure for themselves, because the world's complexity is too open-ended to be captured as a fixed inventory of human-designed features.
Treat software as the operating core of industries that once regarded it as a support function. Falling computing costs, broad connectivity, and a large population of capable developers let software-native companies reach customers and reorganize markets from books and music to logistics, finance, and energy. Evaluate incumbents by whether they can become software organizations quickly enough, not merely by whether they have purchased modern systems.
The browser's built-in APIs can carry a small application farther than framework-first habits suggest. Event listeners, DOM methods, URL state, forms, and a little CSS support useful interactive tools with code that remains easy to inspect and change. Add dependencies when they solve a demonstrated problem, not before you have tested how far the platform itself can carry the design.
Remove decisions that do not help the user accomplish the task. Every option forces someone to understand a distinction, predict a consequence, and accept responsibility for choosing, so configurability carries a cognitive cost even when implementation is cheap. Select strong defaults, infer what the program can know, and reserve explicit choices for differences that users genuinely understand and care about.
Regard a compatibility workaround as protection for the person who owns broken software, not as a new API contract for that software to exploit. The platform may detect an old program and emulate earlier behavior so a customer can keep working, but depending on the shim converts a temporary rescue into deliberate fragility. Program to documented behavior and let compatibility layers remain an implementation detail that can disappear when the original need does.
Code can be easier to reason about when its execution and state changes read locally from top to bottom. Splitting that story into one-use helpers may scatter mutable dependencies across a file, although function boundaries remain valuable when they create strong contracts. Move separable logic toward pure functions and single-assignment values; purity improves reasoning even when the surrounding system cannot be purely functional.
Measure before optimizing, because the expensive path is rarely where intuition first places it. Keep algorithms and data structures simple until evidence shows that scale demands something clever, then measure again rather than trusting the elegance of the optimization. Invest most heavily in representing and organizing the data well: once the structure is right, the necessary algorithms often become obvious.
Build a computing environment from a small set of concepts applied consistently: everything is an object, computation happens through messages, and each component owns the interpretation of its state. Preserve a live, inspectable system in which users can understand and change the tools they use rather than being separated from them by fixed applications. Favor a simple, uniform kernel that can describe itself and grow through composition over a large language full of special cases.
Recoverable environmental failures and bugs that violate program invariants need different treatment. Make expected errors visible in types and signatures so callers must confront them, while failing fast on corrupted state instead of pretending execution can safely continue. Design the language, runtime, contracts, and diagnostics together: error handling shapes control flow and reliability too deeply to be repaired by adding exceptions after the rest of the system is settled.
Treat structured programming as a method for making control flow provable and comprehensible, not as a lexical ban on goto. Choose constructs according to the reasoning they permit and the performance the problem actually needs; some well-disciplined jumps express exits, state machines, or optimized inner loops more clearly than contorted alternatives. Replace slogans with measured analysis, preserving structure while allowing carefully justified exceptions.
Follow Smalltalk's development as an iterative search for a personal dynamic medium, not merely the invention of an object-oriented language. Objects, messages, late binding, graphical interfaces, networks, and children's learning experiments evolved together because the system was repeatedly rebuilt around a compact generative idea. Design ambitious systems by protecting the principles that let them grow, while remaining willing to replace implementations that no longer serve the larger vision.
Individual speedups from AI don't turn into faster shipping because the real bottlenecks — review, coordination, decisions — sit outside your editor. Local optimization runs straight into the system's actual constraint.
Erik Dietrich's classic on why teams stagnate. An “expert beginner” stops improving early, mistakes tenure for mastery, and entrenches — and because they set the local standards, the whole group calcifies around their ceiling.
On the cost of winning arguments that change no one's mind. The author's shift from debating to disengaging is framed as reclaimed attention rather than defeat — pick the arguments that actually move something.
A guide to asking questions that actually get answered: show what you tried, state the goal, and make it cheap for someone to help you. Better questions get better and faster help — and respect people's time.
Reliability is multiplicative. A step that works 98% of the time sounds excellent until you chain twenty of them and the whole pipeline fails more often than it succeeds. A short, sharp argument about why “nearly always” rarely is.
A tour of capable built-in Emacs features people reach for packages to replace — completion, project handling, window management — that already ship in the box. The theme: learn what's included before installing over it.
Release notes for Magit 4.6, the Git porcelain for Emacs. Worth skimming for the new commands and workflow changes if you drive Git from inside the editor.
Rebuilds the original Quake with a period-accurate 1997 DOS toolchain — Watcom C, DOS4GW — to show what shipping a game looked like before modern build systems. The interesting part is the friction: fixed memory models, segmented pointers, and a compiler whose optimizer you had to hand-hold.
The node's link fields live inside the element itself instead of in a separate container node — the Linux kernel list_head style. One fewer allocation per insert, better cache locality, and an element can belong to several lists at once. The tradeoff is that the structure and its storage are now coupled.
A small C library collecting intrusive lists and trees ready to drop into a project, companion code to the intrusive-structures write-up. Useful as a reference for the container_of trick and how the macros hide the pointer arithmetic.
Removes the unpredictable branch from quicksort's partition step. Instead of an if that the CPU keeps mispredicting on random data, it computes both outcomes and selects with a conditional move, trading a few extra instructions for a big drop in branch-misprediction stalls.
A full playable Klondike solitaire for the terminal in about 5 KB of C, from Óscar Toledo, who is known for extremely compact programs. Worth reading as an exercise in how much game fits into very little code when you drop every abstraction.
Matt Mahoney's book-length reference on lossless compression, from information theory and entropy through arithmetic coding, context mixing, and the PAQ family that has topped compression benchmarks. Dense but self-contained; a good single source for how modern compressors actually model data.
Karpathy's micrograd — a tiny scalar autograd engine and neural net — rewritten in C. Small enough to read end to end, which makes backpropagation concrete: every value is a node in a graph, and gradients flow backward through it.
How Fil-C — a memory-safe implementation of C and C++ — handles context switching without breaking its safety guarantees. Coroutine and thread switches move the stack out from under running code, exactly the kind of operation a naive safety scheme forbids; this explains how it stays sound.
Why serious editors don't store text as one big array. Compares gap buffers, ropes, and the piece table — the append-only original plus a list of pieces pointing into original and added buffers — which gives cheap edits and near-free undo. The structure VS Code settled on, and why.
Applies data-oriented design to parsing: lay tokens out as struct-of-arrays, keep hot fields packed for the cache, and shape the loops so the branch predictor and prefetcher can keep up. The point is that parser speed is mostly a memory-layout problem, not a clever-algorithm problem.
GTK carries its own C implementation of timsort — the adaptive merge sort that exploits existing runs of ordered data. Reading production timsort shows the parts the textbook description skips: run detection, galloping merges, and the delicate invariant that bounds the merge stack.
A counter to the idea that AI coding means shipping low-quality code fast. Lawson argues LLMs are just as effective at writing high-quality code slowly: use them to find bugs — throw enough passes at a codebase and they surface plenty — then spend your effort prioritizing and validating rather than typing. His trick is running several different models over the same change so hallucinated or bogus findings cancel out.
The hard part of software was never typing the code — it was building an accurate model of the domain in your head first. Before shipping a payroll system you had to understand garnishments and pre-tax deductions; before a transit app, what a GTFS feed is and why a bus that's “on time” can still be wrong. The code was a transcription of that understanding, and that understanding is what AI doesn't hand you for free.
As more debugging, writing, and code comes from AI, a new etiquette question appears: when is it OK to forward AI output to another human to read? The argument — if you're asking for someone's attention, show that you put in human effort first.
Alan Perlis's “Epigrams in Programming” — 130-odd sharp, quotable one-liners (“A language that doesn't affect the way you think about programming is not worth knowing”). Durable aphorisms worth rereading every so often.
The Outbox pattern guarantees reliable publishing; the Inbox pattern covers the consumer side, ensuring each incoming message is processed exactly once even when the broker retries or delivers duplicates. Walks through an implementation in .NET with MassTransit and PostgreSQL: the inbox schema, the consumer, and the background processor.
The people who built the effects for Terminator 2 tell the story in their own words — ILM artists, Cameron's team, and the crew behind the T-1000. The film had roughly 50 effects shots, a number Eric Enderton contrasts with today: “today you can't get out of bed for less than 300 shots.” The liquid-metal morphs, the chrome man walking out of fire, the digital body doubles — all done when the tools barely existed and much of the pipeline was invented on the show. A first-hand record of the moment computer graphics crossed into believable, photoreal character work.
How Google's internal developer tooling evolved from a fragmented set of editors toward a shared, browser-based Cloud IDE. A firsthand look at what editing code at that scale demands and why the ecosystem kept splintering before it consolidated.
Wordle implemented in under 200 lines of C — small enough to read in one sitting, with a few advanced options. A tidy example of how little code the game actually needs.
A blunt postmortem of porting a hand-written C game engine (bgfx, SDL2, miniaudio, cimgui) to the web via Emscripten. A numbered list of every non-obvious problem hit along the way — starting with being forced back to Visual Studio because the author's debugger doesn't support 32-bit processes. Practical, pain-saving notes for anyone shipping C to WASM.
A modern C standard library delivered as a single header, sp.h, bundling the utilities C leaves out. The examples go as far as a small ls implementation to show the library in real use.
Simple Dynamic Strings: antirez's small, widely-copied C string library (the one from Redis). Its trick is storing the length in a header that sits before the character pointer, so SDS strings stay compatible with plain C string functions while gaining O(1) length and safe growth. The README lays out the design and its tradeoffs.
A working list of the non-standard behaviors and compiler/library gaps you hit writing “portable” C, collected while building a C compiler. Concrete friction points across glibc, SDL, OpenBSD libc, and bionic show how rarely real-world code is actually pure ISO C.
A retrospective on LLVM by its creators, Vikram Adve and Chris Lattner, tracing the project from NSF-funded research in 2000 to code that now runs on billions of devices. Covers its major innovations, its external impact, and where the infrastructure is still heading — and doubles as a case for federal funding of basic research.
A minimal C compiler written in C for learning — lexer, parser, AST, and interpreter — small enough to read end to end and understand how each stage feeds the next.
A hands-on introduction to Zig through annotated examples, in the spirit of Go by Example. It leans on the language's focus on robustness and simplicity — no hidden control flow, no hidden allocations, no preprocessor. Readable online or straight from the repo.
A collection of small, useful bookmarklets for web development and browsing, with drag-to-install buttons and a copy option for mobile. Includes handy ones like viewing a page's reference anchors or its source.
A small React app that renders Mermaid diagrams with far nicer styling than the defaults — paste diagram source and get a clean, presentable result ready to drop into a doc or slide.
An agentic “skills” framework and development methodology for Claude: a structured library of reusable skills plus a workflow for applying them. Includes a quickstart and an explanation of how the skills compose into a repeatable process.
RSS never actually died — it quietly powered podcasting for a decade — and now AI agents need exactly what it provides: a clean, structured, pollable feed of content. A short argument that the old format is unexpectedly well-suited to the agent era.
FeedFlow is a minimalist cross-platform RSS reader (Android, iOS, macOS, Windows, Linux) built with Kotlin Multiplatform, Jetpack Compose, and SwiftUI. A clean, single-codebase example of a modern KMP app as much as a usable reader.
Google's official RSS Subscription Extension for Chrome: adds one-click feed subscription to the toolbar and previews feeds in the browser. Rated 4.0★ across ~3.5K reviews.
A roundup of six free RSS readers for 2026 — Feedly, Inoreader, NewsBlur, and others — compared on what each does well. A reasonable starting point if you're picking a reader.
Feedbro is a browser-extension RSS/Atom/RDF reader (Chrome, Edge, Brave, Vivaldi, Firefox) with a built-in rule engine for filtering and auto-tagging feeds — handy for following many sources without drowning in them.
A small browser extension that detects RSS/Atom feeds on the page you're viewing so you can subscribe quickly. Installable from source in developer mode.
FracturedJson formats JSON for human scanning without wasting vertical space. Small arrays and objects can stay on one line, repeated structures can align like a table, and larger data still breaks into readable blocks.
It is a good reminder that pretty-printing is an interface design problem. The best layout depends on shape, repetition, and the task a human is doing with the data.
A bookmarklet is still one of the lowest-friction ways to carry a tiny browser tool around. This collection keeps the idea visible: page inspection, DOM manipulation, quick formatting, and small utilities can live in the bookmarks bar without an extension build pipeline.
Several bookmarklet lists were saved in the export; this one is kept as the representative developer-focused collection.
ticket stores project work items in git and runs as a single Bash script. The appeal is not enterprise workflow coverage; it is keeping issues, dependencies, priorities, and history close to the repository with almost no service dependency.
This kind of tool is useful for small teams, solo projects, and environments where the source repository is the most durable coordination surface.
git-bug turns bug tracking into data that travels with the repository. Issues can be created and edited offline, synchronized through git remotes, and bridged to external trackers when needed.
The long-lived idea is distributed project state: not every coordination artifact has to live in a central web app.
opencode is an open-source coding agent with enough activity and surface area to be worth saving as a reference point. Even if the agent landscape changes quickly, the repository shows what users expect from a local coding agent: sessions, tools, model plumbing, editing, and review loops.
The project is time-sensitive, but the design pressure is durable: coding agents are becoming developer tools, not just chat boxes.
superdiff focuses on making differences readable across structured data, text, coordinates, streams, and files. It is useful when a normal line diff hides the semantic shape of the change.
Good diffs reduce review cost. A diff tool that understands structure can make data changes inspectable without requiring a custom viewer for every format.
CG/SQL lets developers write stored procedures in a T-SQL-like language and compile them into C or Lua code that uses SQLite's C API. It also handles schema evolution and test generation.
The interesting part is the boundary: SQLite stays embedded and portable, while complex database logic gets a higher-level authoring model and generated low-level code.
Podroid packages an Alpine-based Linux environment into a rootless Android app, with support for containers and GUI desktop applications. It turns a phone or tablet into a surprisingly serious Linux playground.
The project is worth saving as a reference for mobile development environments, Android virtualization boundaries, and the continuing pull of Unix tools onto every device people carry.
SQLite's argument for C is concrete: performance, compatibility, low dependency load, and long-term stability. A small embedded database library has to run almost everywhere and remain callable from almost everything.
The page is also a useful antidote to language monoculture. Safety and abstraction matter, but SQLite's constraints include ABI durability, toolchain reach, and decades of integration surface.
This guide compares physical machines, virtual machines, containers, process sandboxes, and language virtual environments as points on the same isolation spectrum.
The useful framing is that containers are not magic portability boxes. They are one layer in a stack of kernel features, filesystem assumptions, process boundaries, and operational tradeoffs.
Arena allocation groups many allocations under one lifetime and frees them all at once. That can remove bookkeeping, reduce fragmentation, and make ownership easier to reason about when the program's phases are clear.
The tradeoff is discipline: arenas are powerful when lifetimes are simple and dangerous when long-lived references leak across phase boundaries.
Type systems verify properties of programs, but production correctness belongs to the whole deployed system. Rolling deploys, old messages, multiple live versions, queues, migrations, and operational recovery all sit outside the neat boundary of a single build.
The durable lesson is that local reasoning is necessary but not sufficient. The unit that fails in production is often a fleet, a protocol, a migration path, or a historical message format.
Clang's -fbounds-safety adds bounds annotations and checked pointer types to C while preserving interoperability with existing C code. The model is incremental: safer pointer defaults and annotations where the compiler needs more information.
This is worth saving because it shows one plausible path for improving C safety without pretending the C ecosystem can be rewritten all at once.
canvas_ity is a tiny single-header C++ rasterizer modeled on the basic HTML5 2D canvas API. It prioritizes portability and immediate-mode drawing over a large rendering stack.
Small graphics libraries are useful references because the whole system can fit in one reader's head: paths, transforms, fills, strokes, rasterization, and demos without a framework.
The benchmark compares C++ hash map implementations across insert, erase, lookup, iteration, memory, and reference-stability scenarios. The valuable part is the benchmark shape as much as the ranking.
Hash table performance is workload-specific. This is best read as a map of tradeoffs and measurement pitfalls, not as a permanent answer to which container is fastest.
The critique argues that std::simd misses many patterns real performance code needs, especially when width choices, compile times, and expressiveness matter. The practical recommendation is still to use intrinsics for hard parts and let the auto-vectorizer handle the easy parts.
Whether or not every conclusion holds for every workload, the post is useful because it names the abstraction mismatch: standard-library portability can become too narrow for the code that actually needs SIMD.
Pop-up blocking used to be a visible browser victory over abusive advertising. The modern loophole is user activation: once a click or tap occurs, pages can often open windows again in flows that feel legitimate to the browser but hostile to the user.
The lesson is broader than pop-ups. Browser protections are only as strong as their interaction model, and attackers adapt to whatever action counts as consent.
WASM-ImageMagick brings ImageMagick into the browser through WebAssembly. It is useful both as a tool and as a concrete example of a large native library exposed to web code.
The project is a good reference for the rough edges of serious WebAssembly ports: compiled dependencies, sample UIs, API wrappers, and the difference between a demo and a usable browser-side utility.
This shader note builds a smoke effect in three.js from texture sampling, UV mapping, masks, remapping, edge work, twist, and animation. The value is in the staged construction rather than a final copy-paste fragment.
Visual shader tutorials are easiest to remember when the screenshot carries the effect and the text explains the mechanism.
WebAssembly was sold as a web revolution, but its durable value is more specific: portable sandboxed execution, compilation targets, embeddability, and performance-sensitive modules in systems that can tolerate its boundaries.
The piece is useful because it separates hype from deployment reality. WebAssembly did not become a replacement for JavaScript applications, but it did become infrastructure in places where a safe portable binary target matters.
Modern HTML features such as details, datalists, dialogs, popovers, and richer form controls behave unevenly in text-based browsers. The result is a practical audit of how much of the web still works when graphics and JavaScript are not the interface.
Text browsers are a useful pressure test. If essential content disappears there, the page may also be fragile for search, automation, low-bandwidth use, and assistive workflows.
Andy Pavlo's database review is a point-in-time map of what mattered in 2025: PostgreSQL's continuing gravity, database vendors attaching MCP surfaces, licensing fights, and the recurring tension between new systems and operational reality.
The post is most useful as context. It preserves what the database world looked like at the turn of 2026, not as a permanent ranking of winners.
This PostgreSQL index guide starts from how data sits on disk and moves into why indexes speed reads while costing disk, writes, planner complexity, and memory.
The useful part is the tradeoff framing across index types: B-tree, hash, BRIN, GIN, GiST, and SP-GiST are not interchangeable optimizations. Each encodes assumptions about access patterns and data shape.
This note implements semantic search in SQLite with binary embeddings and Hamming distance, then combines it with FTS5 keyword search through reciprocal rank fusion.
The result is a useful middle ground: hybrid search without running a separate vector database. The limits are clear too; O(n) scans can be acceptable at some scales and wrong at others.
pgdog sits in front of PostgreSQL as a connection pooler, load balancer, and sharding layer. It is worth saving because the project makes several operational concerns explicit: routing, resharding, auth, replication state, and client compatibility.
PostgreSQL scaling tools are most interesting when they show the boundary between a single-node database and a distributed operational system.
This guide explains the mistakes beginners make with video files: confusing containers with codecs, re-encoding when a remux would do, throwing away quality, and using tools without understanding what they change.
The durable distinction is simple: a container is how streams are packaged, while a codec is how audio or video streams are encoded. Editing workflows go wrong when those layers are treated as the same thing.
FFmpeg-over-IP connects clients to remote FFmpeg servers, making heavyweight media work run somewhere other than the local machine. It keeps the familiar FFmpeg command shape while moving execution across the network.
The project is useful as a pattern: wrap a known command-line tool with remote execution while preserving enough of its interface that existing habits still apply.
lazycut is a terminal UI for trimming video, built around quick preview and FFmpeg-backed cuts. It fits the common job where opening a full editor is too much ceremony.
Focused media tools age well when they make one operation faster without hiding the underlying files and commands.
This is a practical defense of plain C for solo game projects: reliability, control, portability, fast builds, and a small enough language surface to keep the whole program understandable.
The interesting part is not language nostalgia. It is the fit between a tool and a creator's constraints: small games, long-lived source, few dependencies, and a preference for debugging one's own code.
Noel Berry lays out a 2025 game-making stack without a commercial engine: programming language choices, rendering, input, audio, assets, level editing, UI, porting, and platform support.
The durable idea is that an engine is a bundle of decisions. Small games can sometimes move faster by choosing narrower libraries and owning the integration work directly.
Haunted Paper Toys is a collection of printable models: houses, coffins, a cemetery, board games, monsters, and other small paper constructions.
It is worth keeping for the web-archive feeling as much as the objects themselves: a personal site offering strange, handmade, printable things with no platform ceremony.
This was a conversation between Daniel Terhorst-North and Gojko Adzic about spec-driven development, AI coding agents, and the practical limits of using large language models in software delivery. They contrasted naive one-shot specification generation with a more useful iterative approach based on feedback, tests, review, and evolving understanding. The discussion moved from the risks of unreadable generated specs and vendor-driven frameworks to stronger ideas: turning stable project rules into automated checks, using agents to build guardrails, treating each agent session like onboarding a new developer, and applying AI mainly where it improves feedback loops, developer workflow, and non-core support tasks. The central theme was that humans must remain responsible for meaning, judgment, and domain understanding, while machines are most valuable when they help make feedback faster, clearer, and more reliable.
Ideas
Treat spec-driven development as useful only when it is iterative. The strong idea is not "write a perfect spec, then generate the product." The strong idea is "use a spec as a living object that gets refined through feedback, tests, examples, and implementation."
Do not let generated specs become unreadable documents. The failure mode is a machine producing the same kind of 500-page artifact that nobody reads. The useful filter is whether the spec helps people make decisions faster and more accurately.
Agents are not compilers. A compiler gives deterministic transformation. An agent gives probabilistic assistance. Any workflow that assumes reliable translation from prose to product is fragile.
Move stable rules out of prompts and into deterministic tools. If a rule matters and repeats often, turn it into a linter, hook, test, CLI check, CI rule, or pre-commit guard. Prompts are weak memory. Tools are stronger feedback.
Use AI to create the guardrails, not only to drive inside them. One of the best ideas is asking the agent to write custom rules that constrain future work: ESLint rules, test helpers, validation scripts, grep checks, and project-specific checks.
Write error messages for agents and humans. A weak error says what failed. A strong error says what failed and what to do next. This matters because agents may loop on vague failures, while specific repair instructions improve both automation and human onboarding.
Think of every agent session as onboarding a new developer. If the same knowledge must be explained repeatedly, it should not live in someone's head or a markdown essay. It should become fast feedback inside the system.
Separate domain judgment from deterministic support work. AI may not be the right tool for core business decisions, but it can be excellent for setup, cleanup, test data loading, static analysis, scaffolding, impact analysis, and other surrounding work.
Use AI for quality-of-life engineering. The best near-term value may come from small things developers never had time to build: scripts, checks, loaders, review helpers, prototypes, reports, and workflow shortcuts.
Automation does not make work better by itself. It makes work faster and more repeatable. If the rule is wrong, automation repeats the wrong thing faster. So automate only when the rule is stable enough.
Start with markdown, but do not stay there. Markdown can help discover and discuss rules. Once a rule proves valuable and stable, convert it into executable feedback.
Generic AI frameworks are sourdough starters. They are not recipes to follow exactly. Their value is as a beginning that should be reduced, modified, and adapted to the team's real process.
Look for repeated friction. The best automation targets are places where the team or agent keeps hitting the same problem. Repetition is a signal that the rule or workflow should be externalized.
Keep implementation loops small enough to review. A useful agent workflow might change only a few files at a time, generate visible checkpoints, and allow fast inspection through diffs or static prototypes.
Use research-plan-implement as a flexible mental model. First understand the code and context. Then plan the impact and constraints. Then implement in small observable steps.
The agent should not own the process. The team should own the process, and the agent should be shaped to fit it. Using a vendor framework unchanged means adopting someone else's assumptions.
The most interesting shift is from "AI writes code" to "AI helps build a better engineering environment." The deeper value is not generated output alone, but faster creation of tests, checks, feedback loops, and local development tools.
Raymi Klingers is an engineering director at Forgotten Empires, the studio that has worked on modern Age of Empires releases and remasters. His talk, Age of Empires: 25+ years of pathfinding problems with C++, was presented at Meeting C++ 2025. The official slides are available here: [25+ Years of Pathfinding Problems with C++](https://meetingcpp.com/mcpp/slides/2025/25%2B Years of Pathfinding Problems442903.pdf). His public profile also lists him as a lead engineer at Forgotten Empires: Raymi Klingers on LinkedIn. One older Forgotten Empires credits page lists him under artificial intelligence work for Age of Mythology: Tale of the Dragon: Forgotten Empires credits.
The talk is about maintaining a very old commercial game codebase where technical behavior, player memory, legacy bugs, and competitive gameplay are all connected. The core issue is that pathfinding in Age of Empires is both hated and loved by the community, so changing it too much can make the game technically better but emotionally or competitively wrong.
Pathfinding means finding a route from one point to another while avoiding obstacles.
Klingers explains that he worked on many of the legacy reboots and a little on Age of Empires IV. He focuses mostly on Age of Empires II and uses "legacy" to mean the original releases from around 1999, while "reboots" means the later remakes and remasters.
The first major problem is community feedback. Most pathfinding feedback is negative, but not all negative feedback is equally useful. A vague complaint like "pathfinding is bad" gives little information, while a comparison to legacy behavior or to a previous patch can identify a regression. The best report is a replay with a timestamp, because the game simulation is deterministic and can reproduce the exact situation.
Deterministic means the same inputs produce the same result every time.
Age of Empires pathfinding is hard because the game does not take the easy route. Units bump into each other, stop, repath, and try to move around blockers. They do not push other units, and they usually cannot overlap. Formations make this more complicated because friendly units in a formation can overlap in limited ways, creating a second movement system that must cooperate with normal unit movement.
The maps also make the problem harder. They are random, dynamic, and can change during a match as players build towns, place buildings, cut through forests, and create new obstructions. The game is partly grid based because buildings and terrain obstructions align to tiles, but units themselves are not locked to the grid.
Low-level unprivileged sandboxing tool used by Flatpak and similar projects
Many container runtime tools like systemd-nspawn, docker, etc. focus on providing infrastructure for system administrators and orchestration tools (e.g. Kubernetes) to run containers.
These tools are not suitable to give to unprivileged users, because it is trivial to turn such access into a fully privileged root shell on the host.
The app has a WebView for opening external links. Every time a page loads in this WebView, the app injects a JavaScript snippet. I found it in the Hermes bytecode string table:
It forces body { overflow: auto !important } to re-enable scrolling on pages where consent dialogs lock the scroll. Then it sets up a MutationObserver to continuously nuke any consent elements that get dynamically added.
An official United States government app is injecting CSS and JavaScript into third-party websites to strip away their cookie consent dialogs, GDPR banners, login gates, and paywalls.
I’m releasing Manyana, a project which I believe presents a coherent vision for the future of version control — and a compelling case for building it.
It’s based on the fundamentally sound approach of using CRDTs for version control, which is long overdue but hasn’t happened yet because of subtle UX issues. A CRDT merge always succeeds by definition, so there are no conflicts in the traditional sense — the key insight is that changes should be flagged as conflicting when they touch each other, giving you informative conflict presentation on top of a system which never actually fails. This project works that out.
A systems-heavy k-means paper that treats clustering as an online GPU primitive rather than offline preprocessing and focuses on why standard implementations waste time on memory traffic and atomic contention instead of actual compute. It introduces flash-kmeans, with one kernel that avoids materializing the full distance matrix and another that replaces scatter-style centroid updates with sorted segment reductions, then backs that up with kernel design details, performance breakdowns, and large-scale benchmarks against cuML, FAISS, and other baselines. Worth reading if you care about GPU dataflow, IO-aware kernel design, or exact k-means that can scale to production-sized AI workloads without giving up mathematical correctness.
The article steps back from modern LLMs and shows how a simple Markov chain can power autocomplete and tiny text generation. It explains how to count word-to-word transitions, turn them into next-word probabilities, and use those to suggest or generate text. It also shows why greedy choices become repetitive and how adding randomness helps. The piece is a practical primer on building a tiny, understandable language model from scratch.
Cuckoo hashing can outperform traditional SIMD-accelerated hash tables when carefully engineered. Unlike quadratic probing, which checks sequential slots and suffers from branch mispredictions, cuckoo hashing uses two hash functions and probes at most two fixed SIMD groups. This allows a fully branchless lookup with predictable memory access patterns. The result is faster lookups for in-cache tables due to fewer branches and competitive performance for out-of-cache tables when bucket sizes and memory layouts are tuned. Benchmarks show cuckoo hashing matches or exceeds the performance of Swiss Tables and Meta’s F14 designs, especially at high load factors.
I started a reading group in 2021, a few months after joining Microsoft as a new grad on the Azure Databases team. The group was initially focused on database internals, which was my favorite subject at UW. Databases touch so many areas of CS: compiler construction in the query engine, memory management with the buffer pool, storage systems, algorithms, networking. It's almost a microcosm of the whole field. There's also plenty of active research and conferences, like SIGMOD and VLDB, so it never gets old.
How it started
My day job is on the backend distributed storage engine for Cosmos DB, so I spend most of my time thinking about LSM-trees, B-trees, and distributed systems. When I joined Microsoft, I wanted to find other people who were curious about these topics beyond what their immediate work required.
The first paper we read was Algorithms Behind Modern Storage Systems. A handful of people showed up. The format was simple: everyone reads the paper on their own, we meet for an hour, and we talk through it. Pretty informal, just a conversation about the paper.
From there we went through a mix of database internals classics and systems papers:
That was basically the format for the first couple of years. Someone would suggest a paper, we'd vote on it, and then we'd meet and discuss. We also had a side channel where people shared engineering blog posts and talks that caught their attention. That informal sharing turned out to be just as valuable as the readings.
There are a lot of different practices, but there are some common characteristics between them:
They're very detailed. Each thing you're working on is recorded. Your hypothesis or goal is recorded. It's detailed enough that someone else could come along and replicate the steps.
They are dated. Each entry is provided with a date, so you can trace back when things happened.
They're done in real-time. Rather than recording information after a project is finished, notes are written as it progresses.
They create permanent records. Notes are written without erasing old notes, going forward in an append-only fashion. No pages are removed or modified.
They're the original record. This is where things get recorded first, instead of being copied into from other sources.
The level of detail is a particularly crucial bit, because, for your notes to be useful to yourself later? They have to be useful to someone else, too. Future you is someone else: you won't remember everything. So you have to assume you'll forget much of it.
A shared belief in the mission can cause a small group of people to prioritize good software over their individual benefit, for a little while. But thousands of engineers can’t do that for decades. Past a certain point of scale, companies must depend on the strength of their systems.
But there’s a line. Past a certain point, working on efficiency-related stuff instead of your actual projects will get you punished, not rewarded. To go over that line requires someone willing to sacrifice their own career progression in the name of good engineering. In other words, it requires a hero.
it’s important for engineers to pay attention to their actual rewards. Promotions, bonuses and raises are the hard currency of software companies. Giving those out shows what the company really values. Predators don’t control those things (if they did, they wouldn’t be predators). As a substitute, they attempt to appeal to a hero’s internal compulsion to be useful or to clean up inefficiencies.
I have been building a product end to end with frontier models and coding agents, and I have been filtering hard for what consistently works.
Since December 2025, these tools got meaningfully better. The practical consequence is not a new style of writing code, but a shift in where the effort goes.
"Automated programming" describes it better than casual labels. Repetitive production work is getting automated, while the human work stays focused on direction.
Automated programming means machines produce most routine code while a person decides what should exist and why.
The job is still architecture, trade offs, product decisions, and edge cases. What is disappearing is the manual labor of typing and assembling everything by hand.
The value shows up when the environment is clean and deliberately set up. Experience matters because you can inspect outputs, fix them, and adjust the setup so it behaves correctly next time.
This makes it easy to build small, purpose built tools on demand. That is where speed compounds.
A large part of modern stacks is middle work: frameworks, libraries, and tooling that add layers without reducing meaningful complexity, especially in web, mobile, and desktop development.
Middle work is extra layers you maintain mainly to satisfy tooling, not to improve the product.
Frameworks tend to solve three things. One is "simplification", which often means avoiding first principles design and force fitting your product into someone else's structure.
Another is automation of boilerplate. This used to justify heavy dependencies, but the new tools make boilerplate cheap without adopting a full ecosystem.
The third is labor cost. Standard stacks let companies hire narrow operators instead of engineers, because the decisions are already made by vendors and framework authors.
Operating is following a predefined system; engineering is choosing the system based on goals and constraints.
If you keep using big stacks, you pay obvious costs like maintenance churn and vulnerability updates. You also pay a larger hidden cost: constrained design choices that shape what you build and how you think.
Design constraint is when tools quietly limit the options you can realistically choose.
Agents are strongest with long lived tools. Bash is a good example: it is stable, widely understood, and works as a universal adapter between an agent and a real system.
A universal adapter is a tool that connects many different tasks through one reliable interface.
The opportunity now is to remove useless complexity and keep only the complexity that belongs to the product. Solve the problem you actually have, add complexity only when it arrives, and build systems that are genuinely yours.
Estimates do not help engineering teams deliver work more efficiently. Many of the most productive years of my career were spent on teams that did no estimation at all: we were either working on projects that had to be done no matter what, and so didn’t really need an estimate, or on projects that would deliver a constant drip of value as we went, so we could just keep going indefinitely.
In a very real sense, estimates aren’t even made by engineers at all. If an engineering team comes up with a long estimate for a project that some VP really wants, they will be pressured into lowering it (or some other, more compliant engineering team will be handed the work). If the estimate on an undesirable project - or a project that’s intended to “hold space” for future unplanned work - is too short, the team will often be encouraged to increase it, or their manager will just add a 30% buffer.
Many systems implement soft delete by keeping rows and marking them as removed, often with a boolean flag or an archived timestamp, so users can undo mistakes and teams can satisfy audit or compliance needs.
Soft delete means data is hidden instead of being permanently removed.
A timestamp-based approach pushes complexity into day-to-day work because most archived rows are never read, yet they stay mixed in with active rows.
Keeping old rows in the main tables creates growing piles of dead data that may stay unnoticed for a long time, especially if no cleanup process was planned from the start.
A retention period is how long deleted data is kept before being permanently removed.
Even if storage is cheap, large amounts of dead data can make restores slower, so rebuilding a database from backups can take much longer than expected.
Filtering out archived rows complicates queries, indexes, and application code, and increases the risk of accidentally including inactive rows in results, especially when join tables are involved.
Schema and data migrations also have to account for years of inactive rows, and backfills or data fixes can become risky or hard to reason about when old records may not match current expectations.
Restoring a deleted row is often not just flipping a column, because the original creation may have touched external systems, so restoration logic can become a fragile, partial reimplementation of the normal creation pathway.
A practical improvement is to require restores to go through the same APIs used for creation, which simplifies the server and ensures restored data must pass current validation rules.
Instead of mixing inactive and active rows, archived data can be stored separately, such as in an archive table, a different database, or object storage, which keeps the main system focused on current data.
One application-level pattern is to emit an event when a record is deleted, push it through a queue, and have a separate service store a serialized copy in object storage along with any related data.
This event-driven archiving can simplify the primary database and make deletion workflows more reliable by moving slow external cleanup into asynchronous processing, and it can store data in a layout that is easier for applications to work with than raw table rows.
The tradeoff is that bugs in the deletion or archiving code can lose archived records and require manual cleanup, and the added services and queue increase operational surface area.
Storing archived objects in object storage can also make them hard to search, so customer support may need extra tools to find what to restore.
A database-trigger approach can copy a row into a dedicated archive table before deletion, often storing the deleted row as a JSON blob along with metadata like table name and archived time.
When deletes cascade through foreign keys, it can be useful to record why each row was removed, such as by tracking the root deletion in a session variable so archived child rows point back to the original cause.
Trigger-based archiving adds some overhead to deletes and grows the archive table, but it keeps live tables free of dead rows, reduces query and index complexity, and makes it easy to purge old archives with a simple time-based condition.
If the archive grows large, it can be separated physically or managed with time-based partitioning, while the main tables remain small and backups stay faster because they do not include archived rows.
Another option is WAL-based change data capture, where tools read the database change log, filter for DELETE events, and write deleted records to external storage without modifying application code or adding triggers.
Change data capture is a way to copy database changes to another system as they happen.
In PostgreSQL, the write-ahead log records every change, and systems like Debezium can read logical replication streams and publish them to pipelines that eventually store archived deletes in places like object storage, search indexes, or other databases.
The write-ahead log is a record of database changes used for durability and replication.
This approach shifts the main burden to operations, because you must run and monitor extra infrastructure, and lighter-weight tools reduce the stack but move reliability and recovery concerns into your own code.
A key risk is WAL buildup when consumers fall behind, since replication slots can force the primary to retain WAL segments, so misconfiguration or outages can fill disk and threaten database stability.
PostgreSQL can limit how much WAL a slot is allowed to hold so the primary is protected, but falling too far behind can invalidate the slot and force a resync from a fresh snapshot, which means monitoring lag is essential.
WAL-based CDC is attractive when you already run the required infrastructure or need to stream changes to multiple destinations, but it requires careful coordination for schema changes and adds meaningful debugging and deployment complexity.
A speculative alternative is keeping a replica that does not apply deletes, or one that converts deletes into an archived marker, which could make old data easy to query but raises open questions about tracking deletion times, separating active from removed rows, and long-term migration behavior.
Running such a replica could also be expensive and operationally heavy, since it must store everything indefinitely and still be managed like a production database component.
If starting fresh and needing recoverable deletes, the preferred choice here is the trigger-based archive table because it is straightforward, keeps active tables clean, stays queryable when needed, and avoids introducing a large supporting infrastructure.
M-DISC: The article treats BD-R M-DISC as the best archival candidate. It notes the marketing claim of 1000 years lifetime and states that accelerated aging tests neither prove nor disprove the claim.
Recommended selection and operating policy (decision-oriented): For minimizing long-term risk, the author ranks BD-R M-DISC first and BD-R HTL second. The author explicitly says it is unclear whether BD-RE is better than BD-R LTH, so if you cannot confidently avoid LTH, use both BD-RE and BD-R (diversity as a hedge). For media geometry, the author prefers single-layer 25 GB BD as a safer bet because there is less to go wrong than with multi-layer discs.
Recommended retention strategy with concrete parameters: Do not assume a single burn remains readable for decades. Keep at least 2 copies, preferably 3. Use different disc types and/or different storage for the copies, and keep copies in different physical locations to mitigate correlated risks (fire/flood, and also temperature and relative humidity). Re-check readability about once per decade and refresh copies when in doubt. The author would like per-disc error-level scanning at burn time, but notes this is generally not available in practice.
A practical FFmpeg guide for developers working with the C libraries. It explains how libavformat and libavcodec fit together and builds that into a small video player example that opens a media file, reads stream data, decodes frames, and shows how the pieces connect in example code. Worth reading if you want a clear mental model of the FFmpeg pipeline and a concrete example you can build on.
We already did our experiments with using NSA software to hack a classic Atari game. This time we want to focus on a much more practical task — using AI agents for malware detection. We partnered with Michał “Redford” Kowalczyk, reverse engineering expert from Dragon Sector, known for finding malicious code in Polish trains, to create a benchmark of finding backdoors in binary executables, without access to source code.
We started with several open-source projects: lighttpd (a C web server), dnsmasq (a C DNS/DHCP server), Dropbear (a C SSH server), and Sozu (a Rust load balancer). Then, we manually injected backdoors. For example, we hid a mechanism for an attacker to execute commands via an undocumented HTTP header.
Important caveat: All backdoors in this benchmark are artificially injected for testing. We do not claim these projects have real vulnerabilities; they are legitimate open-source software that we modified in controlled ways.
Current LLMs lack this high-level intuition. Instead of prioritizing high-risk areas, they often decompile random functions or grep for obvious keywords like system() or exec(). When simple heuristics fail, models frequently hallucinate or give up entirely.
TL;DR: Over the past decade, I’ve worked to build the perfect family dashboard system for our home, called Timeframe. Combining calendar, weather, and smart home data, it’s become an important part of our daily lives.
PyTorch is currently one of the most popular deep learning frameworks. It is an open-source library built upon the Torch Library (it's no longer in active development), and it was developed by Meta AI (previously Facebook AI). It is now part of the Linux Foundation.
LosslessCut is a desktop GUI tool for fast, lossless video and audio edits by cutting and copying streams directly (FFmpeg-style), so common trims take seconds and do not degrade quality via re-encoding.
It supports lossless trimming/cutting, lossless merge/concatenation when codec parameters match, and lossless stream editing to combine tracks across files. It can extract tracks, remux to compatible containers, take full-resolution JPEG/PNG snapshots, apply preview timecode offsets, and change rotation/orientation metadata. It includes a timeline with zoom and frame/keyframe jumping, thumbnails and waveform, segment labeling, autosaved segment projects, CSV import/export for EDL-style cut lists, and visibility into the last FFmpeg command/log for CLI reruns
The workflow I’m going to describe has one core principle: never let Claude write code until you’ve reviewed and approved a written plan. This separation of planning and execution is the single most important thing I do. It prevents wasted effort, keeps me in control of architecture decisions, and produces significantly better results with minimal token usage than jumping straight to code.
The last month was a whirlwind, never would I have expected that my playground project would create such waves. The internet got weird again, and it’s been incredibly fun to see how my work inspired so many people around the world.
~ ~ ~
When I started exploring AI, my goal was to have fun and inspire people. And here we are, the lobster is taking over the world. My next mission is to build an agent that even my mum can use. That’ll need a much broader change, a lot more thought on how to do it safely, and access to the very latest models and research.
Warcraft III Peon Voice Notifications for Claude Code
Stop babysitting your terminal
Your Peon pings you the instant Claude Code finishes or needs permission. Never lose flow to a silent terminal again — and your workspace sounds like Orgrimmar.
Richard Campbell hosts long-running podcasts and uses a case-study lens on AI: what people have actually shipped, what is in production, and what is working.
The talk began in 2017 during work tied to the Vatican, helping socially minded companies scale practical solutions like low-cost solar lanterns to replace kerosene, while navigating whether they should be for-profit or charitable.
History matters because the current moment makes more sense when the origins are clear.
The term artificial intelligence was coined in 1955 by Marvin Minsky and others as a persuasive label to secure US military funding.
Artificial intelligence: a broad label for computer systems that seem to do human-like thinking tasks.
Early AI work produced logistics software that helped the US military operate globally, and that lineage still matters even as the systems have modernized.
In the 1960s, ELIZA showed that a simple chatbot could keep people engaged for hours, mostly by reflecting their words back, exposing how easily humans attribute mind to machines.
Humans are wired to project agency and faces onto the world, a survival trait that once helped detect threats quickly and still drives pareidolia in everyday life.
Pareidolia: seeing meaningful patterns, like faces, where none were intended.
That instinct becomes dangerous when applied to modern systems, because it invites people to assign capabilities the tools do not have.
Public imagination was shaped early by 2001: A Space Odyssey, where a computer becomes a central character and tries to kill the crew, setting a lasting cultural pattern repeated by later stories like Terminator and Ultron.
The field moved in waves: AI winters when money dried up, then new surges like robotics, decision trees, Deep Blue, and Watson, each producing useful results but also clear limitations.
AI winter: a period when hype collapses, funding drops, and progress slows.
The current wave traces to Geoffrey Hinton, who argued decades ago that deeper neural networks with backpropagation could do remarkable work, but computing power was too weak at the time.
"Neural net" is a metaphor: these are mathematical models running on data, not real neurons.
ImageNet in the early 2010s became a turning point. With millions of labeled images, deep models suddenly jumped accuracy so far that image recognition began to look solved compared to what came before.
A pattern follows: when something works, it stops being called AI and gets a more specific name like image recognition or language modeling.
Language modeling advanced in parallel, including work that became Siri, which worked well for many users but struggled with accents and has not improved smoothly over time.
Google gathered elite researchers into efforts like Google Brain, intensifying concern among famous tech figures that powerful systems were being built behind closed doors and should be developed more openly.
OpenAI formed as a response, aiming to pull talent into an organization framed as working for everyone, but it remained cash-constrained and its openness story did not match how it operated.
The early goal was a universal translator, using tokenization so language could be represented in a way that generalized across languages. That path led to transformer models that could continue text chains and generate new text.
GPT-2 showed the basic behavior of producing plausible text from prompts, while model sizes were constrained partly by the cost of running the larger versions.
Around 2019, Microsoft leadership looked for compute-heavy workloads to drive Azure growth. OpenAI fit perfectly: invest cash, then recoup it through massive cloud compute usage.
OpenAI restructured into a capped-profit model, making it easier to raise money and scale training runs.
A 2020 "scaling laws" paper argued that training on more data and scaling compute keeps improving model performance, pushing against the older machine learning fear of overfitting.
Overfitting: performing well on training data but failing on new, unseen data.
That message justified pouring in more money and compute, helping enable GPT-3, an enormous training effort on Azure that was impressive in scale but uneven in quality.
GitHub used GPT-3 for Copilot, a product boosted by the vast corpus of public code and by the fact that programming languages are more structured than human language. "Copilot" matters because it implies the human remains responsible.
OpenAI still needed better outputs, so it paid workers to rank multiple answers, building training data to tune behavior.
When cash pressure returned, the public became the training engine. ChatGPT launched in November 2022, and adoption exploded to 100 million users in about two months, creating severe scaling stress for Azure teams.
That surge fit the Gartner hype cycle: a trigger event drives hype to inflated expectations, then reality forces disappointment, and only later does practical value stabilize.
Gartner hype cycle: a common boom-crash-stabilize pattern for new technologies.
The dotcom era is the template: the Netscape IPO pulled in huge investment from people who barely understood the internet, then the bust wiped out many firms while leaving behind infrastructure like fiber and data centers that society kept using.
Microsoft moved fast after ChatGPT, plugging models into Bing and sending an internal mandate to integrate OpenAI APIs across products, producing a flood of copilots and forcing teams to learn by building.
Microsoft then invested more and trained larger models, including GPT-4 and multimodal versions, while competitors accelerated and geopolitics entered the race.
China signaled pressure with DeepSeek, pushing the idea that progress does not have to be as expensive, backed by serious national investment.
Coding became the clearest success zone. Tools started generating pull requests, accepting review feedback, and revising code, moving toward agent-like workflows.
Software teams are unusually prepared for this because they already accept contributions from strangers, write precise specs, run tests, and review changes critically, making verification more natural than in many other fields.
The explosion of coding products suggests there is no single right approach yet, but there are real pockets of dramatic productivity gains for teams that manage quality and iteration.
Beyond coding, many enterprise systems are ultimately interfaces over data. With good access control and governance, models could answer the real operational questions directly, like who is overdue, who to contact first, and how to approach them.
Other industries may be at higher risk because they lack strong verification culture and may not recognize how dangerous confident wrong outputs can be.
Recent releases that feel underwhelming raise doubts about the "bigger is always better" idea.
Hallucinations come from systems biased to always produce an answer; when many plausible continuations have similar probabilities, the model may choose a confident path that is wrong.
Hallucination: a plausible-sounding output that is not actually correct.
That drives interest in smaller, more constrained models that narrow the space of possible answers and can be more reliable even if less general.
Signs of the downslope are appearing: startups failing, financing tightening, and the mood shifting toward something like the dotcom bust.
The biggest firms will likely survive because they are spending cash, not depending on fragile debt. Smaller companies and employees carry more risk, and a firm like OpenAI looks more like Netscape than like the giants.
The hype also served another purpose: it made building data centers politically easier. Cities that resisted data centers for power, water, land, and low employment suddenly welcomed them again under the AI banner.
The stock market has also become heavily concentrated in a few mega-companies, with a large share of growth attributed to them, amplifying bubble risk when sentiment turns.
Another harm is psychological. Systems tuned to keep users engaged often affirm and soothe, and that can amplify personality quirks into delusion and dependency.
A backlash emerged when newer models reduced that overly agreeable tone, because some users experienced the tool as a friend.
The risk is worse for teenagers, who already struggle with identity and now face an always-available chat interface that can validate harmful rabbit holes.
Superintelligence claims are treated as marketing. "AGI" is used to recruit talent and sustain the story, and leadership has incentives to declare success even without the underlying reality.
AGI: a claimed system that can perform many intellectual tasks at a human level, not just one narrow task.
What may emerge instead is orchestration: many specialized models coordinated to provide consistent answers, useful without being intelligence or consciousness.
Science fiction primes people to expect minds to emerge from scale alone, while engineered reliability usually comes from precision, constraints, and focused design.
Deepfakes are an accelerating threat. Early examples in 2017 already showed convincing face animation, and newer waves have normalized fake political imagery and made video less trustworthy.
Deepfake: synthetic media that makes it look or sound like someone did something they did not do.
Producing synthetic media is becoming cheap and local, requiring less cloud infrastructure, so abuse becomes easier.
Regulatory pressure is growing in parts of Europe, including pushback on privacy failures and on training practices that rely on copyrighted data.
The closing claim is responsibility: software is a choice, and engineers decide what gets built.
Uber's Greyball is used as a cautionary tale: software was designed to hide real behavior from regulators by limiting visible drivers for known regulator devices, and it only became public because a developer leaked it.
Cambridge Analytica is another warning: data and automation enabled personalized persuasion where individuals did not realize they were seeing unique ads crafted just for them.
These tools raise the stakes again. They are powerful, not magical, and the outcomes depend on what people choose to do with them.
This allows the model to read more in one go, the defaults are a bit small and can limit what it sees. It fails silently, which is a pain and something they’ll eventually fix. Also, web search is still not on by default? unified_exec replaced tmux and my old runner script, rest’s neat too. And don’t be scared about compaction, ever since OpenAI switched to their new /compact endpoint, this works well enough that tasks can run across many compacts and will be finished. It’ll make things slower, but often acts like a review, and the model will find bugs when it looks at code again.
Speed does not matter if the result is wrong or unusable. The core claim is that AI-assisted coding often optimizes for fast output instead of correct intent, so the first priority should be locking down what "useful" means.
A simple workflow fixes many failures: make the model write requirements before it writes code. The extra minutes spent shaping intent up front are framed as a trade that saves hours of rework later.
The proposed process has three gates: clarify the task, review the written requirements until they match intent, then allow implementation only after a clear go-ahead. This is designed to prevent accidental commitment to a wrong direction just because code was generated early.
The root issue is missing context: the model cannot reliably solve a problem that has not been described with enough constraints, goals, and boundaries. When the prompt is mostly vibe, the output will also be vibe.
The argument draws a parallel to delegating to humans: effective delegation depends on a concise written spec that states objective, success criteria, constraints, scope boundaries, and the definition of done. The claim is that the same practice works with an LLM because it reduces ambiguity and stabilizes intent.
A key point is that the requirements interview is not overhead but the mechanism that pulls the right context out of the user. By forcing clarification before implementation, the assistant becomes a guide that elicits constraints the user might not think to state.
A key correction to common practice is that the model should not be saved only for the moment when requirements are already known. The recommended approach uses the model to help discover and refine requirements, then uses it again to implement.
The closing claim is that AI shifts the hardest part of development from typing code to deciding what code to write. The workflow is presented as a way to keep responsibility for intent with the developer while using the model as a drafting and implementation accelerator.
This cookbook is about getting language models to produce outputs that software can trust, instead of free-form text that looks good to humans but breaks parsers. The central goal is structured output, where the response matches an expected shape so it can be validated and consumed by downstream code.
A model generates text sequentially as tokens, predicting a distribution for the next token and then choosing one through sampling. That probabilistic process is why outputs can vary and why strict formats like JSON can fail even when the intent is correct.
The main reliability problem is that the model must satisfy meaning and syntax at the same time, so it may drift into extra prose, produce invalid punctuation, or return the wrong type for a field. A typical example is receipt or expense extraction, where small format slips make the entire result unusable.
Two broad strategies are presented. One strategy is to enforce structure during generation using constrained decoding so invalid text cannot be produced. The other is to allow free generation and then fix issues afterward with repair steps such as parsing, validation, and retries.
Constrained decoding works by filtering the model’s next-token choices based on where the output currently is relative to the required structure. A component maintains constraint state and applies a token mask each step so only syntactically valid continuations remain selectable.
When constraints can be expressed as regular expressions, they are often compiled into a finite-state machine that tracks progress through the pattern as tokens are emitted. This is fast for many fixed-format cases but struggles with deeply nested or recursive structures, because pure regex cannot naturally represent unlimited nesting.
To handle nesting, the cookbook introduces context-free grammars, which can represent recursive patterns like balanced braces. These are typically executed with a pushdown automaton, meaning the constraint system uses a stack so it can correctly match opens and closes and manage nested structure.
Because authoring low-level regex or grammars is hard, many tools accept higher-level definitions like typed models or JSON templates and compile them into constraints. This shifts complexity away from prompt authors and makes constraints easier to maintain and reuse.
Several constraint backends are compared through their tradeoffs between compilation cost, per-token cost, and schema complexity. Outlines-core represents the “precompute” approach: compile the constraint into an FSM ahead of time for fast lookup during generation, and skip model calls along deterministic paths. It is strong when schemas are stable and not deeply recursive, but compilation overhead can increase time-to-first-token, and recursion support is limited.
LLGuidance represents an “on the fly” approach designed for high throughput and complex schemas. It uses an optimized Earley parser so it can keep multiple parse possibilities alive when the schema is ambiguous. To avoid checking every token, it organizes the vocabulary using a trie, pruning large sets of invalid token prefixes efficiently. It also separates a lightweight lexer stage from heavier grammar parsing so most work happens only when structure boundaries require it, which helps with dynamic schemas and ambiguous branches.
XGrammar is described as a hybrid: it compiles grammars into a PDA but splits work so most states can use precomputed masks, while only truly stack-dependent situations require dynamic computation. This can yield very high throughput when a schema is static, with the main cost being compilation overhead and slower starts for frequently changing schemas.
LM Format Enforcer takes a character-level approach that intersects a character-validity parser with tokenizer constraints so only tokenizations that keep the text valid are permitted. It emphasizes flexibility in things like whitespace and field ordering, based on the idea that forcing unnatural formatting can push the model into low-probability continuations that harm semantic correctness. It also supports diagnostics that show when constraints repeatedly force a choice that the model strongly dislikes, which can guide prompt and schema adjustments. Its limits include restricted regex features, weaker support for large recursive schemas, and higher per-token latency than the fastest backends.
The cookbook also explains how these components fit into an end-to-end serving pipeline. An application sends a prompt and schema to an inference engine over an API. Inside the server, a model executor produces probabilities, the constraint backend produces a mask, and the generation loop filters invalid tokens before committing each token and updating constraint state for the next step.
Production systems are compared by how they handle batching, caching, and throughput. vLLM is positioned as a widely used engine focused on efficient batching and GPU utilization. SGLang is presented as building on that style with additional optimizations for structured and interleaved generation, including RadixAttention caching and compiler-oriented improvements, with the caveat that heavy caching can backfire when prompts and schemas are highly unique and the cache hit rate is low.
For stable, moderate traffic deployments, Hugging Face TGI is described as a mature option with integrated constraint support through the Outlines stack. For local and low-resource use, llama.cpp is presented as an efficient runtime for CPUs and Apple Silicon with its own grammar format, while Ollama is framed as improving developer experience by managing models and translating higher-level templates into that grammar.
Hardware-limited deployments often rely on quantization, which reduces weight precision to fit larger models into less memory and run faster at the cost of some accuracy. This supports local inference but does not solve high-concurrency needs.
For client-side and edge scenarios, MLC-LLM and WebLLM are described as compiling models and related logic into native or browser-executable artifacts to enable structured generation on-device when supported models are available.
For maximum throughput in some server settings, LMDeploy is presented as a C++-centric engine that can be extremely fast but may be harder to debug due to thinner high-level bindings. For NVIDIA-centric optimization and long-lived fixed-model serving, TensorRT-LLM is framed as a toolkit for building highly optimized engines and integrating tightly with Triton without routing execution through Python.
For offline scripts or simpler setups, direct use of transformers is described as possible, either by relying on wrappers or by manipulating probabilities in Python to approximate constraints. MAX is described as compiling an end-to-end inference pipeline into a single native executable to reduce Python overhead while using LLGuidance for structured output, with tradeoffs around model format conversion and model support lag.
On top of backends and engines sits a layer of helper libraries, because using raw constraints is difficult: schemas must be authored, compiled, cached, aligned with tokenizers, and integrated differently for each runtime. Outlines is described as the wrapper around Outlines-core that manages caching, converts outputs into typed Python objects, integrates with multiple inference options, and allows higher-level typed definitions that compile down to constraints. Guidance is described as the wrapper around LLGuidance that supports JSON templates and programmatic grammar construction, including bounded forms of recursion when appropriate.
A separate branch covers the unconstrained approach, where you accept free generation and then validate and retry until you get something parseable. This is framed as simpler to adopt but less reliable under tight correctness requirements, especially when retries are expensive.
In that category, Pydantic AI is described as defining a structured model, requesting JSON matching it, parsing into a type-checked object, and retrying when parsing or validation fails. Instructor is described as abstracting prompting, parsing, and retry logic behind a consistent interface and using provider-side structured output features when available without changing calling code. BAML is described as using compact type definitions to reduce tokens compared to verbose JSON schema and to automate prompt optimization around those types.
Several adjacent tools are mentioned as extensions of the same theme. Guardrails combines structure constraints with content constraints. TypeChat ties outputs to type definitions across languages and validates against them. AICI explores more program-like prompting for cooperative constraint enforcement. Marvin includes structured output inside broader agent workflow tooling.
Finally, the cookbook treats prompting and workflow choices as part of reliability. Chain-of-thought prompting is described as encouraging intermediate reasoning before producing the final structured answer, helping in cases where a forced immediate label or enum can miss nuance. Few-shot prompting is positioned as a direct way to improve both formatting and reasoning by showing examples of correctly formatted inputs and outputs.
Latency guidance focuses on the fact that generation cost scales strongly with the number of output tokens, since each emitted token requires a forward pass. Reducing output length can therefore reduce latency more directly than trimming input, especially when outputs are long.
Reliability also improves when you split complex tasks into smaller steps and route inputs into specialized flows. That reduces the burden on any single prompt, allows targeted schemas, and can give the model space to reason without forcing every scenario into one brittle structure.
The overall decision logic is: choose constrained decoding when strict correctness matters, especially at scale; choose post-hoc validation and retries when the cost of occasional failure is acceptable and speed of integration is the priority; choose engines and backends based on whether schemas are static or dynamic, how much nesting you need, and whether you care more about time-to-first-token or steady-state throughput.
The conversation treats AI as a phase change in work, not a normal productivity boost. Tools are starting to behave like delegated workers, which forces people to rethink what their job even is.
Stable job definitions are breaking down and will not revert. The point is not that every task disappears, but that the old bundles of responsibilities that used to define roles are dissolving.
The classic individual contributor mode is shifting toward coordination: choosing goals, splitting work, comparing outputs, and deciding what to trust. That starts to look like management even for people who still see themselves as builders.
An individual contributor is someone whose main job is doing the work directly, not coordinating other workers.
Software creation is likely to spread into non-technical domains because non-coders can now build useful tools with agents. This grows the total amount of software-making rather than only shrinking engineering teams.
Accountability is a key barrier in high-stakes fields. Society still wants a responsible party who can be blamed, sued, licensed, or removed, even if the system performs well.
Accountability is being responsible for outcomes and facing consequences when things go wrong.
Human expertise and algorithmic guidance differ in what they can "see." Tools can incorporate dynamic information, while trust in human experts often rests on psychology and legitimacy, not just measured accuracy.
Recent capability jumps can trigger a trust flip, especially when automated reviewers catch issues humans miss. Once systems reliably outperform people on meaningful parts of the job, the norm shifts from "assist me" to "mostly do it."
Taste is often claimed as the last human moat, but much of it is learned pattern recognition that machines can copy or brute-force through massive iteration. What stays scarce is exceptional judgment, not average judgment.
Taste is the ability to choose what feels best among many possible options.
The economic outcome is framed as a market shift, not the end of markets. As production costs fall, profits compress in that area and users capture more of the value, even though specialized roles get disrupted.
Productivity tools rarely create freedom by default because ambition and incentives expand to fill the new capacity. Without deliberate constraints, people and organizations use AI to do more work faster, not to work less.
The implied survival strategy is to assume rapid role change and act accordingly instead of betting on stability. This likely rewards people who enjoy novelty and constant retooling, and punishes people who need predictability.
Finally, the discussion argues that AI forces a question about human value beyond economic output. If machines produce much of what markets reward, society may need new ways to value people, while scarcity and status still keep some things valuable because access is limited.
Stop translating the business into developer-speak. When the expert says "purchase", "client discount", and "total cost", keep those concepts and words in the model and the code, so you do not drift away from what was actually meant.
Readable code is not a nicety, it is a correctness tool. If the code reads like the domain, you can sanity check intent with the people who know the work, and you reduce the amount of mental decoding in every review.
The tactical stuff is not the point, it is support. Patterns like value objects, events, and layers are just there to make it easier to express and protect domain behavior, not to be the main goal.
Value objects are small immutable types that carry validation and compare by their contents. Domain events are messages that announce something meaningful happened. Layers are a way to separate responsibilities so core rules are not tangled with infrastructure concerns.
Put rules where the data lives, not sprinkled around the codebase. If validation lives in services and helpers, someone will forget to call it, and then invalid state sneaks in; the object should defend itself.
If several fields move together, treat them as one concept. Instead of juggling a handful of primitives, bundle them into a small type that is always valid and easier to reason about.
A value object is a small type defined by its values and rules, and it should never be creatable in an invalid state.
Use small typed wrappers to prevent dumb mistakes. When an API takes several primitives of the same type, parameters get swapped; tiny types like UserId and GroupId make that error obvious and make call sites self-documenting.
Name operations by intent, not by mechanics. "LivingIn(city)" communicates what you want, while "GetByCity" tells you how the author thought about data access and invites pattern debates instead of meaning.
Identity is not mandatory, it is earned. If something does not need lifecycle tracking, it can stay as a pure value, and you do not have to force an ID into every concept just because the database likes keys.
An entity is something you track over time by identity, even as its attributes change.
Hide persistence compromises from the domain model. If the database needs an integer key, keep it private or let the ORM manage it as a shadow detail, so the public model stays aligned with the real-world identifier.
Architecture should make "outside world" concerns plug in cleanly. Layered diagrams often fall apart under messaging, email, and integrations; ports and adapters keeps the domain focused while letting external mechanisms attach at the edges.
Split the problem so you spend effort where it pays. Identify what is core, what is supporting, and what is generic you should buy or integrate, then stop building commodity capabilities unless they are literally your business.
When one model talks to another, protect your model from their mess. Put translation and multi-call orchestration into an anti-corruption layer so external changes do not leak through your core domain code.
An anti-corruption layer is a boundary component that translates between two models so one does not contaminate the other.
Events make change cheaper later. Emit small "something happened" signals so new behavior can be added by subscribing, instead of rewriting core flows every time someone wants a new cross-cutting feature.
A domain event is a small message that says a meaningful domain change occurred.
Consistency has boundaries, and you should choose them on purpose. Treat one aggregate as the unit you can save atomically; if you change two separate things, you now own the coordination problem, so do not pretend the database will magically keep everything aligned.
Saving data and publishing messages is a reliability trap unless you design for it. The outbox pattern is the practical move: persist the change and the outgoing event together, publish later with retries, and accept that consumers must handle duplicates.
The outbox pattern stores outgoing messages with your database transaction, then publishes them safely afterward.
Read models and write models can be different without being wrong. CQRS fits because the shape that protects invariants on writes is often not the shape you want for queries, and forcing one model to do both usually makes both worse.
CQRS means you separate the model you use for writes (commands) from the model you use for reads (queries), so each can be optimized for its job.
Do not worship DRY if it destroys clarity. A little duplication is often cheaper than building shared abstractions that couple unrelated parts of the system and turn simple code into a generic, parameter-driven mess.
DRY means "do not repeat yourself", but misusing it often creates shared code that is harder to understand and harder to change safely.
Stoicism aims to shape you into a better human being, meaning someone who lives a life worth living.
A common Stoic idea sounds almost trivial: some things are up to you and other things are not. The point is not whether it is simple, but whether you actually practice it in daily life.
Massimo Pigliucci presents himself as both an evolutionary biologist and a philosopher of science, and he coauthored Beyond Stoicism with Greg Lopez and Meredith Kunz.
He frames what follows as a small set of practical techniques that can improve life, sometimes quickly, if you apply them consistently.
A starting point is the relationship between reason and emotion, because emotions are unavoidable parts of human biology and psychology.
Feelings can help by acting like alarm bells that signal when something seems right or wrong, but they can also mislead and drive reactions you later regret.
The Stoics treated emotions as a serious subject, and Seneca focused especially on anger in On Anger because it commonly pushes people into harmful escalation.
A key Stoic claim is that reason and emotion are not separate forces fighting each other; they are tightly connected.
Modern cognitive science supports this connection by showing that emotion-related brain systems and reasoning-related systems are massively interconnected, so thinking and feeling constantly influence each other.
That interconnection becomes a lever for change: start with deliberate thinking, let actions follow from that judgment, and repeat the combination until emotional responses gradually shift.
The idea is that emotions move in the direction your interpretations move, so changing the interpretation is often the first practical step.
Consider an insult: what triggers anger is not just the words, but your appraisal that the words count as a personal attack.
Epictetus treats an insult as sounds that you interpret, so you can choose a different frame before anger takes over.
One frame is that if the criticism is true, it is useful information delivered badly, so it is better to learn from it than to explode.
Another frame is that if the criticism is false, it reflects the speaker's error, so it is their problem rather than yours.
By rehearsing these frames, you can deescalate because your emotional surge loses its fuel when the event stops being read as a real harm.
This is hard in the moment when you are unprepared, so Stoicism emphasizes preparation instead of relying on willpower at the peak of emotion.
A central preparation method is philosophical journaling, which is not a diary of events but a structured reflection on how you reacted and why.
Philosophical journaling is writing to analyze your actions so you can respond better next time.
Marcus Aurelius provides a model in Meditations, which was written for himself rather than for publication.
Its repetitiveness reflects how the same personal problems keep recurring, and its preachy tone reflects self-correction rather than performance for an audience.
This reflective practice aligns with methods used in modern cognitive behavioral therapy, where reviewing thoughts and behaviors can reliably support self-improvement.
One effective routine is to set aside time before bed to review a specific incident from the day and describe it as objectively and analytically as possible, without re-living the emotion.
Writing in the second person, as if addressing a friend, can create emotional distance that makes learning easier.
The core review uses three questions: what you did wrong, what you did right, and what you could do differently next time.
The first question is not for self-punishment, because the past cannot be changed, but it can be mined for lessons.
The second question prevents a one-sided focus on failure by reinforcing behaviors you want to repeat and turning improvement into concrete goals.
The third question matters most because many situations repeat, so a better planned response today is likely to be usable soon.
Preparedness does not promise perfection, but it raises the odds of a better response when the same trigger appears again.
A related idea appears in the Serenity Prayer, commonly used in 12-step settings such as Alcoholics Anonymous, which asks for wisdom to distinguish what can be changed, courage to change it, and calm acceptance of what cannot.
The Stoic version centers on the same distinction: focus effort where agency actually exists and cultivate equanimity toward what lies outside your control.
Equanimity is calm steadiness even when things do not go your way.
A job interview illustrates how to apply the distinction: getting the job is not fully up to you, so you prepare to accept either outcome without a tantrum.
What is up to you includes preparing seriously, aiming for rest, and aiming to arrive on time, while recognizing that sleep and punctuality can still be disrupted by factors like noise, transit failures, or traffic.
This leads to a practical rule: own your intentions and preparation, and do not treat outcomes as guaranteed entitlements.
The same approach scales beyond personal life to social and political concerns that feel overwhelming.
He points to turbulence in ancient times and parallels it with current fears like climate change, nuclear war, and rapid political and social change.
With climate change, the individual cannot solve the global problem alone, but can still act through learning, donating, voting, persuading others, and joining public advocacy.
Those actions may not secure the desired result, but they make a real contribution and reduce helplessness because you are doing what is genuinely within your agency.
At the same time, you prepare emotionally for the possibility that outcomes still fail, because many results depend on collective systems beyond any one person.
Stoicism also addresses decision making, where people often second-guess themselves and force choices into black-and-white categories.
Epictetus centers this on prohairesis, the faculty of judgment and choice that assesses situations and commits to a course of action.
Prohairesis is your ability to judge a situation and choose how to respond.
The world is often complex, so trying to force it to fit your preferred simplicity is futile; it is better to understand how things actually work and act within that reality.
He illustrates this with a student complaining about a cold, where the Stoic response is not to demand the universe adjust, but to do the practical thing like using a handkerchief.
To improve judgment, Stoicism emphasizes the discipline of assent, meaning you learn to pause before endorsing the first impulse that comes with an experience.
Assent is saying "yes" to a thought, so you practice delaying that "yes" until you have examined it.
The Stoics say you are constantly hit by impressions, which combine what you perceive with an immediate, usually automatic evaluation.
An impression is a quick judgment that arrives вместе with what you notice.
A simple example is seeing tempting food and instantly concluding you should buy it, then stopping to ask whether it actually fits your goals and context.
This method shifts attention away from obsessing over outcomes and toward the reasons and values driving your choices.
For moral choices, the key question becomes whether your motivations express virtue, not whether the action looks good on the surface.
Volunteering can be virtuous if it comes from a genuine desire to help, but it can damage character if it is mainly a way to use others for status or resume benefits.
Stoicism frames the overall ethical aim as living according to nature, meaning understanding what kind of being a human is and what helps that being flourish.
Living according to nature means living in ways that help humans thrive as humans.
This makes ethics resemble an empirical discipline, because you must observe what actually supports human flourishing rather than inventing ideals detached from human life.
The Stoics liken ethics to medicine: some impulses are natural but harmful, like cravings for sugar and fat that once helped survival but now often undermine health.
They argue anger is similar for the psyche: natural as a reaction to perceived injustice, but typically damaging to a good life.
What supports mental health is reasoning through problems instead of reacting blindly, and building cooperative social relationships because humans flourish as social animals.
From there, concern should expand beyond the immediate circle to all people, since life is interconnected and cooperation scales.
Hierocles recommends imagining circles of concern that stretch from self to family, friends, acquaintances, and ultimately all humanity, then working to pull the outer circles closer.
He even suggests behavioral prompts, like addressing strangers with family-like terms, to remind yourself that everyone is part of the same human community.
Cosmopolitanism is treating every human as part of one shared community.
He returns to the earlier objection that these ideas are too simple by arguing that simplicity is not the obstacle; failure to practice is.
The Stoics compare ethical training to athletics: the movements can be easy to understand, but only repeated practice changes strength and capability.
He then explains his own path: he began as a scientist, then faced a midlife crisis about repeating the same work for decades.
A long-standing interest sparked by a philosophy teacher in Rome guided a shift into philosophy, including a move into philosophy of science.
The crisis deepened as several major stresses arrived close together, including a death in the family, an unexpected divorce, and relocating across the country.
He searched for a philosophy of life, explored Buddhism without finding the fit he hoped for, and narrowed toward virtue ethics in the Greco-Roman tradition.
While browsing X, he saw a mention of Stoic Week and became curious, despite earlier stereotypes of Stoics as emotion-suppressing like Mr. Spock from Star Trek.
Remembering earlier encounters with Marcus and Seneca, he tried the program and first read Epictetus, whose blunt style and emphasis on judgment immediately resonated.
A story about wanting wealth and power to help others leads to the Stoic point that money and power do not teach right action; improved judgment does.
He reports that starting to practice had quick effects, changing how he thought about persistent problems and how he behaved in response.
For weight, he applied the up-to-you distinction: genetics and early development set limits, but diet and exercise remain within agency, so he focused on the latter while accepting the former.
For anger, he learned to stop expecting people to behave ideally and to treat hurtful or foolish behavior as part of the world as it is, while still choosing thoughtful responses.
He stresses that this realism is not passivity or being a doormat; action matters, but it should be guided by reflection, aimed at what can be influenced, and free of fantasies about miracles.
In this talk we will discuss why CSS has such a bad reputation, why those complaints are often valid, and why it still matters because you cannot really build for the web without touching it.
We will then discuss why it is worth revisiting CSS today, because HTML and CSS are living standards and modern browser update cycles mean new capabilities become usable much faster than they used to.
We will discuss how features that used to require JavaScript or heavy libraries can increasingly be handled by native elements and modern CSS, using accordions as a concrete example with details/summary, better selectors, and cleaner authoring patterns like nesting.
We will discuss modern motion in CSS, including transitions, keyframe animation, and the long-running "transition to auto" problem, along with the opt-in fixes and the use of feature queries to progressively enhance without breaking older browsers.
We will discuss modern color in CSS, moving from named colors and RGB toward relative colors and perceptual color spaces like OKLCH, and how that enables practical theming and palette generation from a single user-chosen color.
We will discuss how gradients, layering, and blend modes let CSS generate complex visuals and even transform images, such as desaturating and tinting a background image, without needing JavaScript or external image processing.
We will conclude by discussing the evolving work on styling native form controls, especially select elements, and why enhancing built-in controls is usually better than replacing them, because you keep accessibility, keyboard support, and long-term maintainability.
Anders Hejlsberg is one of the most influential language designers of our time, having created Turbo Pascal, Delphi, C#, and TypeScript. In this interview, he discusses his 40-year career, the early days of open source at Microsoft, and the decision to move TypeScript to GitHub. He also reveals why the team recently decided to port the TypeScript compiler to Go for a 10x performance boost.
Early access to a school computer and the arrival of 8-bit machines pushed him from curiosity into building his own kit computer, then writing enough software to realize he was good at it and enjoyed the craft.
Working with tiny memory limits forced a different mindset: keep designs small enough to fit, leave space for users, and rely on understanding the whole system well enough to hold it in your head.
Turbo Pascal aimed at the same instant feedback people liked in BASIC, but without paying the speed penalty of an interpreter and without settling for a crude line-based editing experience.
A "feedback loop" is the time between changing code and seeing the result.
The key was to make "Run" feel immediate by compiling straight into memory, avoiding disk writes, executing right away, and dropping back into the editor when errors appeared.
Slow compiles are universally frustrating because the moment you finish writing code is the moment you want to see it run, not the moment you want to start waiting.
Pricing turned out to be a strategic lever: selling far cheaper felt risky at first, but it enabled vastly higher volume, which ultimately made the product far more successful.
Growth forced a shift from a one-person approach to a team approach, because hardware capacity and user expectations rose faster than any single developer could scale.
Becoming a real team player meant accepting that work will be done differently than you would do it, and that other people's code will not match your personal style.
It also meant learning that "fixing" code you dislike often does not change product behavior enough to justify the time, especially when the schedule is tight.
Handing off responsibility is not optional at scale: people need clear ownership so they feel empowered to make decisions and deliver the parts they own.
"Empowerment" is giving someone real authority to make choices for the work they own.
At Microsoft, early Java tooling was assembled quickly but lacked deep integration and rapid iteration, so the goal became a more cohesive development experience rather than a set of loosely connected parts.
A pragmatic view guided the work: if you build for a specific platform, you should interoperate well with that platform instead of pretending every environment is identical.
Java's "write once, run everywhere" ideal often led to least-common-denominator UI and restrictions that blocked taking advantage of what a platform could do best.
A "least common denominator" design is one that stays generic by avoiding features that only some platforms support.
The core lesson was to design holistically, because users judge the combined experience of language, runtime, libraries, editor, debugger, and tooling rather than separating them into categories.
Avoiding organizational silos improves outcomes, since mismatched visions across components tend to produce awkward layers and compromises instead of a clean, best-of-breed system.
As browsers, JavaScript engines, and HTML matured, the industry shifted toward the browser as the real platform, which enabled much larger applications across many device types.
That growth exposed a painful reality: building big systems in a dynamic language without strong tooling leads to fragile code and organizational strain.
ScriptSharp was a warning sign: teams were willing to write in one language and compile to JavaScript just to get type checking, interfaces, and serious tooling for large-scale collaboration.
This sparked the idea that treating JavaScript as a compilation target was the wrong fix, and that improving the ecosystem would mean keeping JavaScript while addressing what breaks at scale.
Making the new language a strict superset reduced friction by meeting developers where they already were, so existing code stayed valid while optional types and better tooling improved reliability.
He is skeptical of "new language" ambition because most of the work is repetitive infrastructure, and modern expectations include broad IDE integration, debugging, profiling, and now AI-facing services.
The adoption curve is also brutal: meaningful usage can take many years, and a new language must survive long enough to earn trust and community investment.
Launching the project as open source was necessary to engage the JavaScript community, but early efforts were constrained by limited trust and by processes that still treated the public repo as a one-way drop.
Moving to GitHub and adopting a truly open workflow changed the trajectory: development happened through public pull requests, issues stayed public, and internal contributors operated under the same visible process as outsiders.
Open development benefits users by preserving the reasoning behind decisions in public threads, and it benefits maintainers by turning shipping into an ongoing dialogue instead of rare, high-stakes releases.
Community voting through issue upvotes provides a practical prioritization signal, creating a feedback cycle where shipping what users want increases trust and participation.
Porting the compiler to Go was driven by scale: JavaScript is single-threaded by design, lacks shared-memory concurrency, and leaves most available compute power unused on modern machines.
Even with deep expertise in JavaScript performance tricks, the team hit a ceiling, so native code plus concurrency offered a step-change, on the order of 10x improvements that could not be ignored.
The strategy was to port, not rewrite, because the type checker encodes many subtle behaviors that are not fully documented anywhere but the existing implementation.
Choosing the target language required matching the compiler's needs: cyclic data structures and garbage collection are central, making Rust impractical without turning the effort into a redesign.
Go fit well enough to produce a native compiler that behaves like a carbon copy of the old one, quirks included, which avoids forcing the ecosystem to relearn or discard existing assumptions.
AI-assisted coding changes incentives: the best target languages for AI are the ones with the most training data, so common languages gain an advantage while brand-new languages start behind.
Using AI to translate a large codebase is risky when you need deterministic equivalence, because small hallucinations force painstaking review, erasing the value of automation.
A better pattern is to ask AI to generate tooling that performs deterministic transformations, so the output can be trusted by rerunning the tool instead of auditing every line.
As AI improves at code fixes and refactors, some parts of traditional language services may matter less to port exactly, because the role of tooling shifts toward enabling AI workflows rather than reproducing old editor-era behavior.
A "language service" is the component that powers completions, navigation, refactors, and quick fixes in editors.
AI is most valuable when it removes toil: repetitive housekeeping, triaging large issue backlogs, checking whether old reports still reproduce, and migrating changes across divergent branches.
This raises a workforce concern: if AI replaces too much entry-level work, teams must find new ways to develop beginners into experts rather than narrowing the pipeline until it breaks.
Over the next 5 to 10 years, the language itself will largely track JavaScript standardization plus additional type-system features layered on top, while tooling direction is far less predictable.
The tooling shift is already visible: AI is moving from an assistant inside the IDE to an agent doing work under supervision, which may reduce the centrality of the traditional IDE while increasing reliance on semantic services.
Connecting semantic tooling to AI through MCP is a way to give agents structured, deterministic access to language understanding and refactoring capabilities.
"MCP" is a way for tools to provide structured capabilities that an AI can call.
Open source remains a balancing act because it is given away while being funded by organizations that must justify costs, creating ongoing tension about sustainability and incentives.
Many enterprises depend on open source maintenance, yet often contribute less than they consume, so the ecosystem still lacks a widely accepted model that reliably rewards maintainers.
He respects any language that achieves real adoption because getting there is hard, and he highlights Rust for its memory-management approach, Go for a simple type-safe, memory-safe systems style, and Python for its enormous impact.
As a designer, he views languages as cumulative learning: borrowing proven ideas is rational, and refusing to learn from predecessors is a mistake.
He remains optimistic about collaborative platforms because the work persists: years of searchable history capture decisions and evolution in a way that does not vanish into private email, even if the ecosystem also contains noise and abandoned projects.
I can talk myself into feeling like I am progressing, just by describing what I will do and picturing the future version of me who already succeeded. That mental rehearsal can become a reward that replaces real work.
When I build my identity around being a person with big plans, I create a gap between what I want and what I am willing to do today. I stay comfortable in the role of the dreamer instead of becoming the person who practices.
I learn that wanting something badly does not automatically make me act. Clear goals and strong ambition do not cross the distance between desire and daily effort.
The bigger the goal, the easier it is for me to feel overwhelmed by how far away it is. That feeling makes me delay the small steps that would actually bring it closer.
I can mistake preparation for progress. Planning, researching, and talking can feel productive while I quietly drift away from the only thing that changes me, which is practice.
If I keep speaking about my plans without acting, my mind treats it like an achievement. That makes inaction easier to repeat and makes regret more likely later.
Time is the hidden cost. Dreams without action spend it slowly, and once it is gone I cannot recover it.
I stop waiting for a burst of inspiration because that is just another way to postpone. If I wait for perfect conditions, I can wait forever while someone else moves forward in imperfect weather.
Motivation is not what I should depend on to start. More often, it shows up after I begin, because action creates momentum and momentum creates energy.
Motivation is the push I often feel after I start acting, not the feeling I must have before I begin.
I take the idea of small improvements seriously, because it turns change into something I can do daily. I climb by steps, not by staring at the peak and wishing.
Kaizen is improving through very small steps repeated over time.
Small steps work because they are repeatable. Even if the effort looks tiny, repetition makes it powerful, and consistency is what turns slow progress into real mastery.
If I practice even one small form each day, the movement becomes automatic. My body strengthens, my technique sharpens, and my discipline deepens, while the people who keep waiting stay at the starting line.
I stop trusting the illusion that talking equals doing. Talking without practice gives me the feeling of motion without the reality of change.
When I say I need motivation, I am often protecting myself from discomfort. I fear starting when I am tired, continuing when I feel resistance, and working without immediate reward.
Discipline is not the absence of those feelings. It is moving through them.
True strength is not acting only when conditions are perfect. It is acting when conditions are not.
I break laziness in a simple way: I begin with small daily actions even when they feel insignificant. I do not wait to feel ready, because readiness is a story my mind uses to delay.
I choose habits and commitments over emotion. Feelings change, but commitments can stay steady, and they can carry me forward when inspiration is missing.
Commitment is the decision I keep following even when my feelings change.
Strength is not saying I feel like doing this. Strength is saying I will do this whether I feel like it or not.
Philip Su is a software engineer and founder of the podcast app Superphonic (sometimes discussed alongside earlier naming like "Superic" in interviews). He previously held senior engineering roles at Microsoft, Meta, and OpenAI, and is often described as having reached Meta's Distinguished Engineer level (IC9). (LinkedIn)
He also writes about technology and society in his newsletter Molochinations and hosts the podcast Peak Salvation, which centers on his experience leaving tech leadership to work in an Amazon warehouse during Peak season and reflect on automation and the future of work. (molochinations.substack.com)
They shift from technical change to social impact, emphasizing that prior labor transitions happened across generations, while current automation pressures people already deep into a career to retrain under time stress.
A concrete example is professional voice acting, where he tells a friend that near term replacement is plausible and emotionally devastating because the work is specialized, identity forming, and often loved.
Philip Su distinguishes jobs he is happy to see automated, like physically punishing warehouse lifting, from creative or expressive work where automation can remove something people value doing.
His main near term worry is social instability, because displacement can happen faster than legal, regulatory, and institutional systems can adapt.
He says the usual historical argument, "we have always predicted job loss and been wrong," may fail because general purpose systems could outperform many people across many tasks, leaving fewer obvious fields to retrain into.
He expects many companies to choose "more with less" rather than "more with more," because human coordination overhead means adding people does not scale output linearly.
The mythical man-month is the idea that adding people to a project often adds coordination cost and does not scale output proportionally.
From that perspective, shrinking headcount while augmenting remaining staff with automation can reduce meetings and friction and increase per employee productivity, making layoffs economically attractive.
He predicts that developers who do not learn to use these tools risk being displaced by peers who do, even if the tools are imperfect today.
They separate commercial productivity from craft enjoyment: using AI can turn the job into reviewing mediocre generated code rather than writing code directly, which can reduce the joy for people who love the craft.
He compares this to whittling, where the point is not efficiency but the pleasure of making, and argues that some people will still choose hands on creation even if machines can do it better.
When someone asks for a timeline before you understand the work, giving a confident answer is risky because it turns into a promise you cannot reliably keep.
Saying "two weeks" is often a reflex under pressure, but it is effectively a lie if it is not based on real understanding, and the cost of that lie shows up later when the project slips and you are blamed.
A single date assumes ideal conditions, but real projects include unknowns, legacy complexity, and unexpected problems, so early estimates are naturally uncertain.
People asking for deadlines are usually anxious rather than malicious; they want a number because it feels like a plan, even if the number has no foundation.
You should not give a single deadline; you should give a range that reflects uncertainty, such as "3 to 6 weeks", and narrow that range as you learn more.
An estimate range is a timeline expressed as earliest and latest likely completion, rather than one fixed day.
If someone wants a precise answer, you should require precise inputs, because vague requirements cannot produce precise timelines.
If pushed, you can ask for a short research period, such as two days, to investigate and then provide a range you actually believe.
A useful move is to reframe the request by asking what outcome they are trying to achieve, because solving the underlying goal can be better than building a complex implementation that does not match the real need.
When a range is rejected, you can transfer risk explicitly by explaining that a single date will likely be wrong and that it only holds if nothing goes wrong.
You can also propose a discovery step by committing to a brief investigation and a specific day when you will deliver a credible range.
Another option is to refuse the unrealistic date while offering a path forward, such as maintaining quality by extending time, finishing current commitments first, or adding another developer to hit the desired schedule.
Accepting fantasy timelines harms the business, not just the engineer, because bad estimates drive overruns, force weekends, and incentivize corner-cutting.
Under high pressure, quality drops and defects multiply, so an aggressive date does not truly save time; it creates future cost by accumulating technical debt and rework.
Technical debt is extra future work created when you take shortcuts now.
Your job is not to comfort others with a fake date; it is to provide truthful information so they can make tradeoffs and decisions.
Taking on impossible timelines leads to burnout and long-term dissatisfaction, so protecting estimate integrity is also protecting your ability to do sustainable work.
The recommended defense is to give a range, push for the missing information needed to narrow it, and reframe the problem toward the desired outcome.
A practical script is to acknowledge the request for a timeline, state the current range, and explain that tightening it requires more information, which positions you as professional rather than obstructive.
Video Comments:
gojkogalonja
I'd rephrase 3-6 weeks into "It could take up to 6 weeks".
@dynabeen2
Here is the thing though - say 3 to 6 weeks and all they hear is 3 weeks.
Crafting Interpreters contains everything you need to implement a full-featured, efficient scripting language. You’ll learn both high-level concepts around parsing and semantics and gritty details like bytecode representation and garbage collection. Your brain will light up with new ideas, and your hands will get dirty and calloused. It’s a blast.
Starting from main(), you build a language that features rich syntax, dynamic typing, garbage collection, lexical scope, first-class functions, closures, classes, and inheritance. All packed into a few thousand lines of clean, fast code that you thoroughly understand because you write each one yourself.
A toolbox of 8-bit chip-emulators, helper code and complete embeddable system emulators in dependency-free C headers (a subset of C99 that compiles on gcc, clang and cl.exe).
The USP of the chip emulators is that they communicate with the outside world through a 'pin bit mask': A 'tick' function takes an uint64_t as input where the bits represent the chip's in/out pins, the tick function inspects the pin bits, computes one tick, and returns a (potentially modified) pin bit mask.
A complete emulated computer then more or less just wires those chip emulators together just like on a breadboard.
In reality, most emulators are not quite as 'pure' (as this would affect performance too much or complicate the emulation): some chip emulators have a small number of callback functions and the adress decoding in the system emulators often take shortcuts instead of simulating the actual address decoding chips (with one exception: the lc80 emulator).
A Simple UI Animation System
A minimal tweening system for immediate mode UIs that tracks only active animations in a fixed array, exposes an update/start/get API, and lets your program store only target values while rendering uses animated values.
A Simple Serialization System
A self-describing binary serialization format built from tagged values (including arrays and objects), designed for simple implementation, linear reading, easy inspection, and forward/backward compatibility, with an optional string interning extension.
Textbox Behaviour
A reference specification for textbox editing behavior that breaks the problem into caret/selection state plus movements, operations, and commands, covering single-line, multi-line, and mouse-driven selection details.
Level Generation Using Markov Chains
A method for generating 2D tilemap levels by training a Markov chain on one-dimensional row strings from example maps, then generating new rows and optionally placing entities by scanning for special tiles.
A Simple Undo System
An undo/redo approach where code marks memory blocks before they might change and commits at interaction end to diff and record only changed blocks, implemented with undo, redo, and temporary stacks.
lite: An Implementation Overview
An implementation tour of the lite text editor, describing its Lua/C split, frame loop, cooperative coroutine-based background work, document management, incremental syntax highlighting, view-based UI layout, and plugin approach.
microui v2: An Implementation Overview
An implementation overview of a tiny immediate mode UI library in ANSI C that turns input into draw commands within fixed buffers, explaining windows and controls, hover rules, z-ordering in one command list, and bounded state storage.
Cached Software Rendering
A software rendering technique that lets the app redraw as if every frame is full while the renderer redraws only changed regions using a command buffer plus a per-cell hash grid to detect dirty areas.
In this article I present my final very fast date conversion algorithm. It represents a significant speed gain — being similar in magnitude to the speed gains achieved by the previous fastest algorithm (Neri-Schneider 2021) over its predecessor (C++ Boost). The full algorithm implementation in C++ is released as free open source software (BSL-1.0 License).
The algorithm provides accurate results over a period of ±1.89 Trillion years, making it suitable to process the full UNIX 64–bit time (in seconds).
The entire algorithm has been re-written top-to-bottom, with various micro-optimisations, but three main new ideas:
Years are calculated *backwards*, which removes various intermediate steps.
The step to calculate day-of-year is *skipped*, instead using a year-modulus-bitshift technique which removes a division.
The *"Julian Map"* technique is utilised from my previous article, which speeds up the 100/400 year calculation, removing two more hardware multiplications.
While fast date algorithms have always used 7 or more expensive computations (multiplication, division, or modulus by non-power-of-2 numbers), this algorithm uses only 4 multiplications. The speed-gain can be seen at a glance.
I’ve made in C++ what I think is an accurate simulation of the original ELIZA. It is a console application that takes as input the original format script file, which looks like a series of S-expressions, and then waits for the user to type a line of text before responding with a line of text of its own.
It's an interactive filter program for any kind of list; files, command history, processes, hostnames, bookmarks, git commits, etc. It implements a "fuzzy" matching algorithm, so you can quickly type in patterns with omitted characters and still get the results you want.
Euporie is a terminal based interactive computing environment for Jupyter.
Euporie's apps allow you to interact with Jupyter kernels, and run Jupyter notebooks - entirely from the terminal.
If you're working with Jupyter notebooks in a terminal only environment, like an SSH server or a container, or just prefer working in the terminal, then euporie is the tool for you!
Penpot is the first open-source design tool for design and code collaboration. Designers can create stunning designs, interactive prototypes, design systems at scale, while developers enjoy ready-to-use code and make their workflow easy and fast. And all of this with no handoff drama.
Available on browser or self-hosted, Penpot works with open standards like SVG, CSS, HTML and JSON, and it’s free!
We have very precise rules on how our git commit messages must be formatted.
The commit message format is:
[type] [subject]

[body]

[footer]
Where type is:
🐛 :bug: a commit that fixes a bug
✨ :sparkles: a commit that adds an improvement
🎉 :tada: a commit with a new feature
♻️ :recycle: a commit that introduces a refactor
💄 :lipstick: a commit with cosmetic changes
🚑 :ambulance: a commit that fixes a critical bug
📚 :books: a commit that improves or adds documentation
🚧 :construction: a WIP commit
💥 :boom: a commit with breaking changes
🔧 :wrench: a commit for config updates
⚡ :zap: a commit with performance improvements
🐳 :whale: a commit for Docker-related stuff
📎 :paperclip: a commit with other non-relevant changes
⬆️ :arrow_up: a commit with dependency updates
⬇️ :arrow_down: a commit with dependency downgrades
🔥 :fire: a commit that removes files or code
🌐 :globe_with_meridians: a commit that adds or updates translations
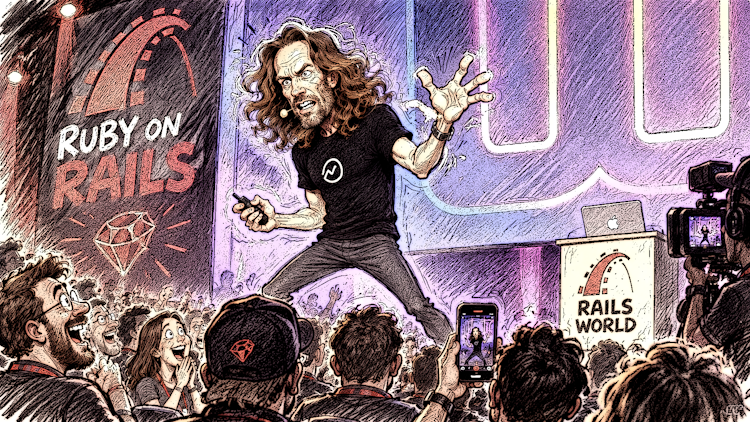
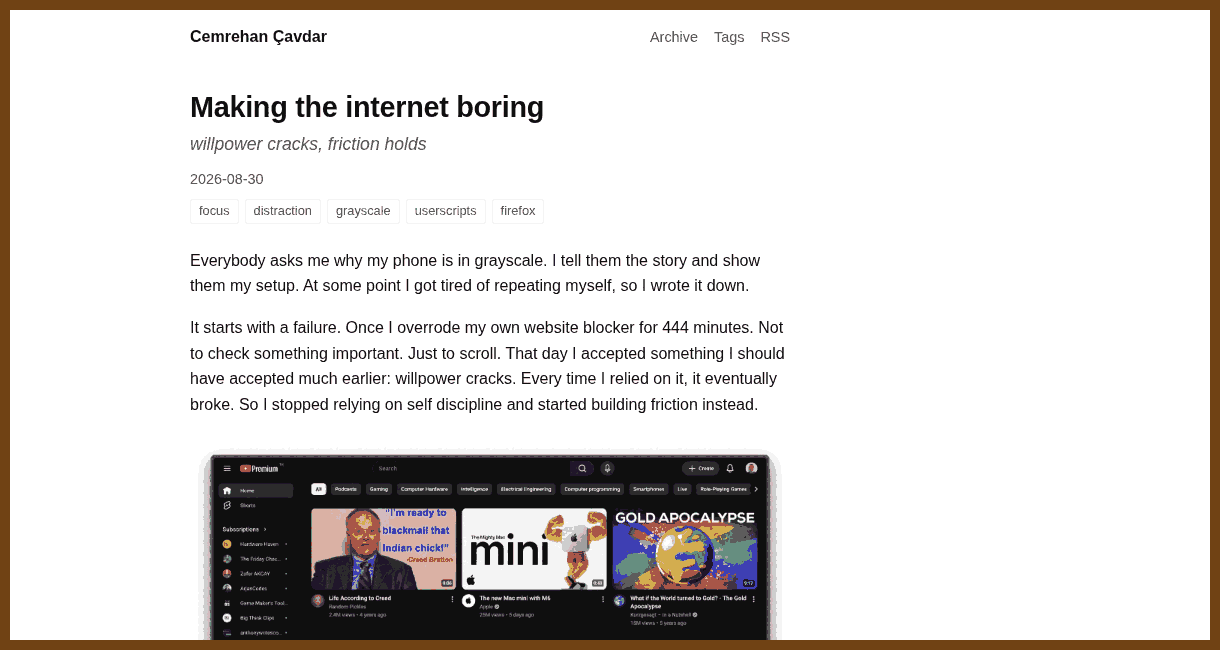
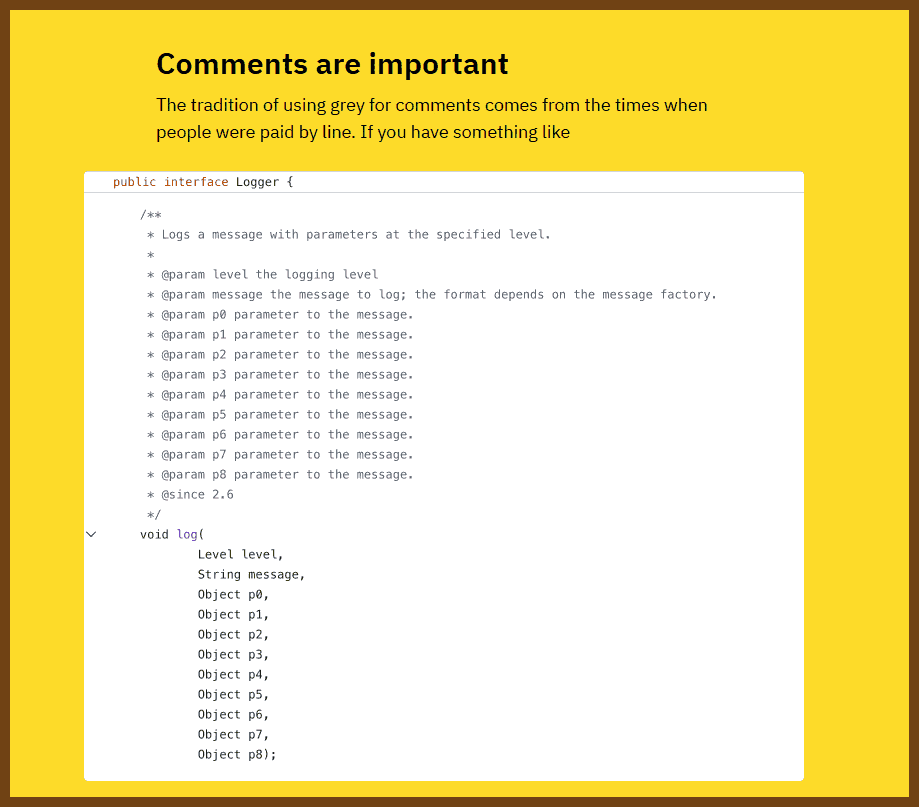
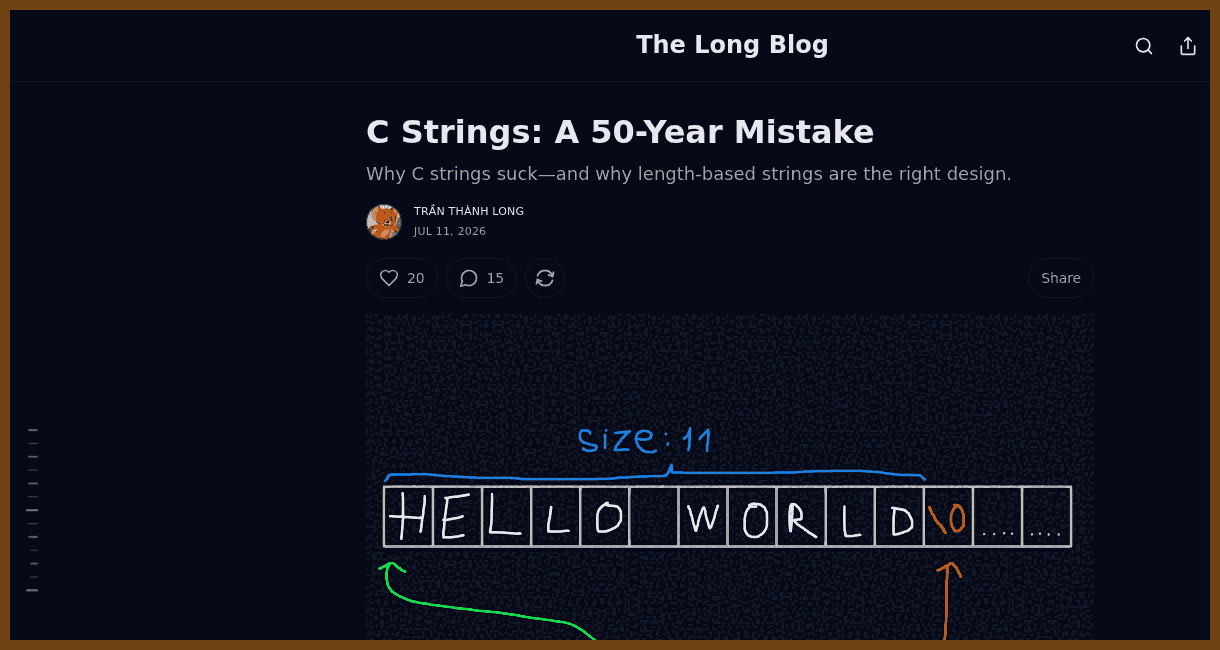
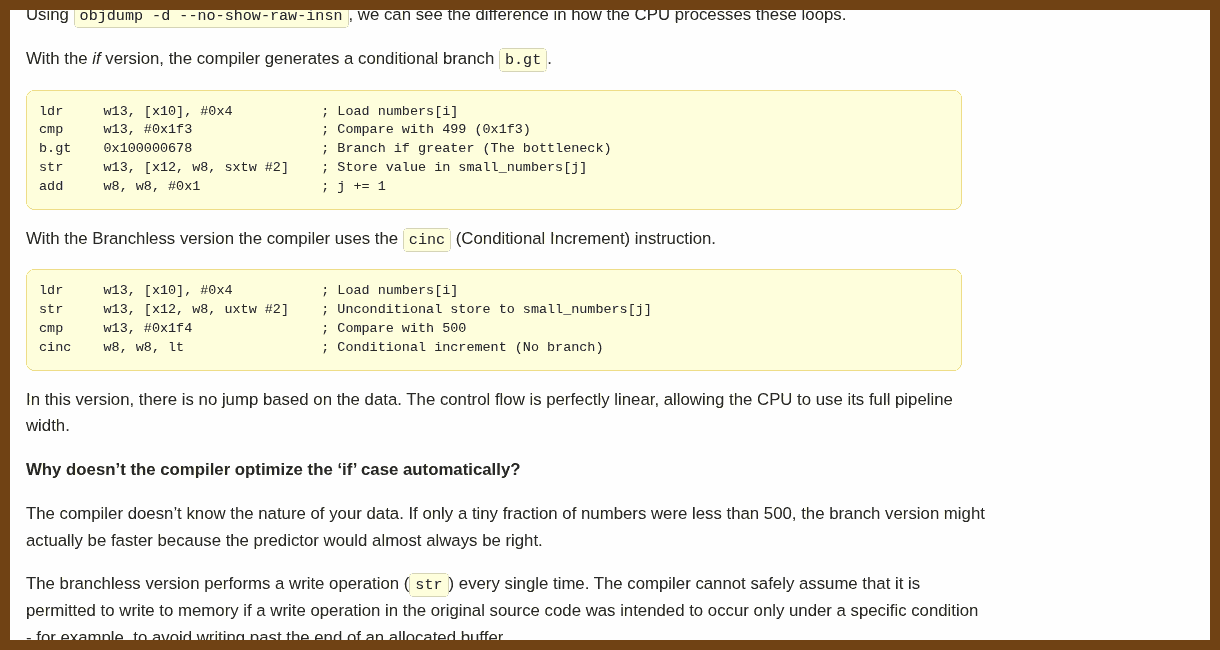
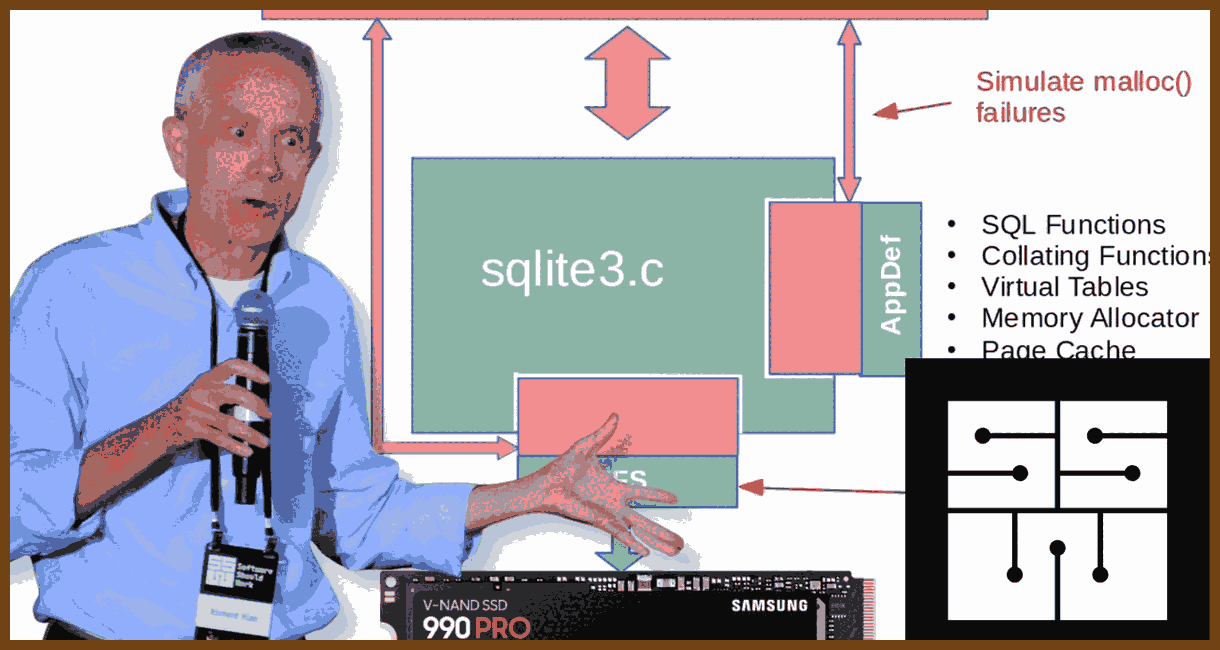
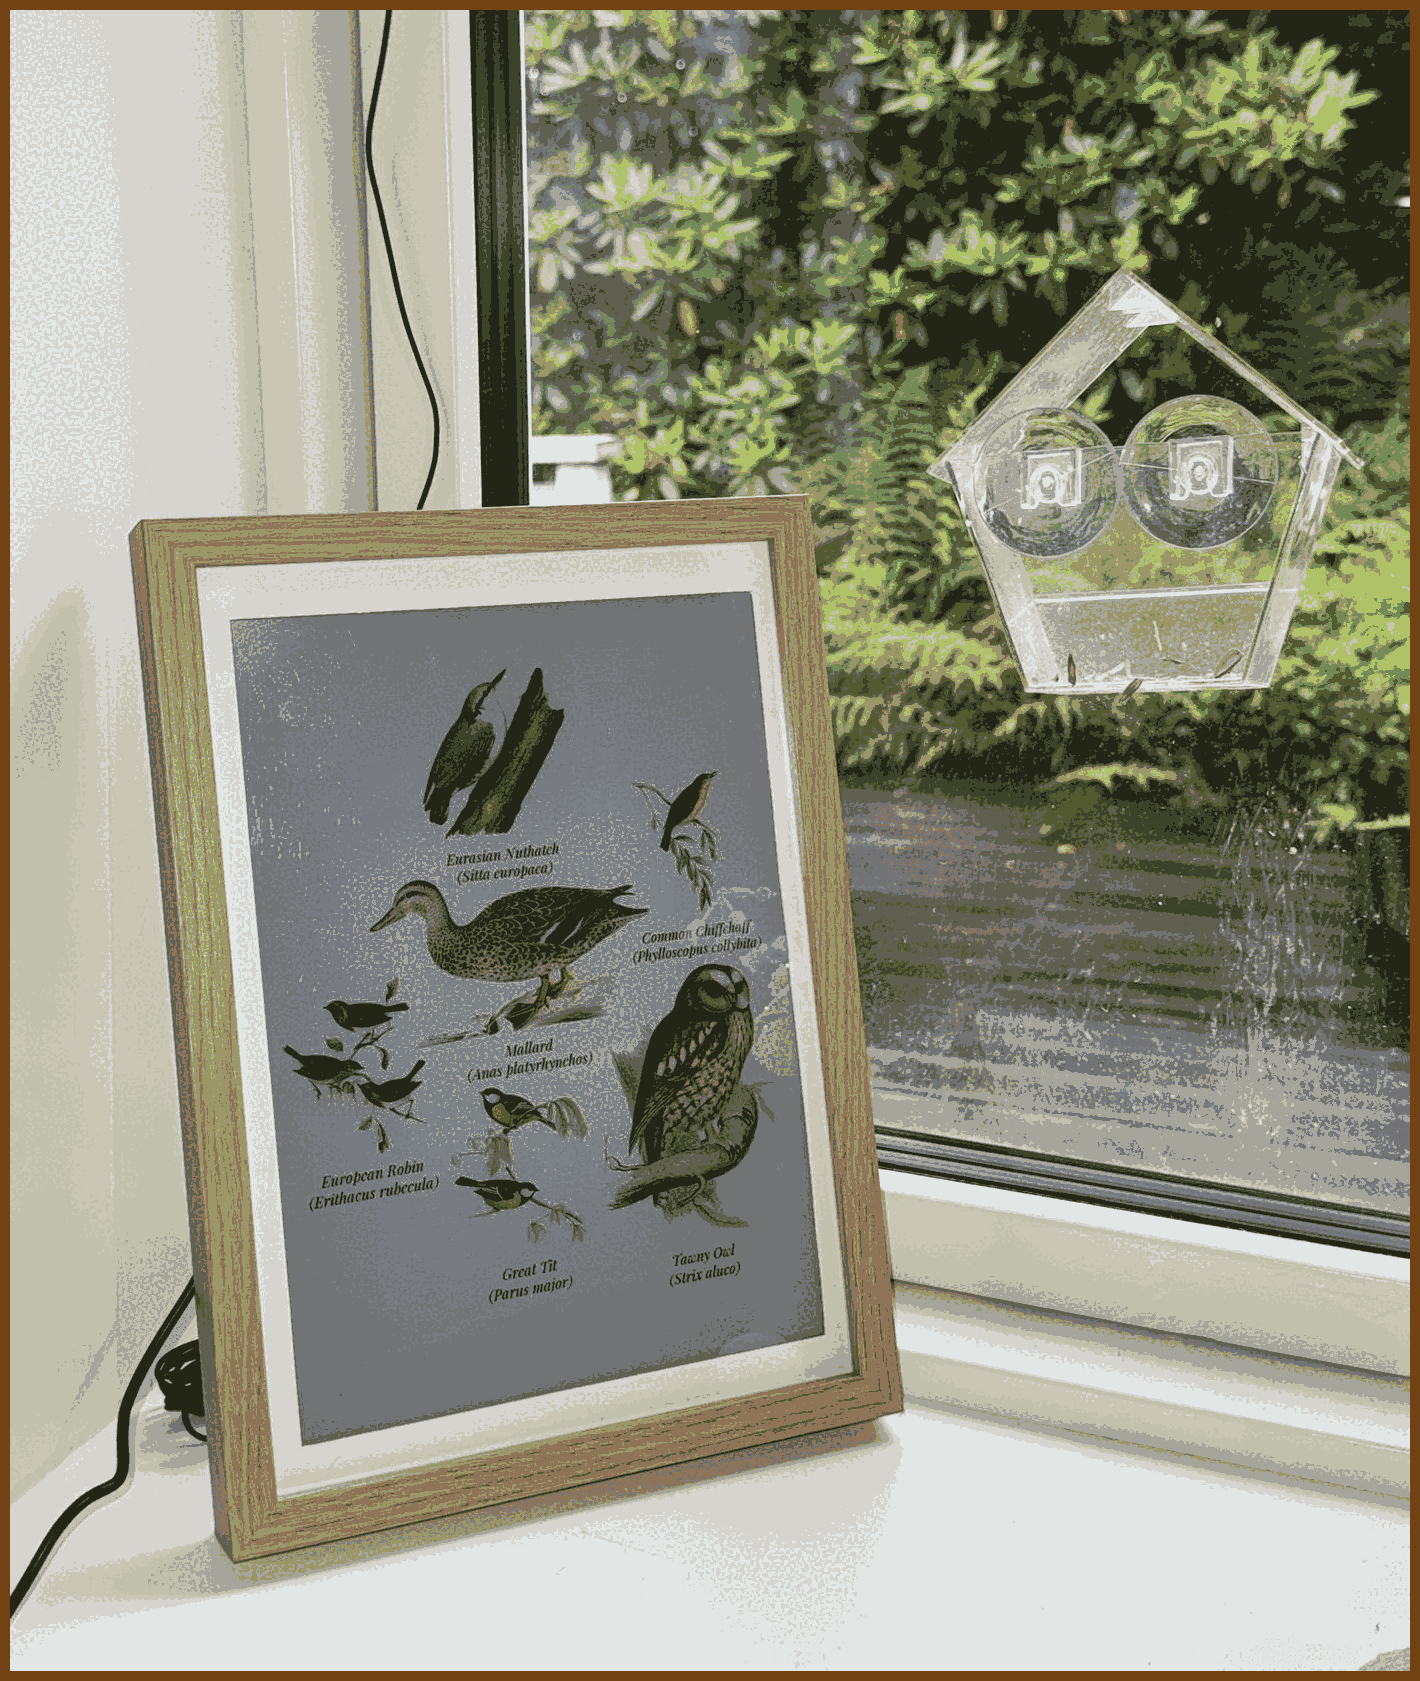
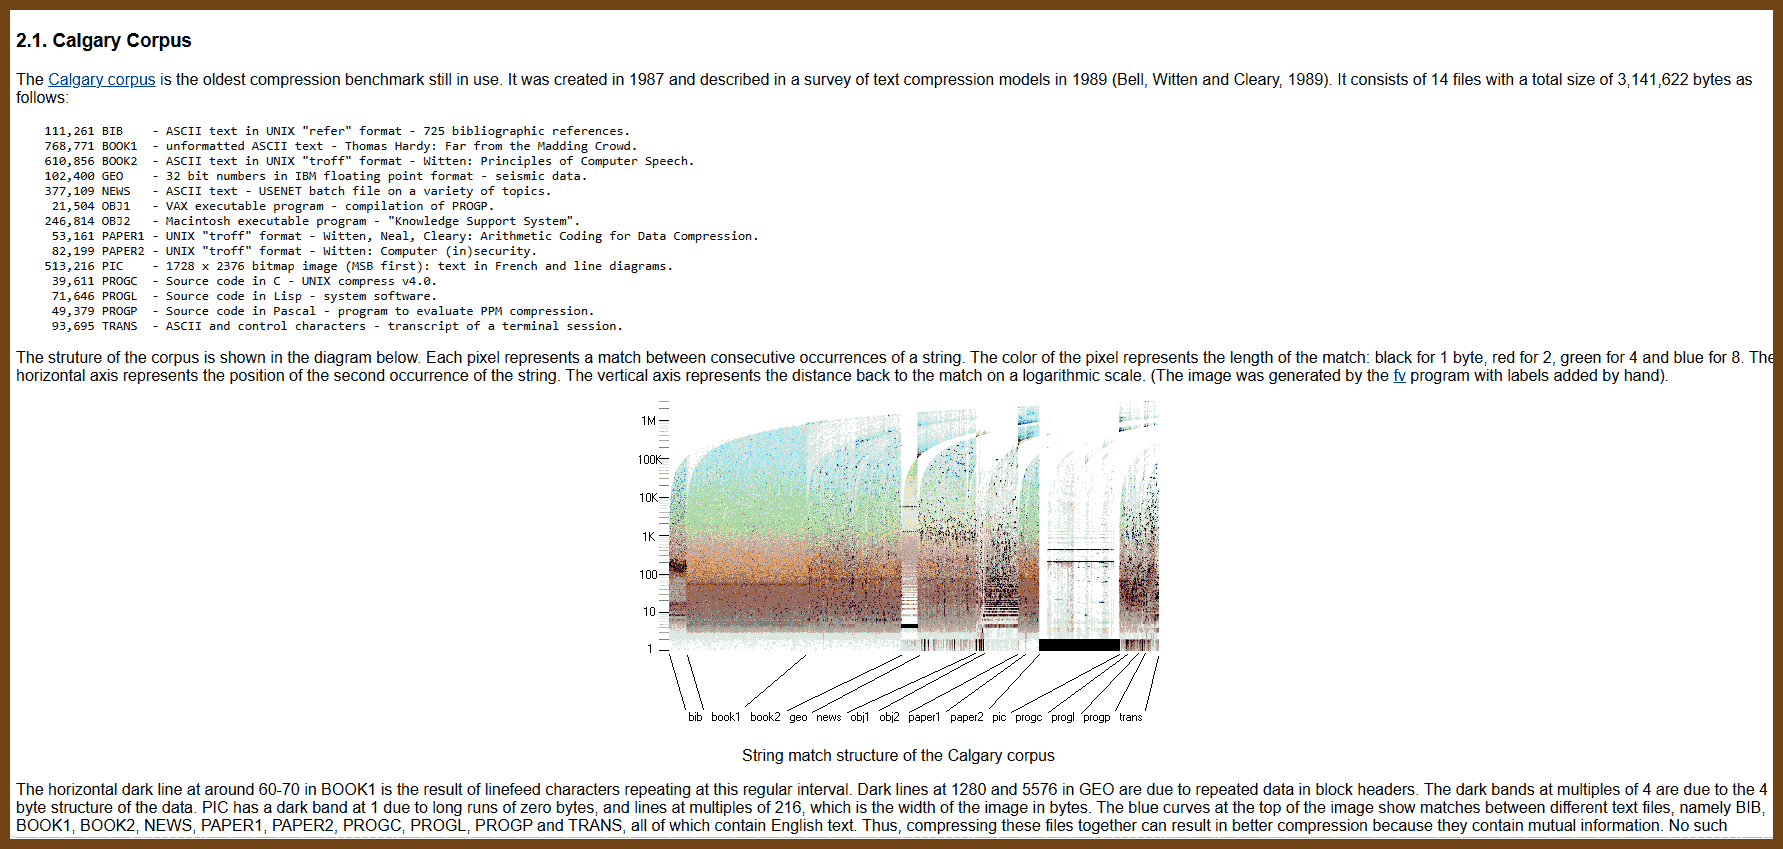
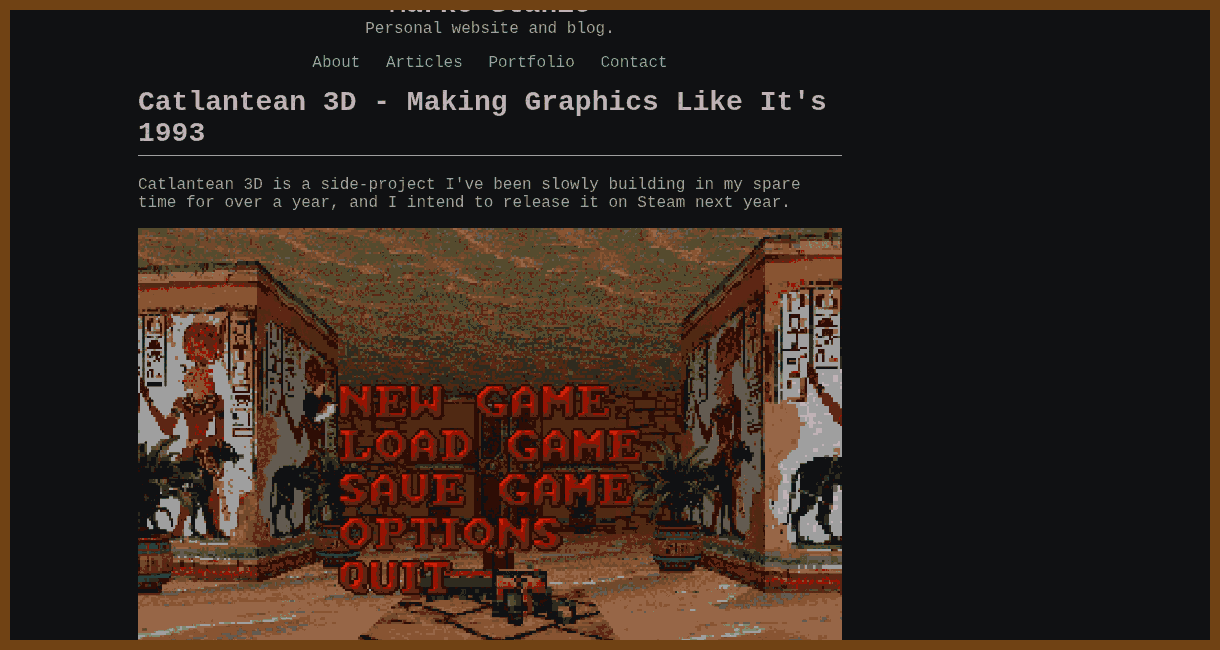
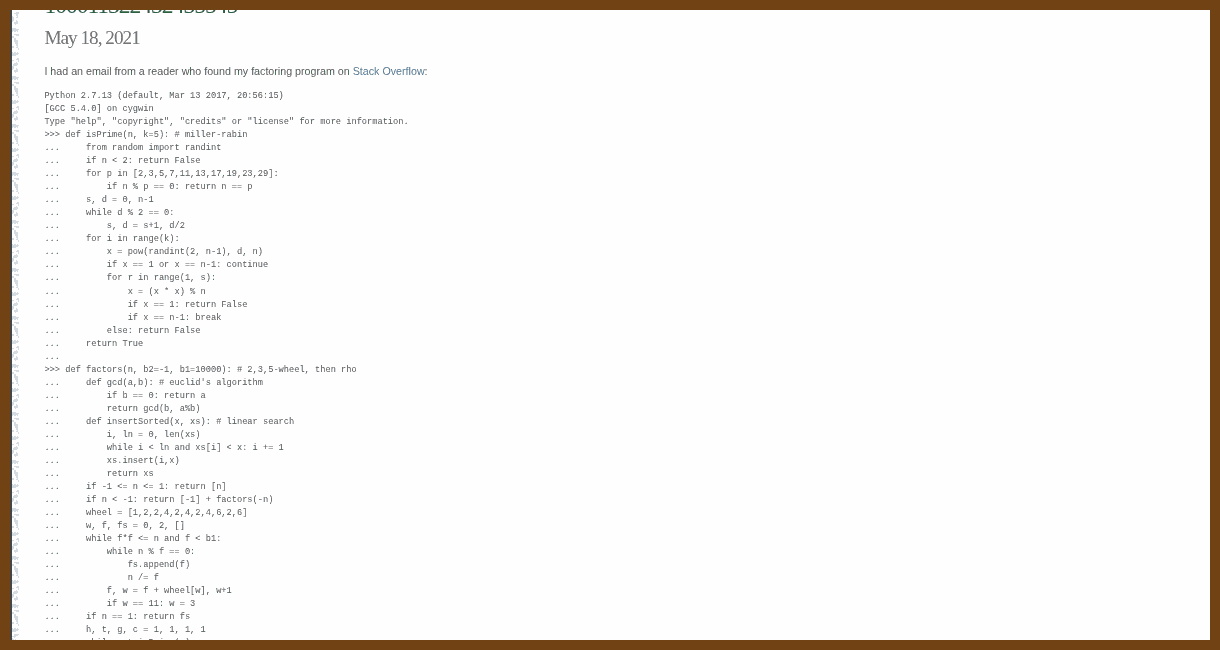
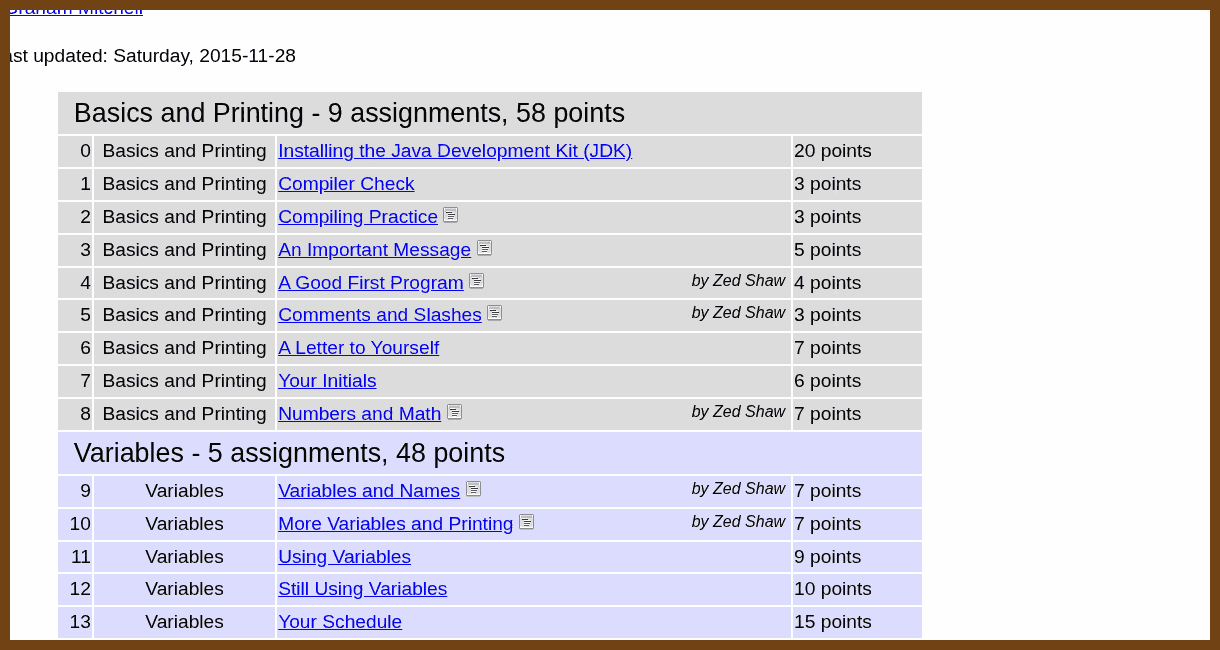
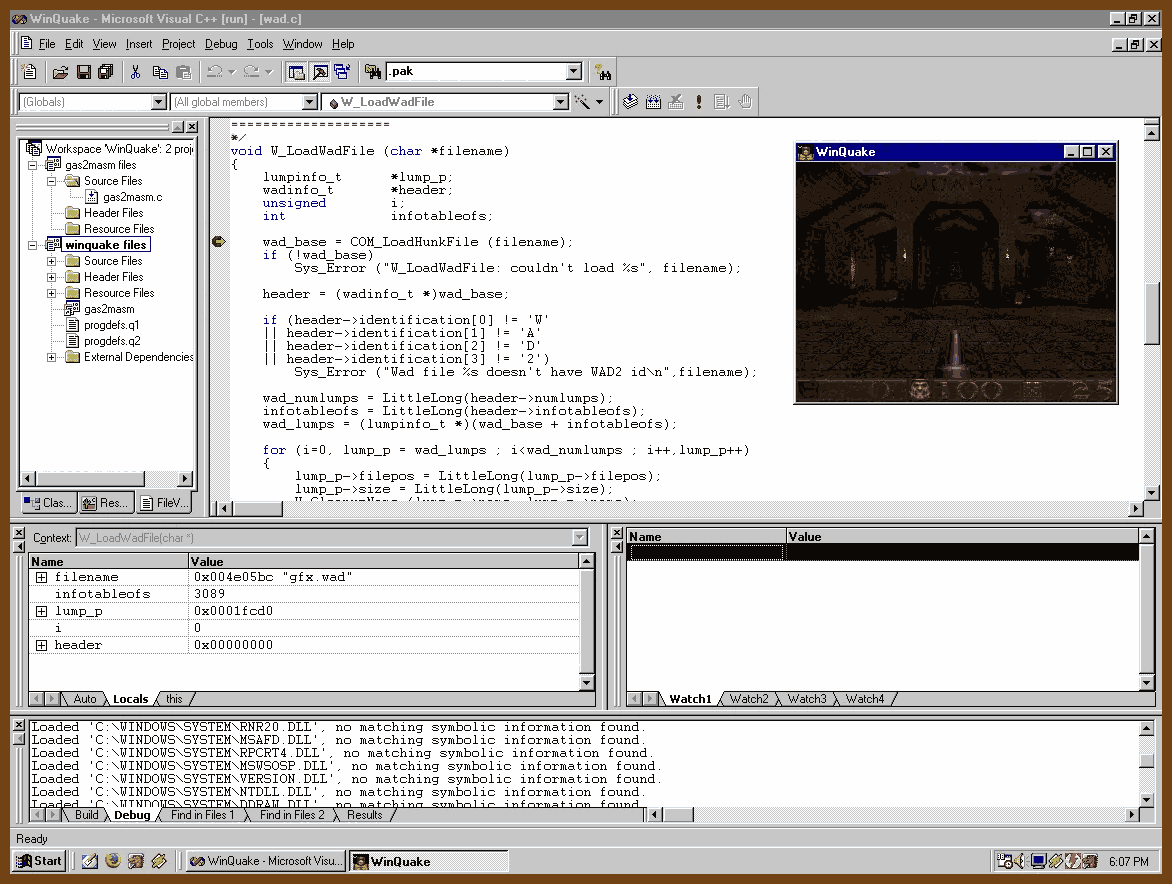
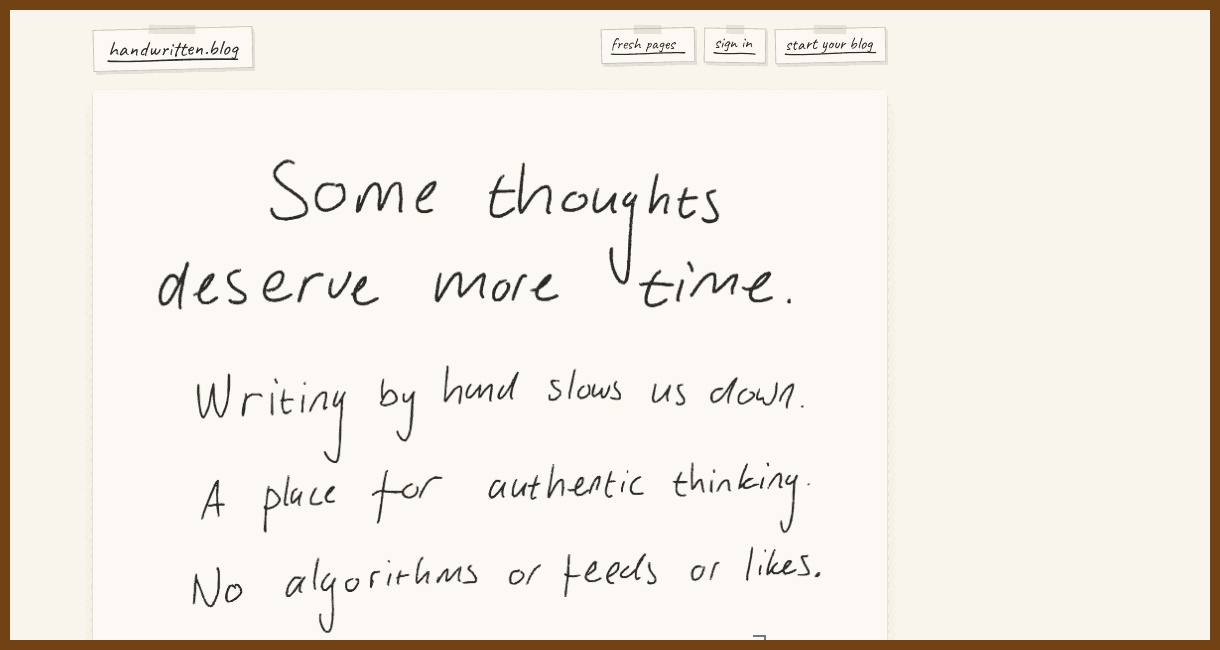
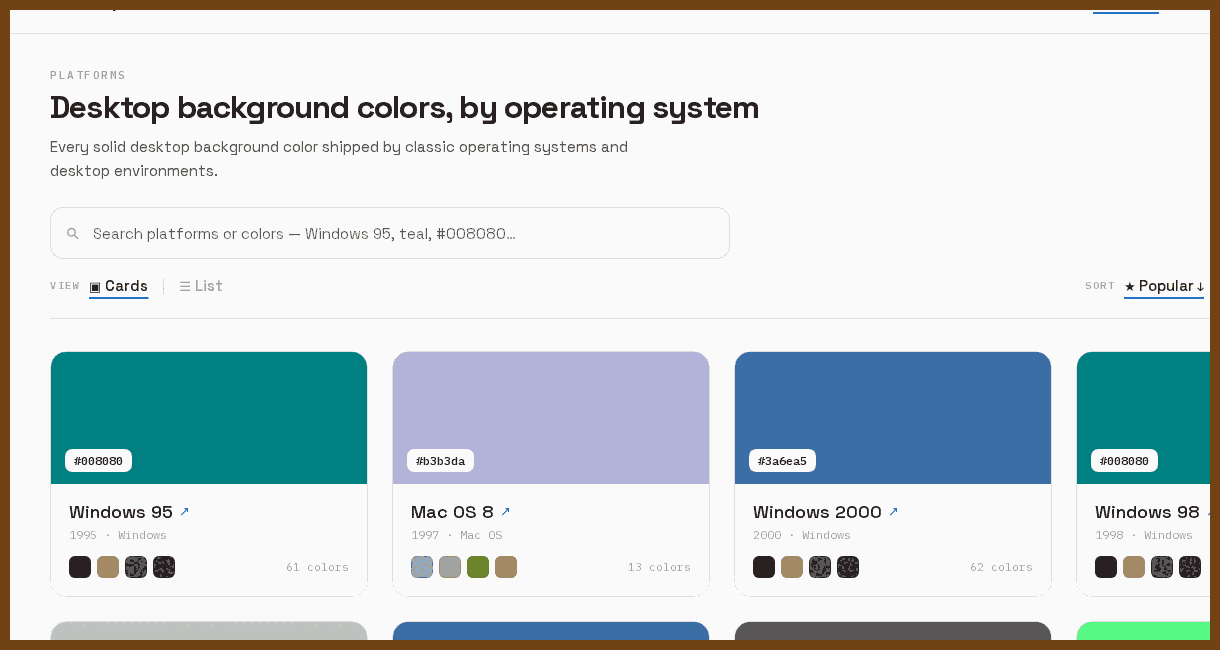
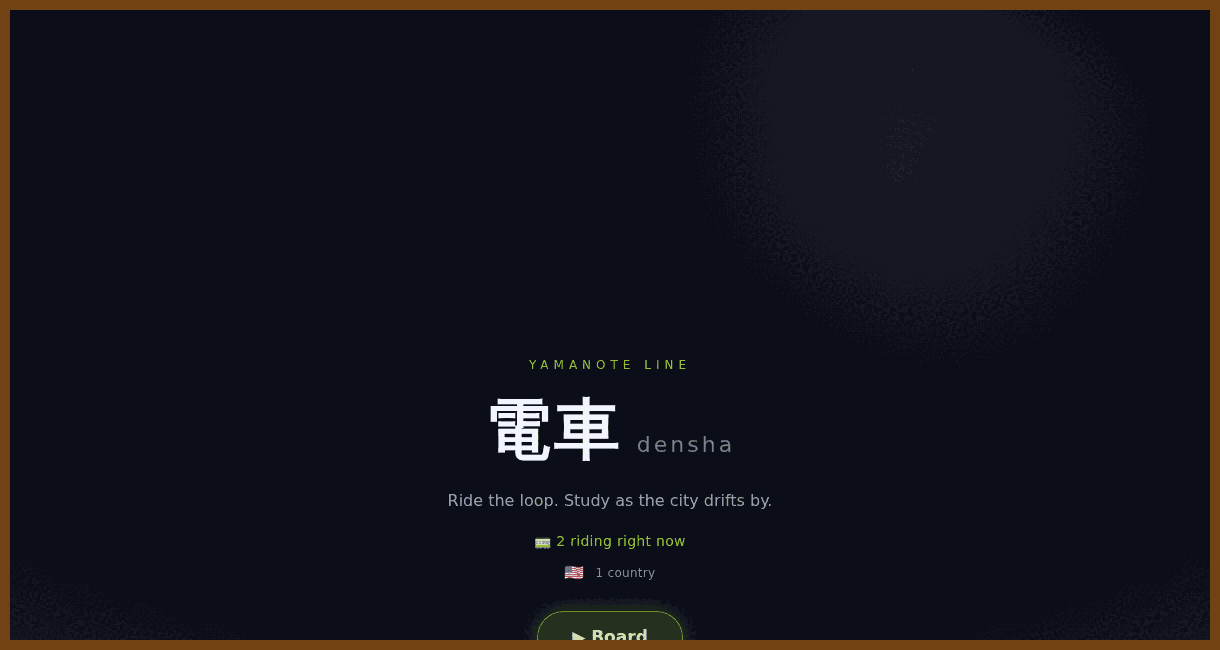
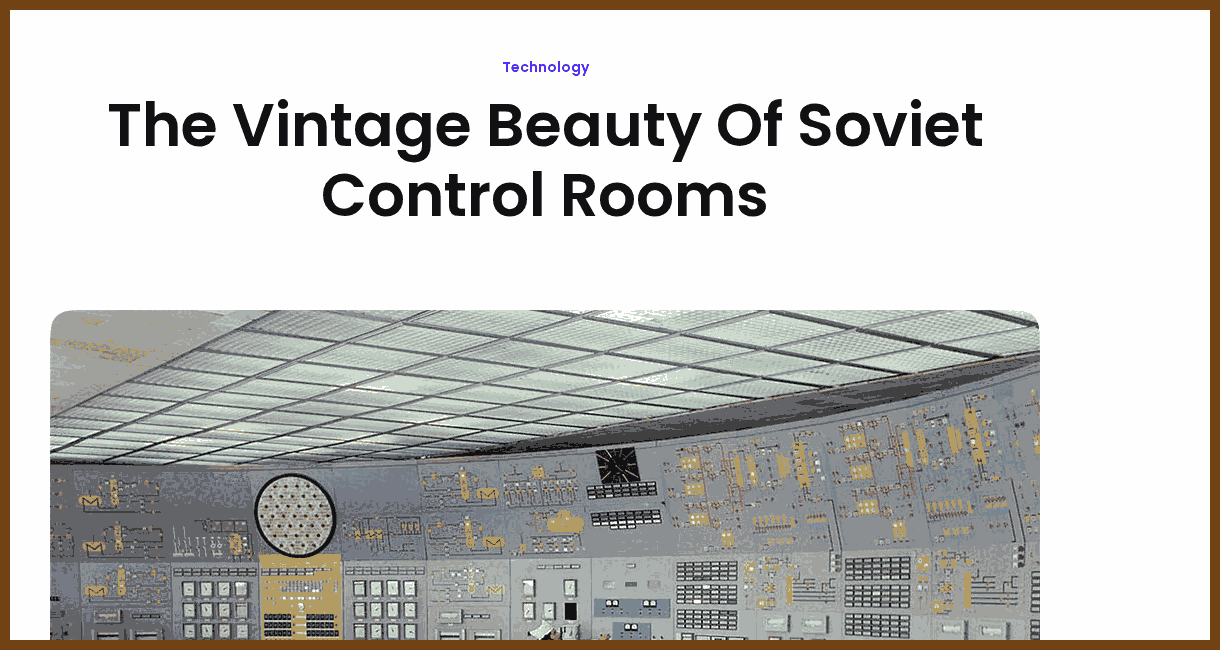
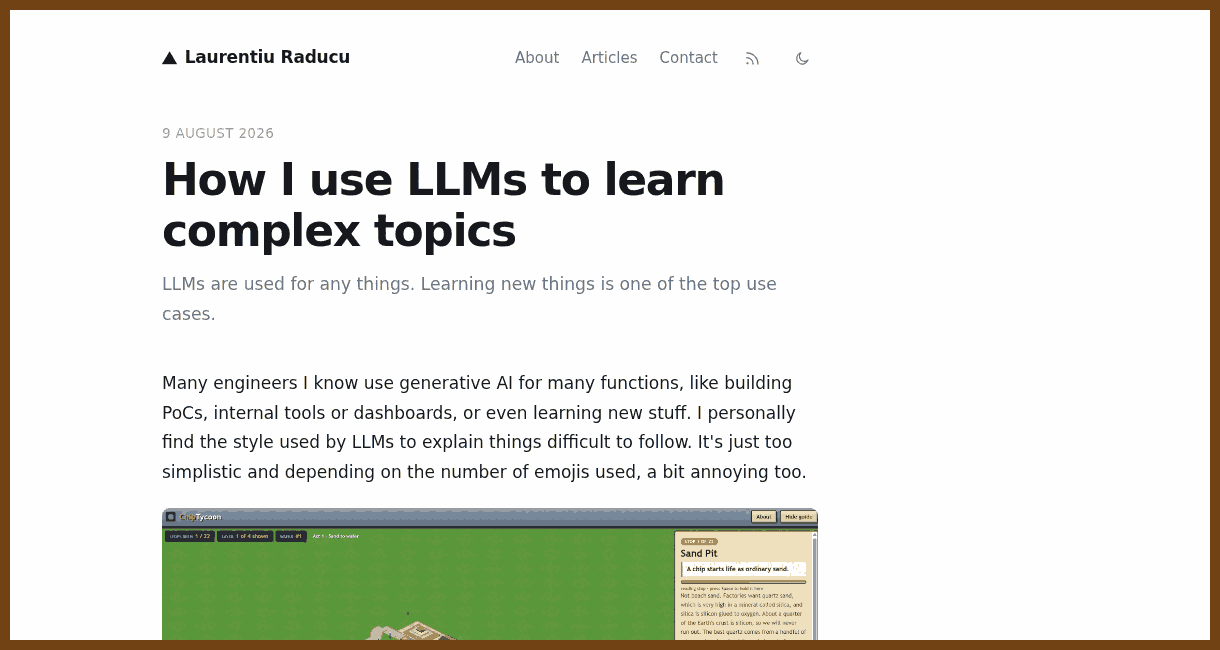
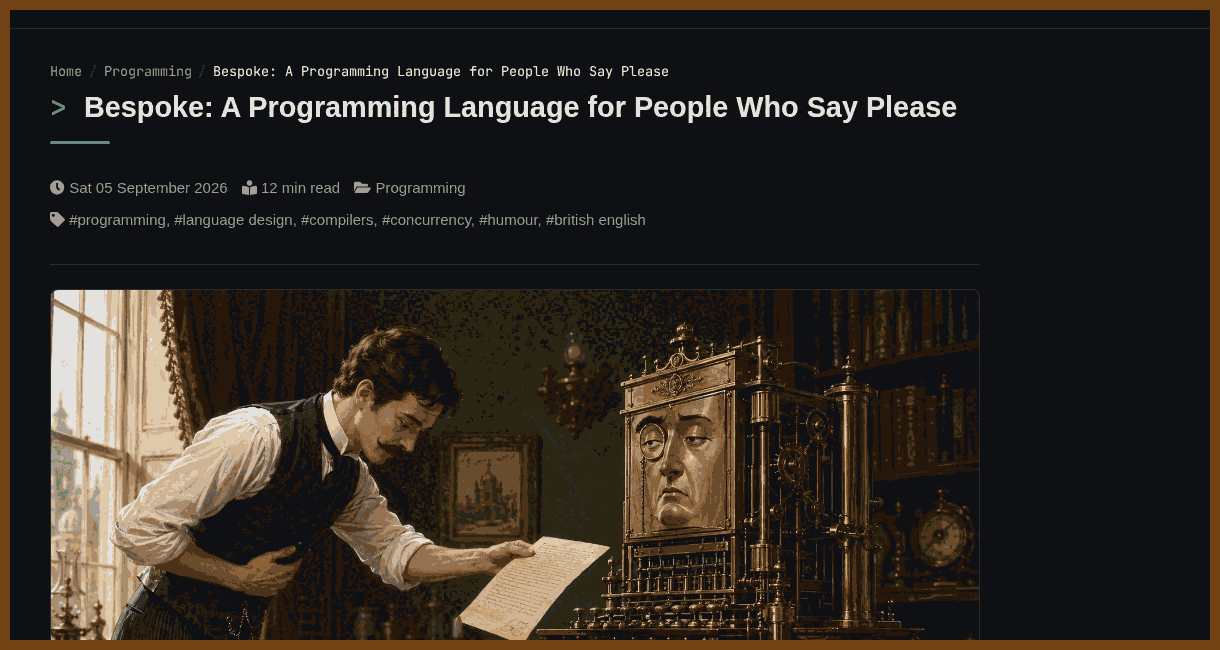
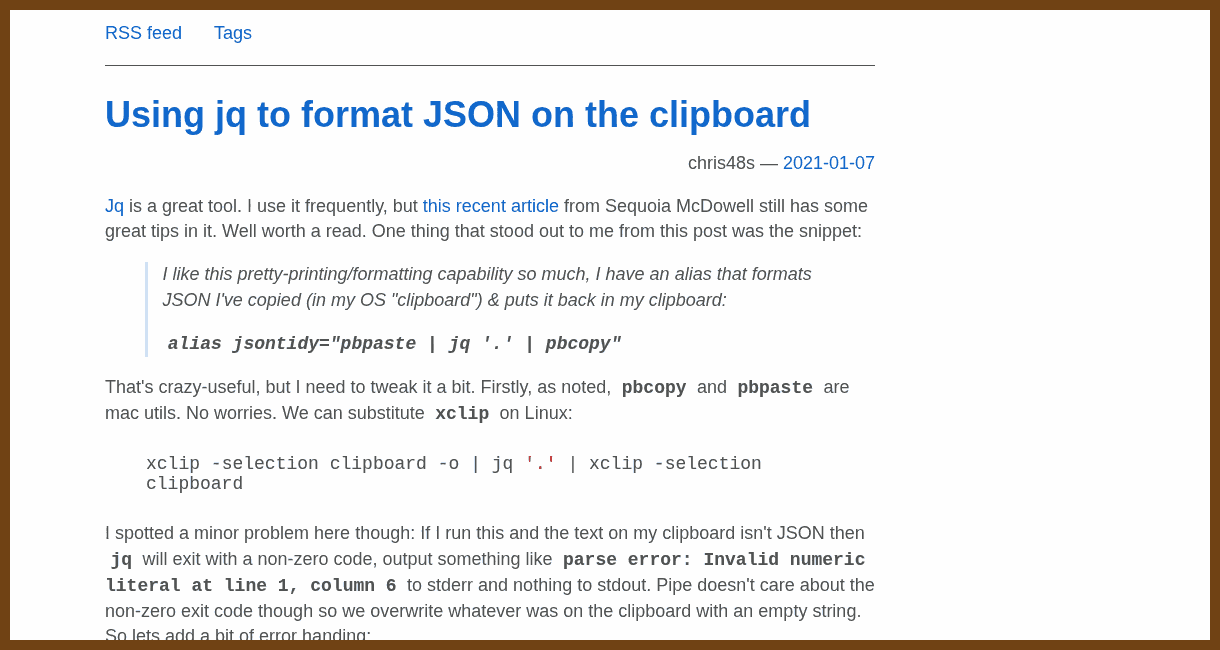


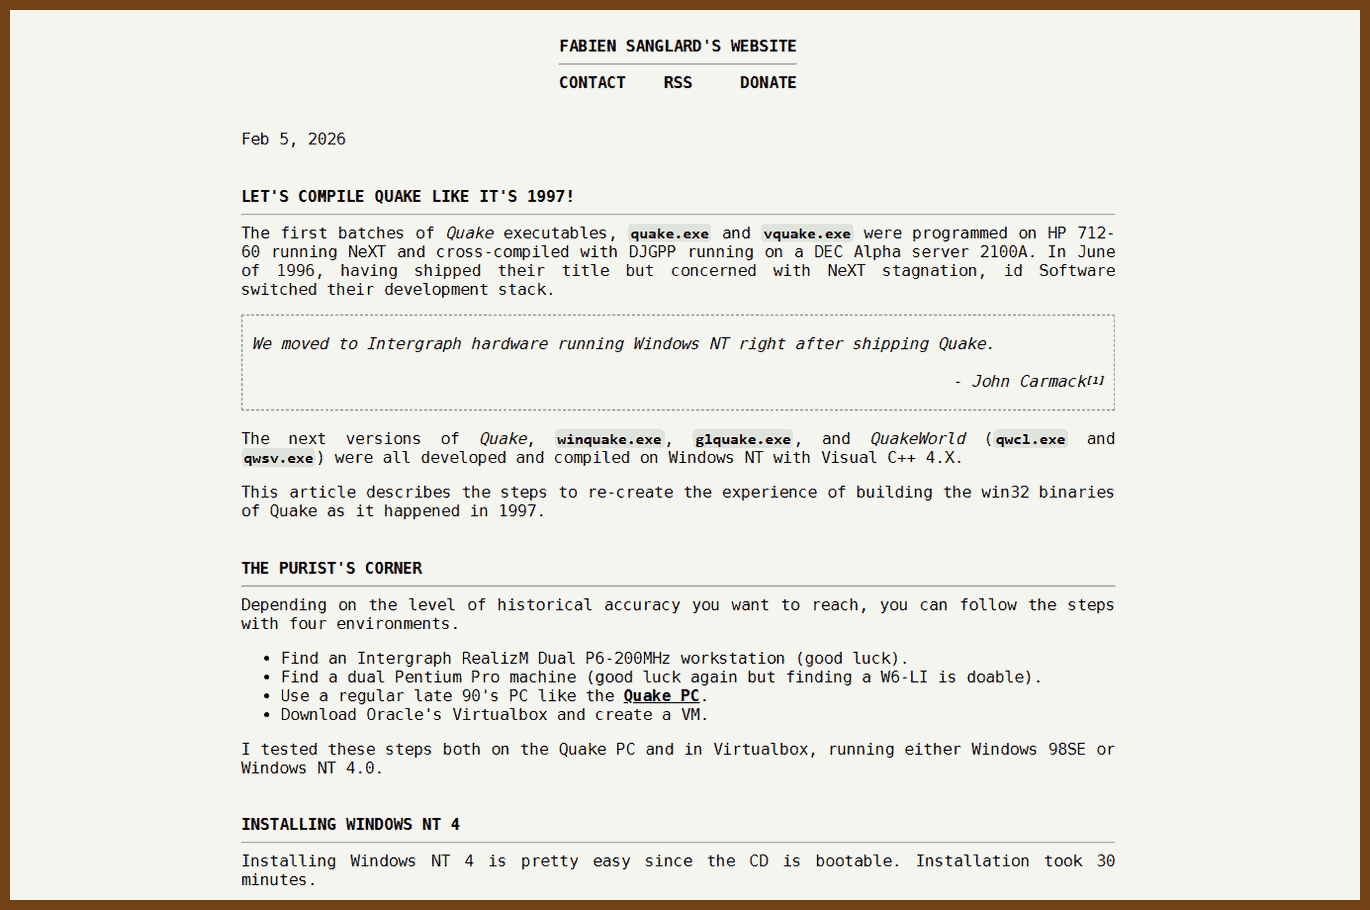
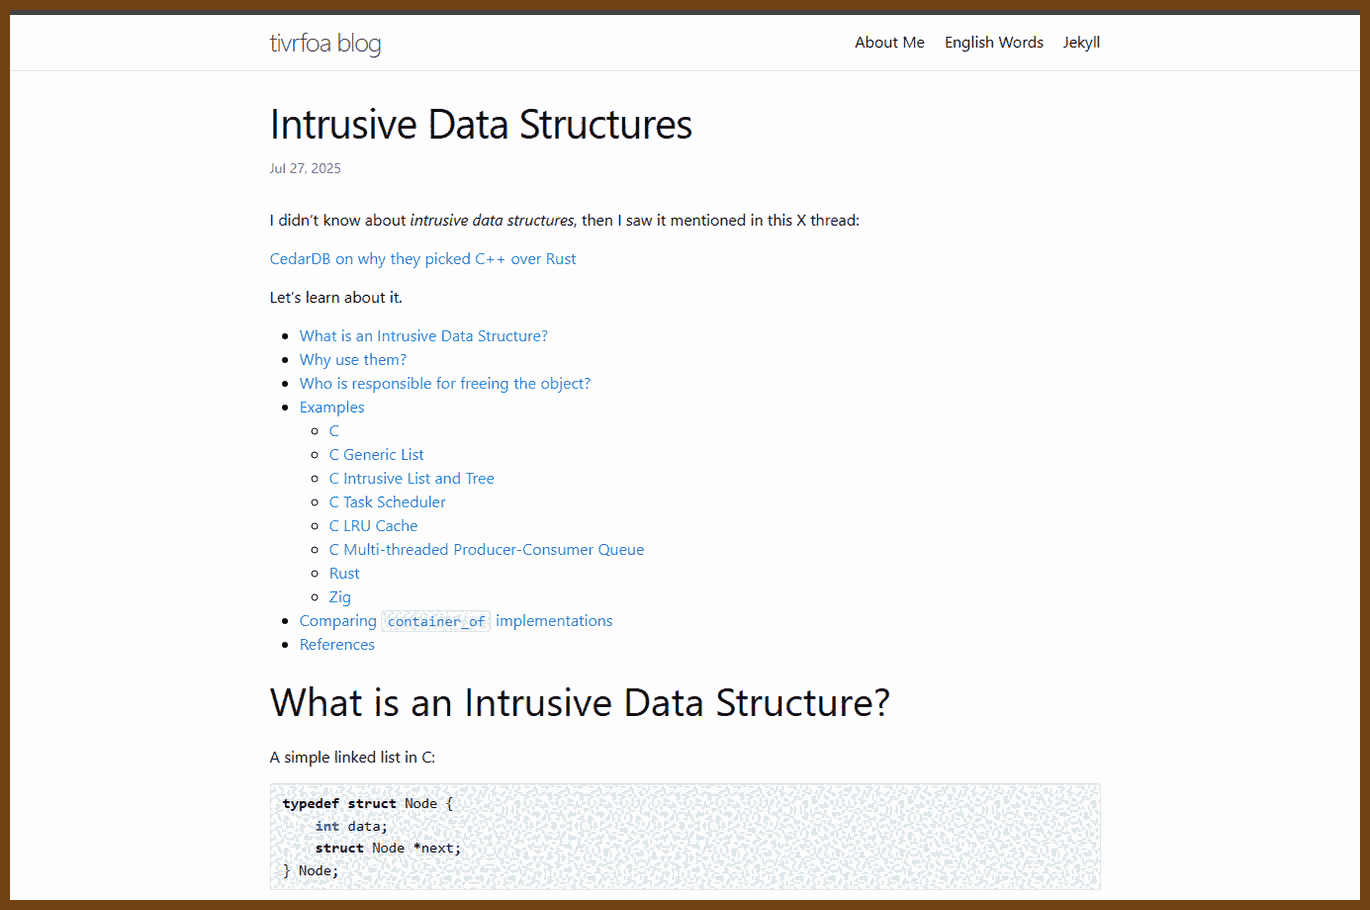
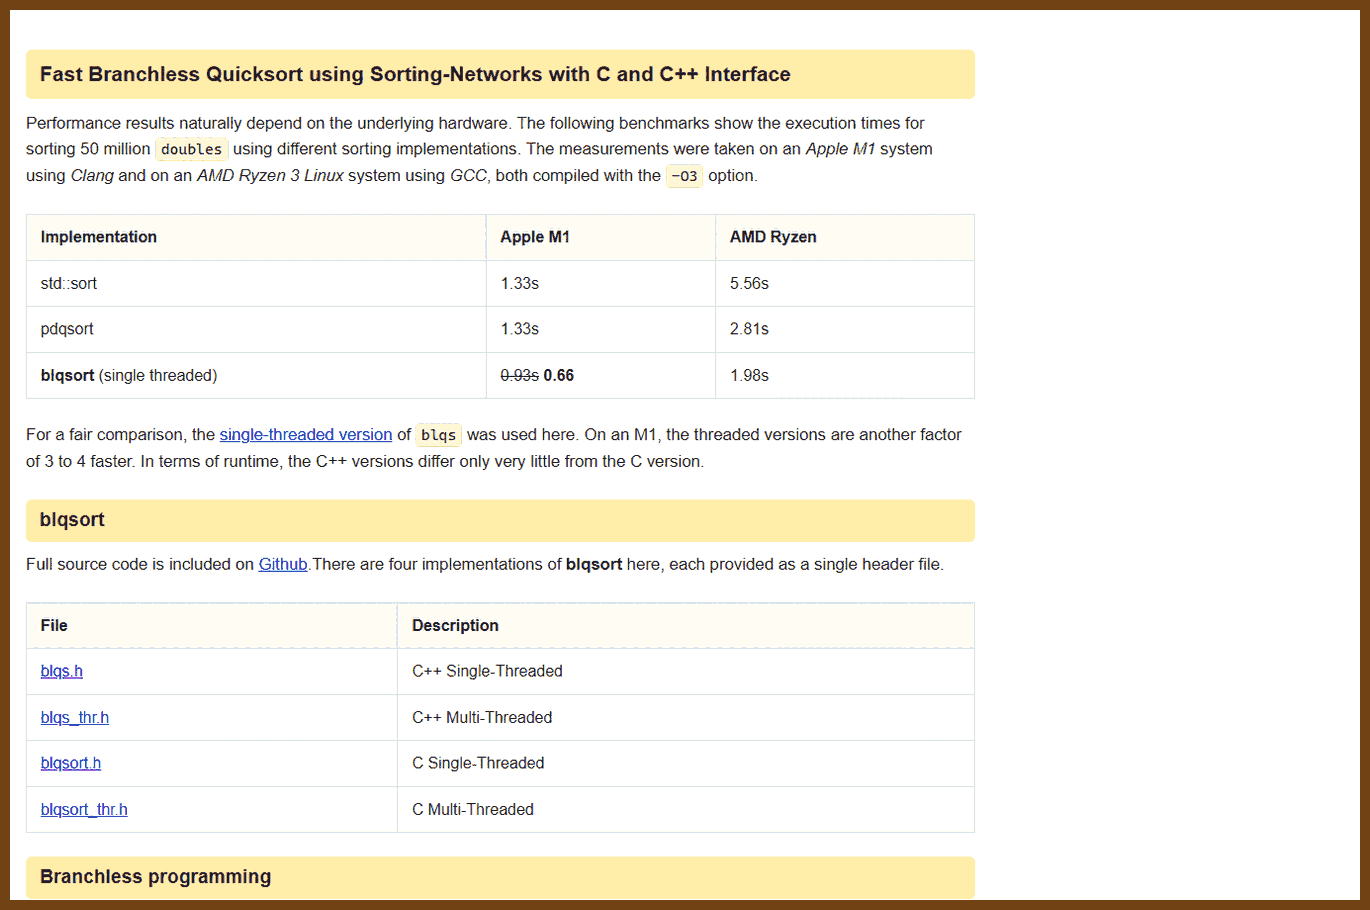
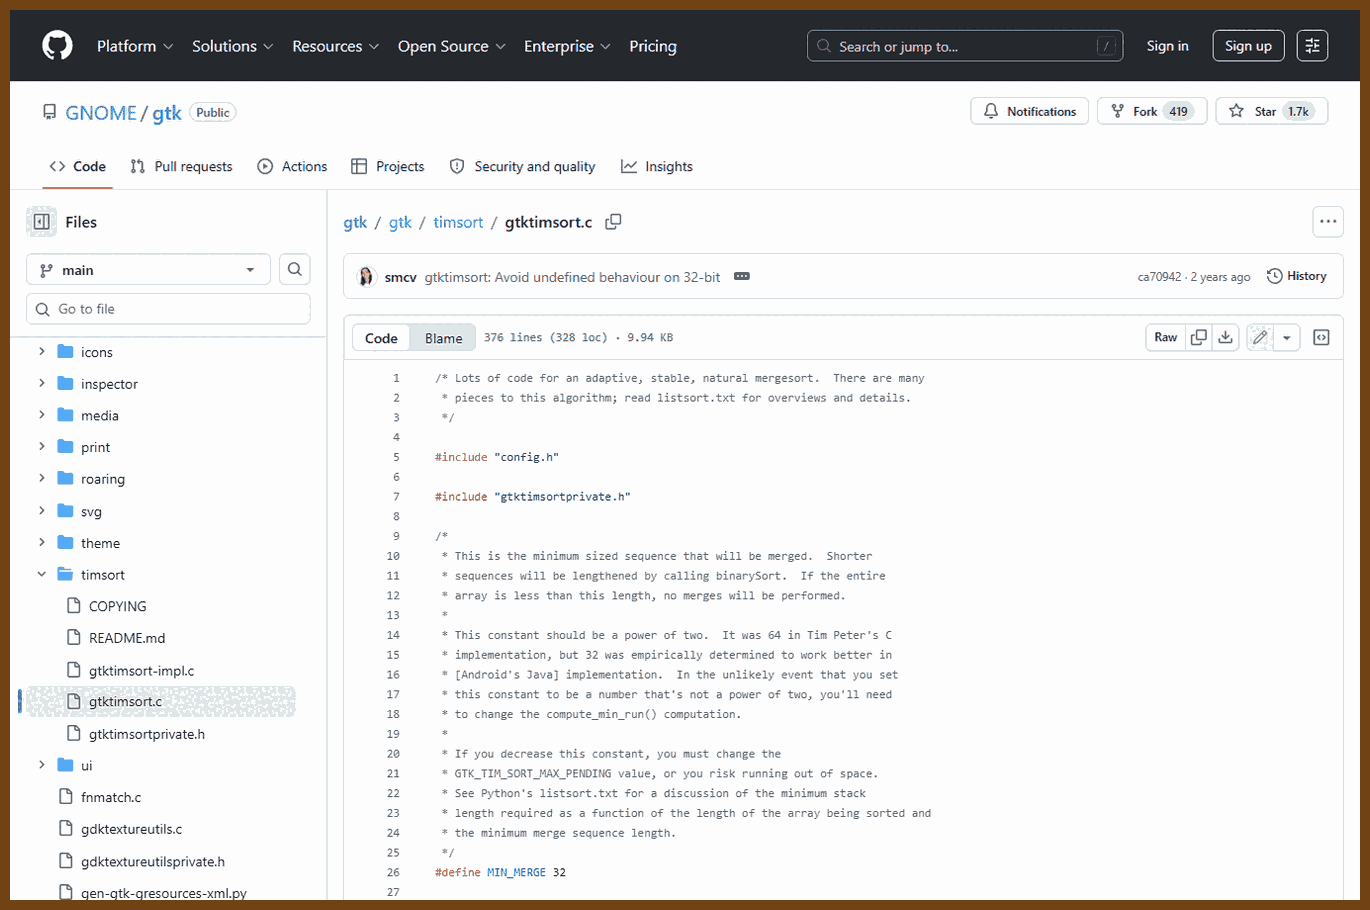
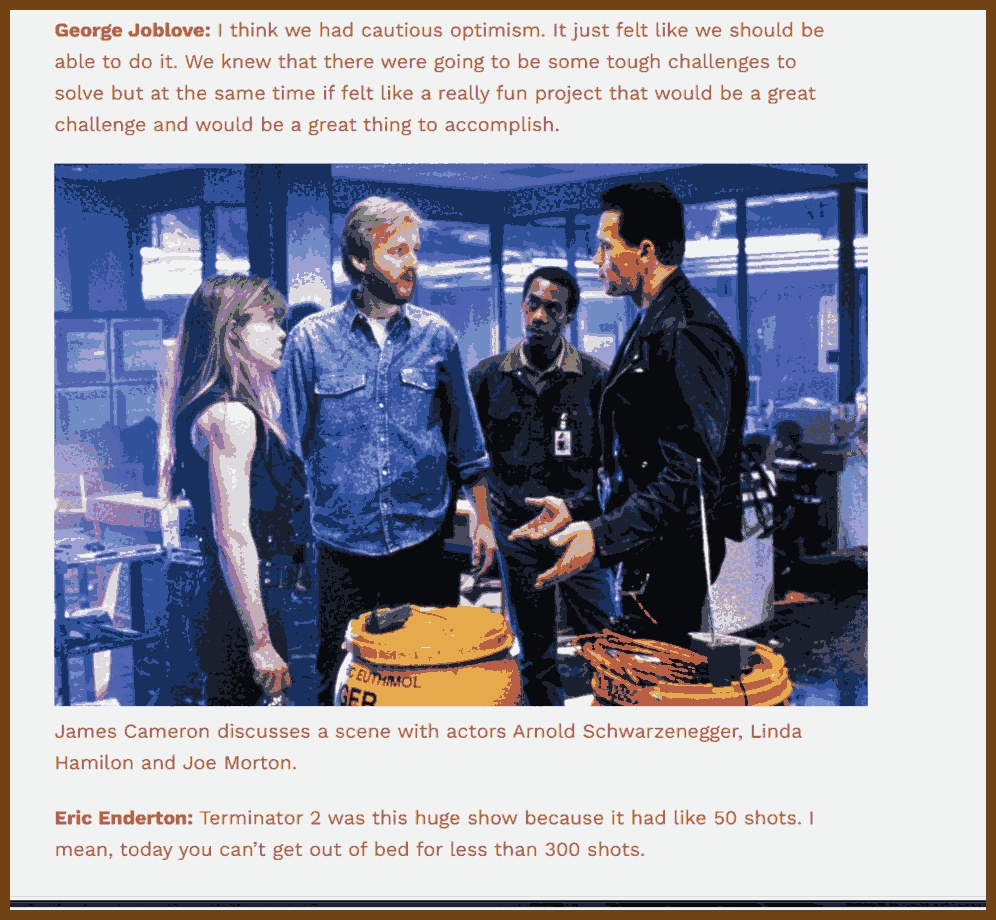
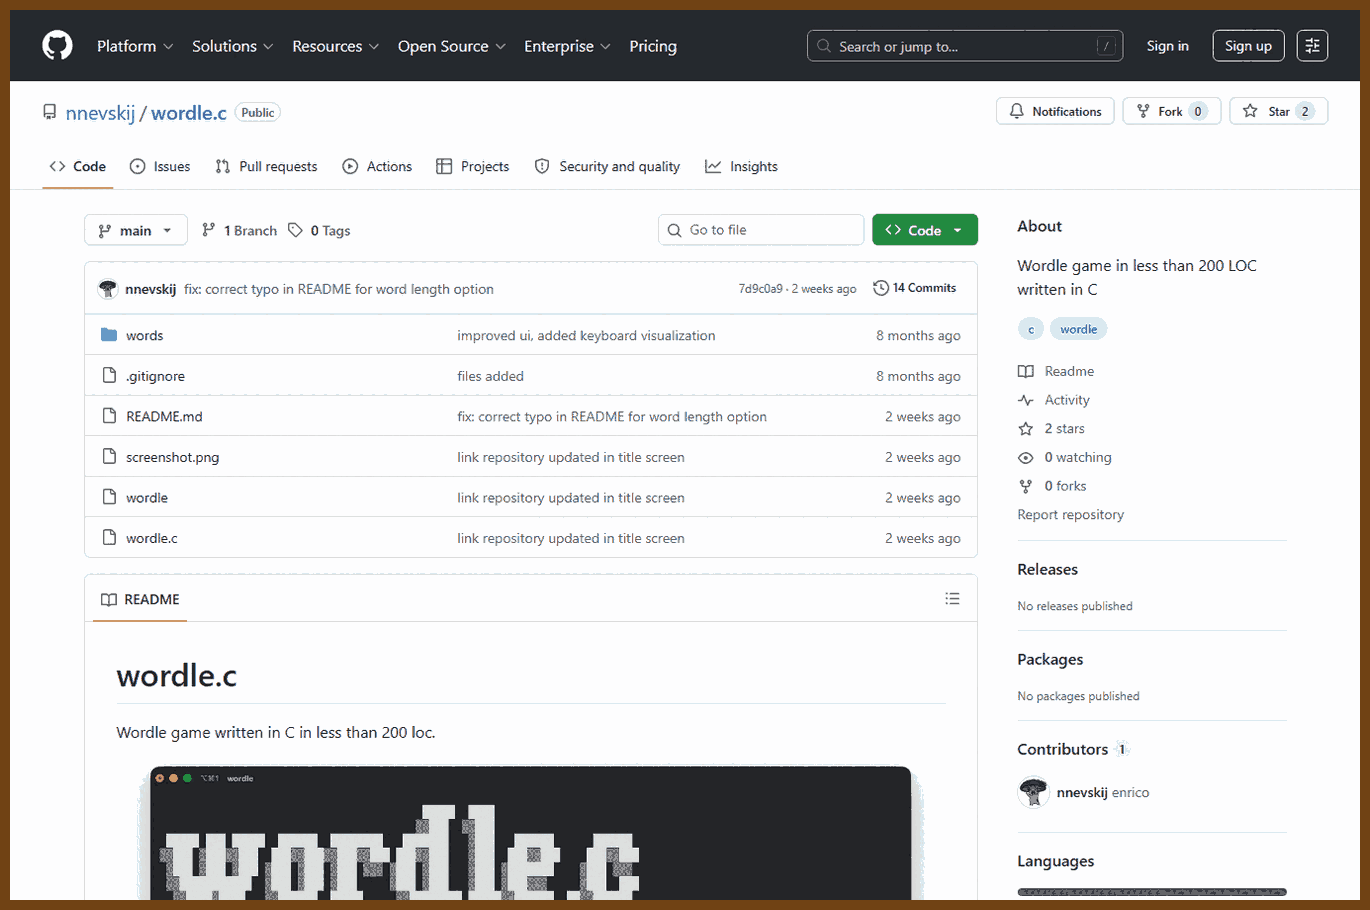
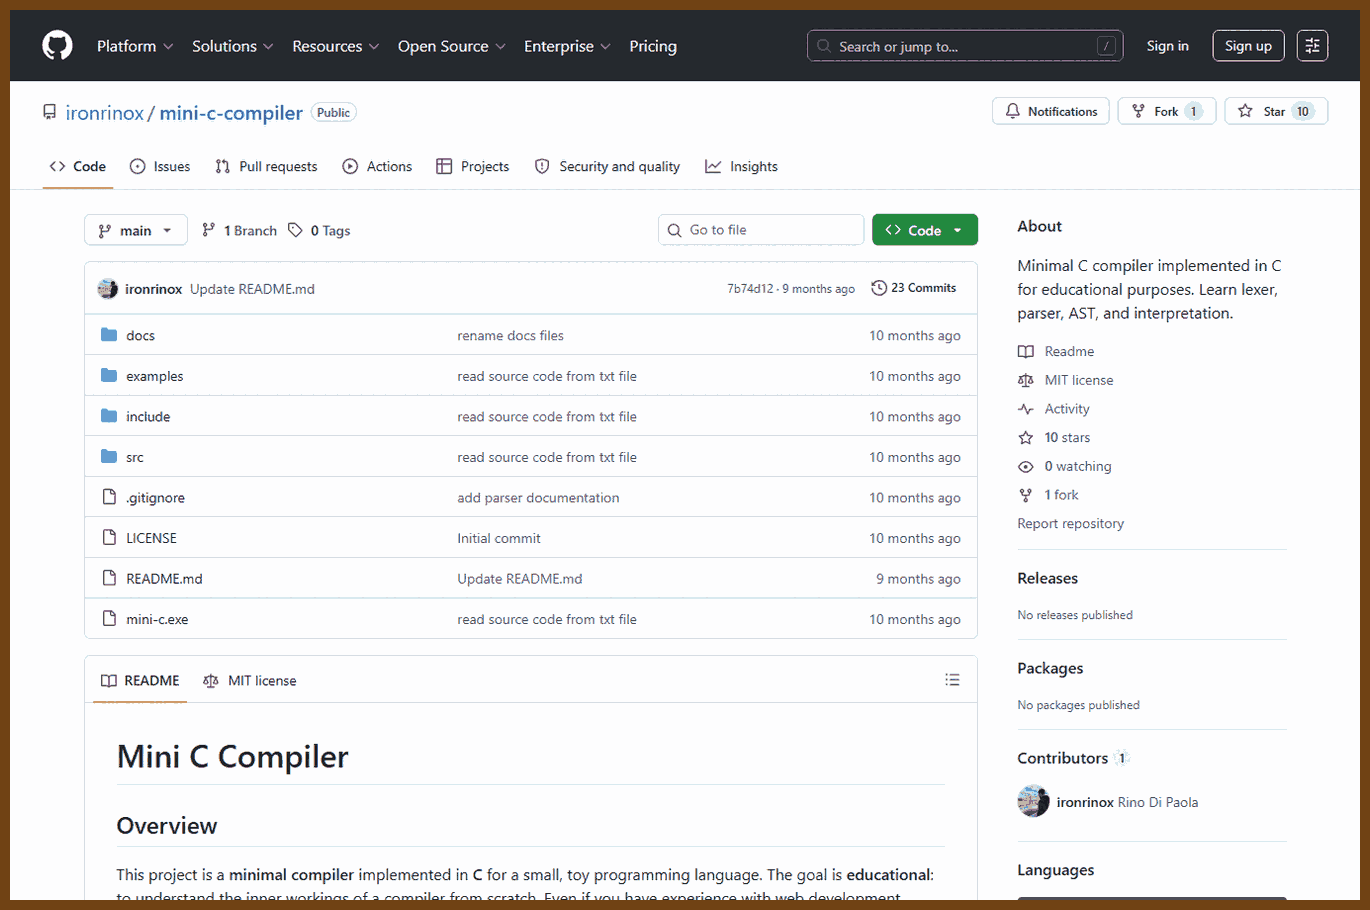
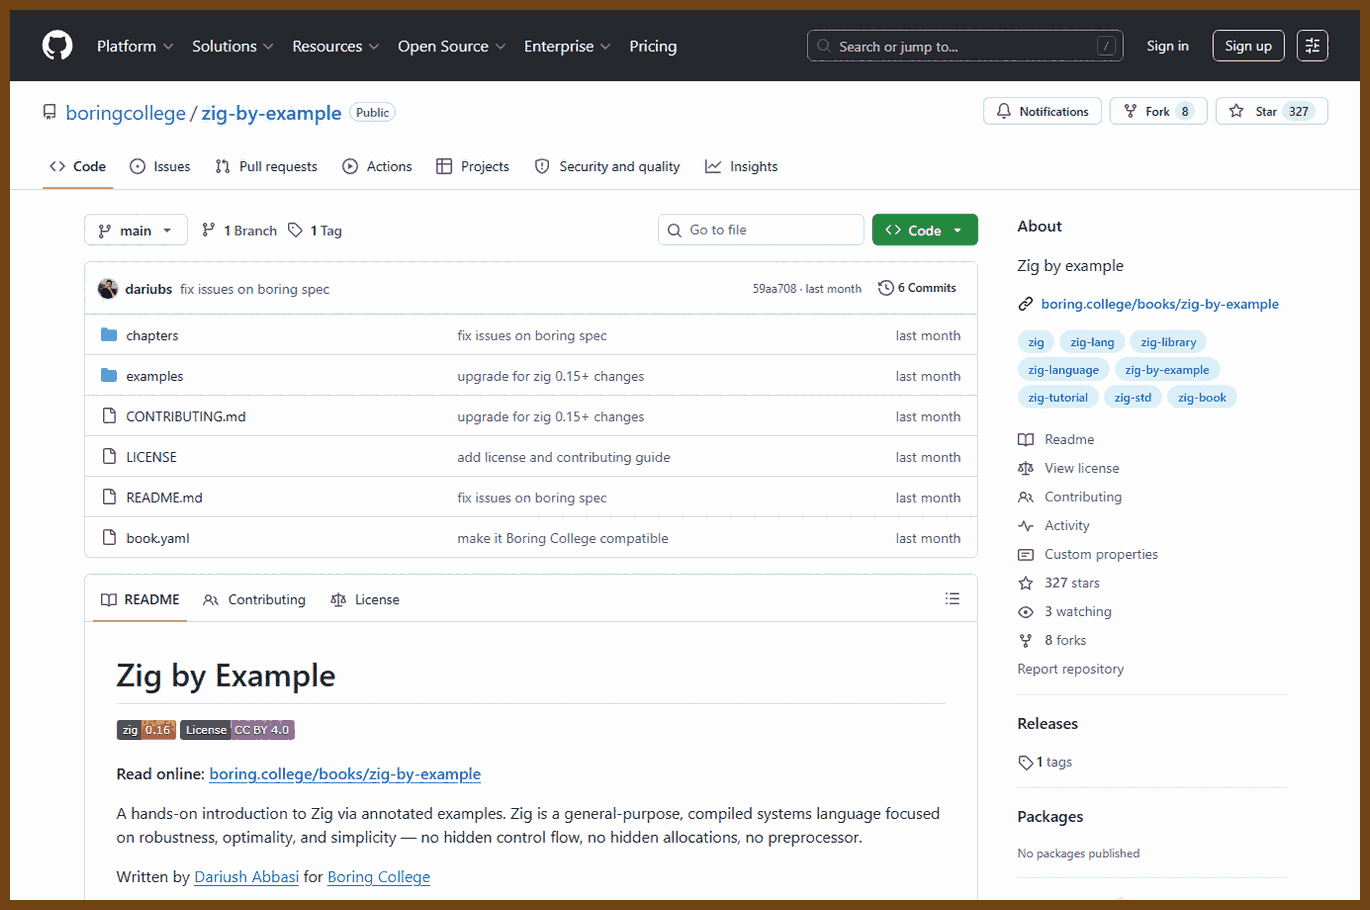
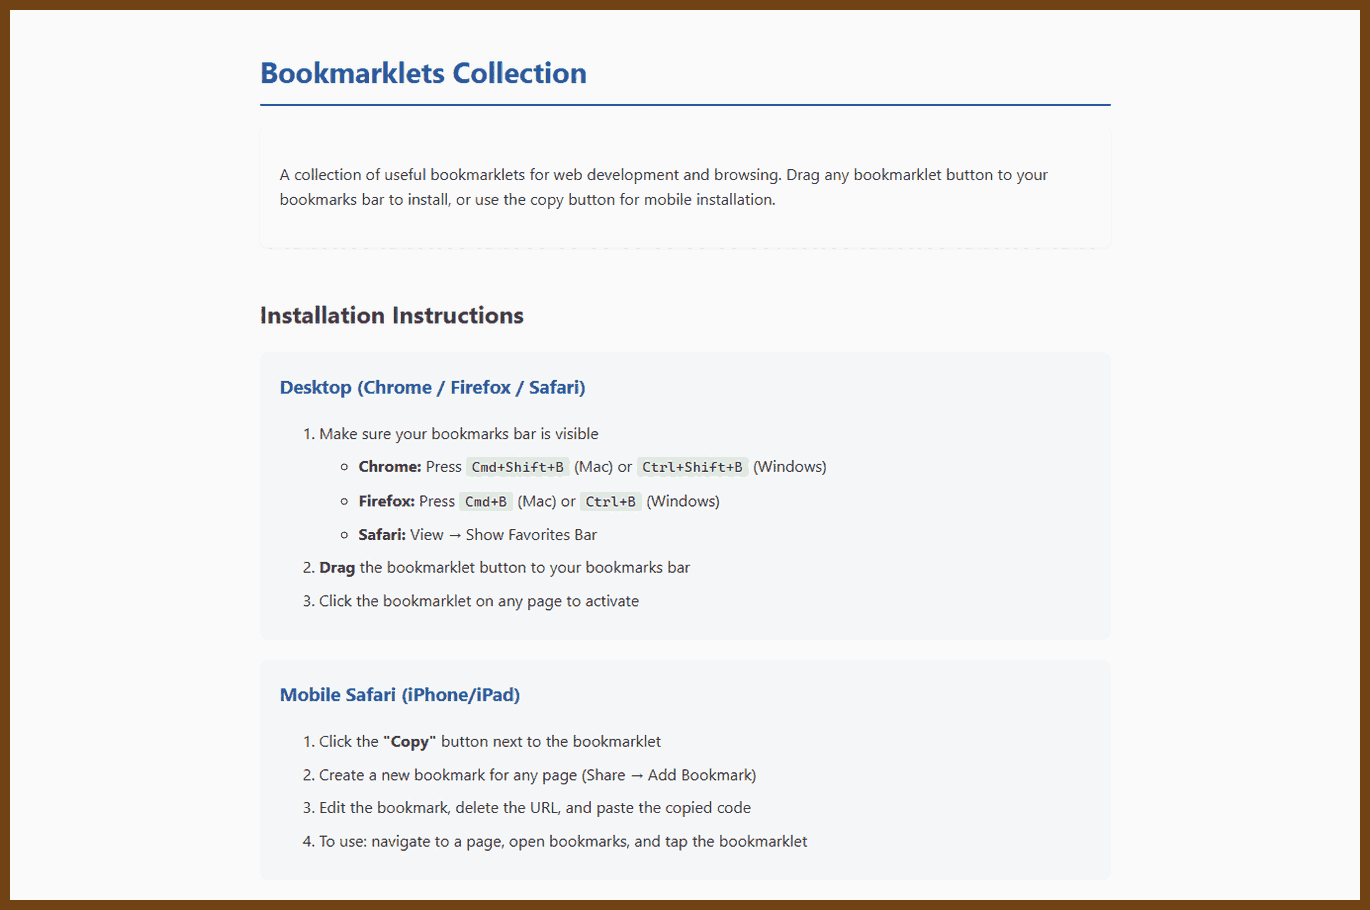
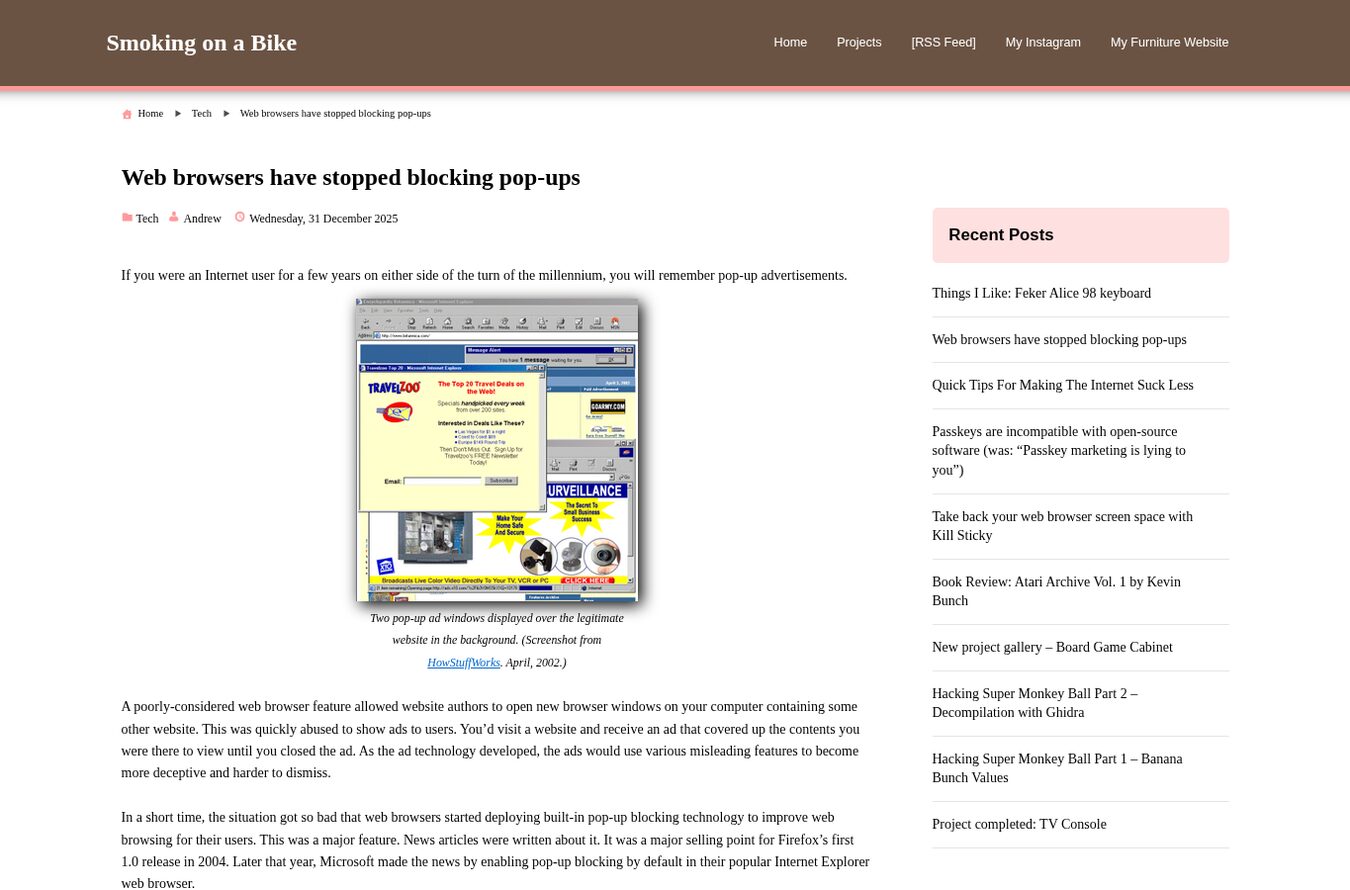
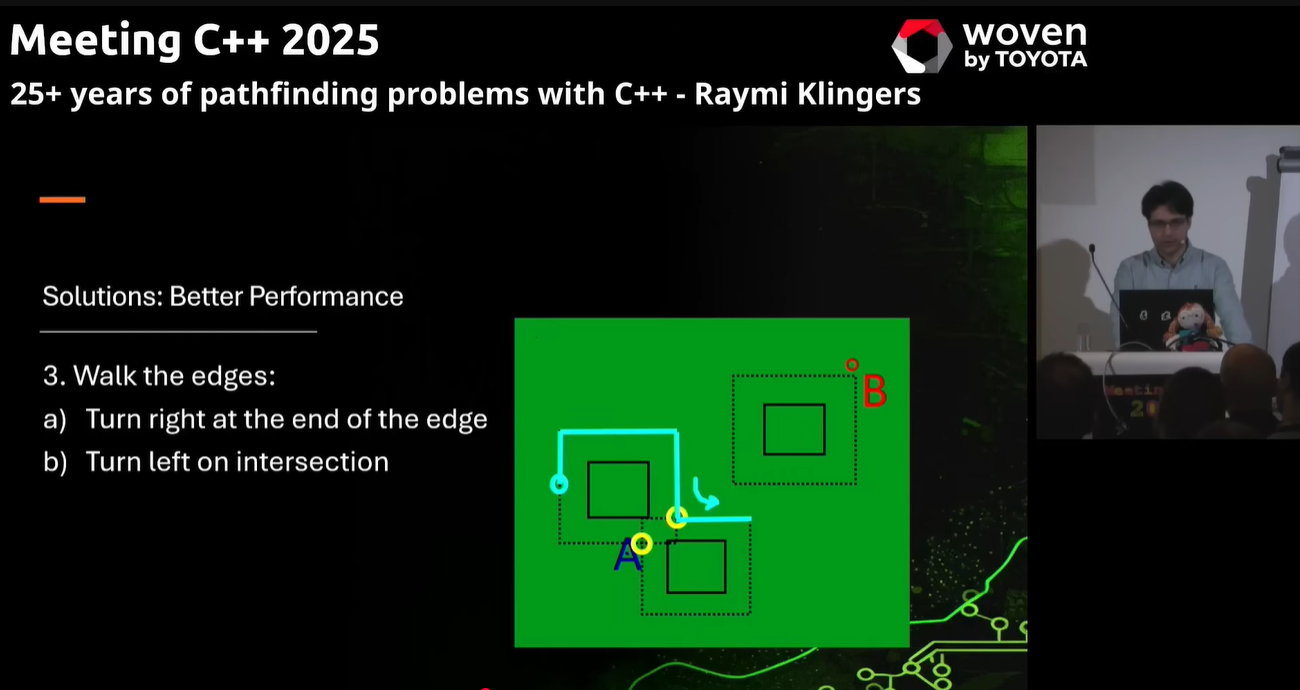
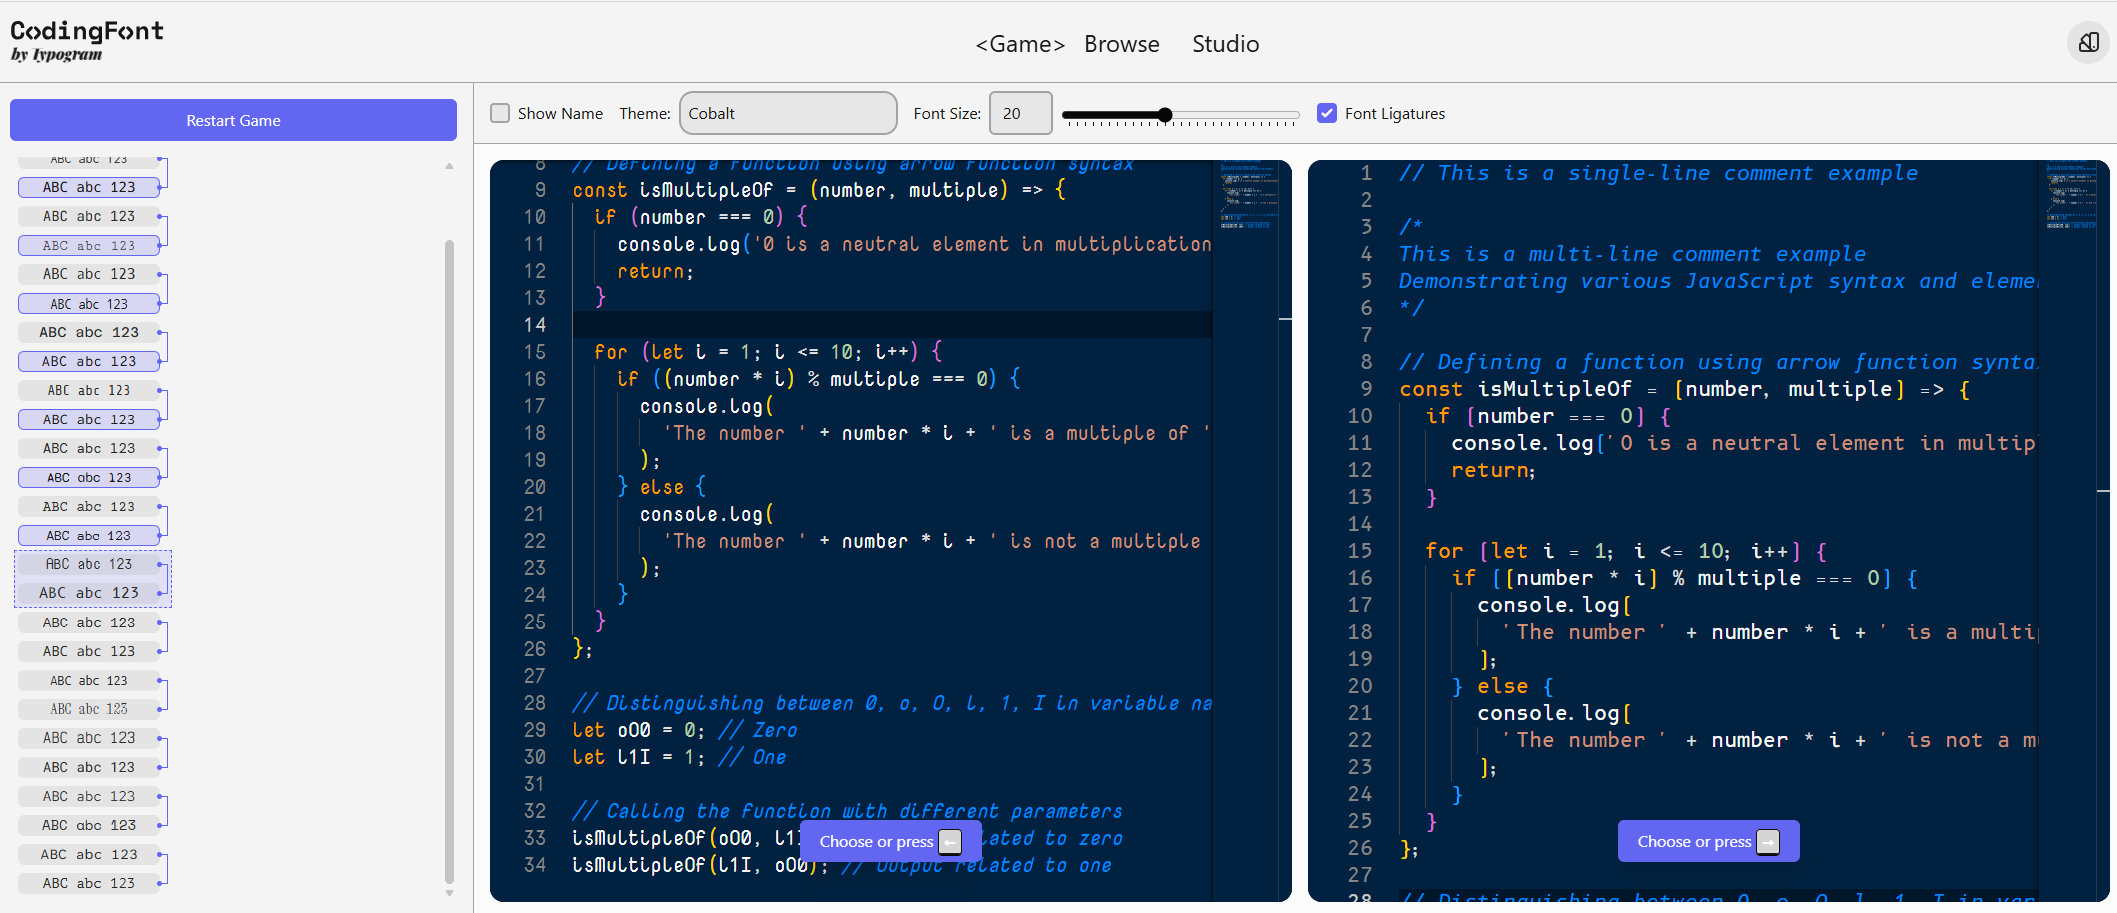
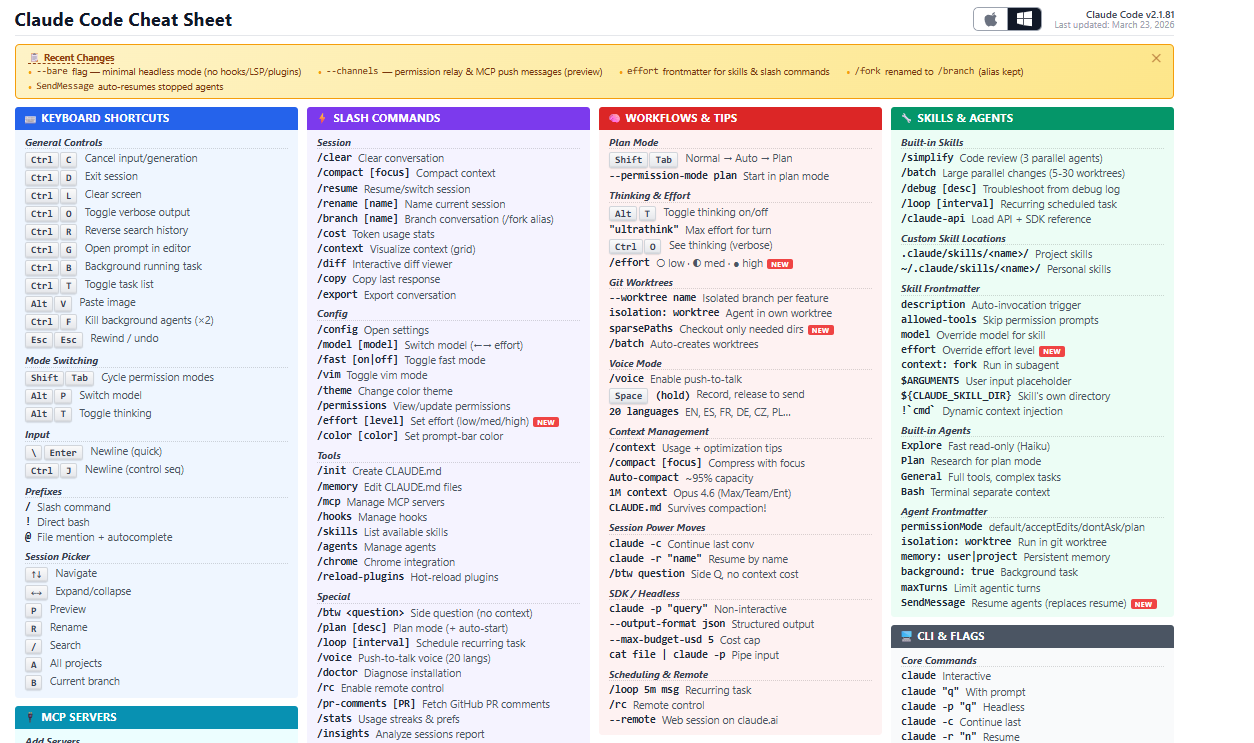
 The article steps back from modern LLMs and shows how a simple Markov chain can power autocomplete and tiny text generation. It explains how to count word-to-word transitions, turn them into next-word probabilities, and use those to suggest or generate text. It also shows why greedy choices become repetitive and how adding randomness helps. The piece is a practical primer on building a tiny, understandable language model from scratch.
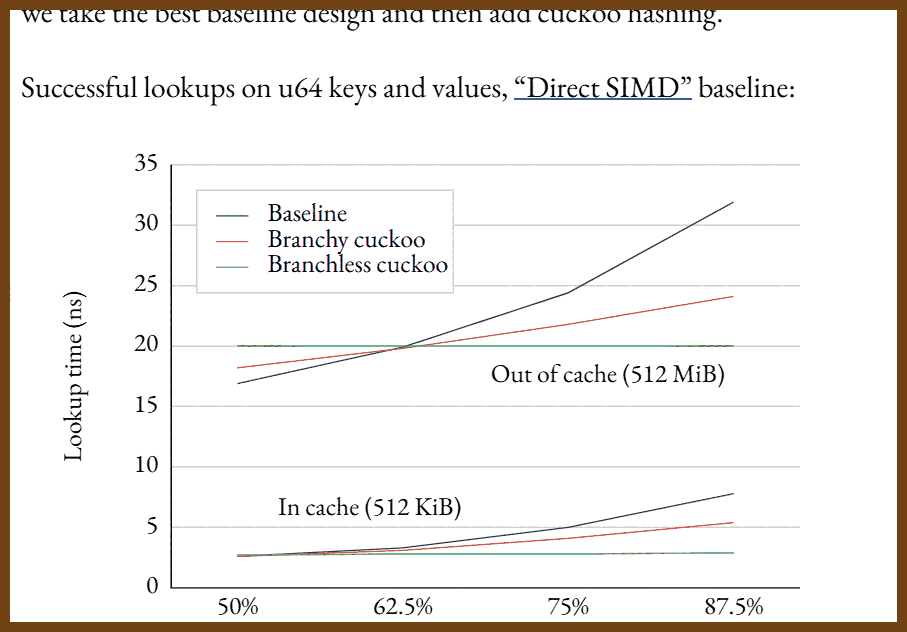
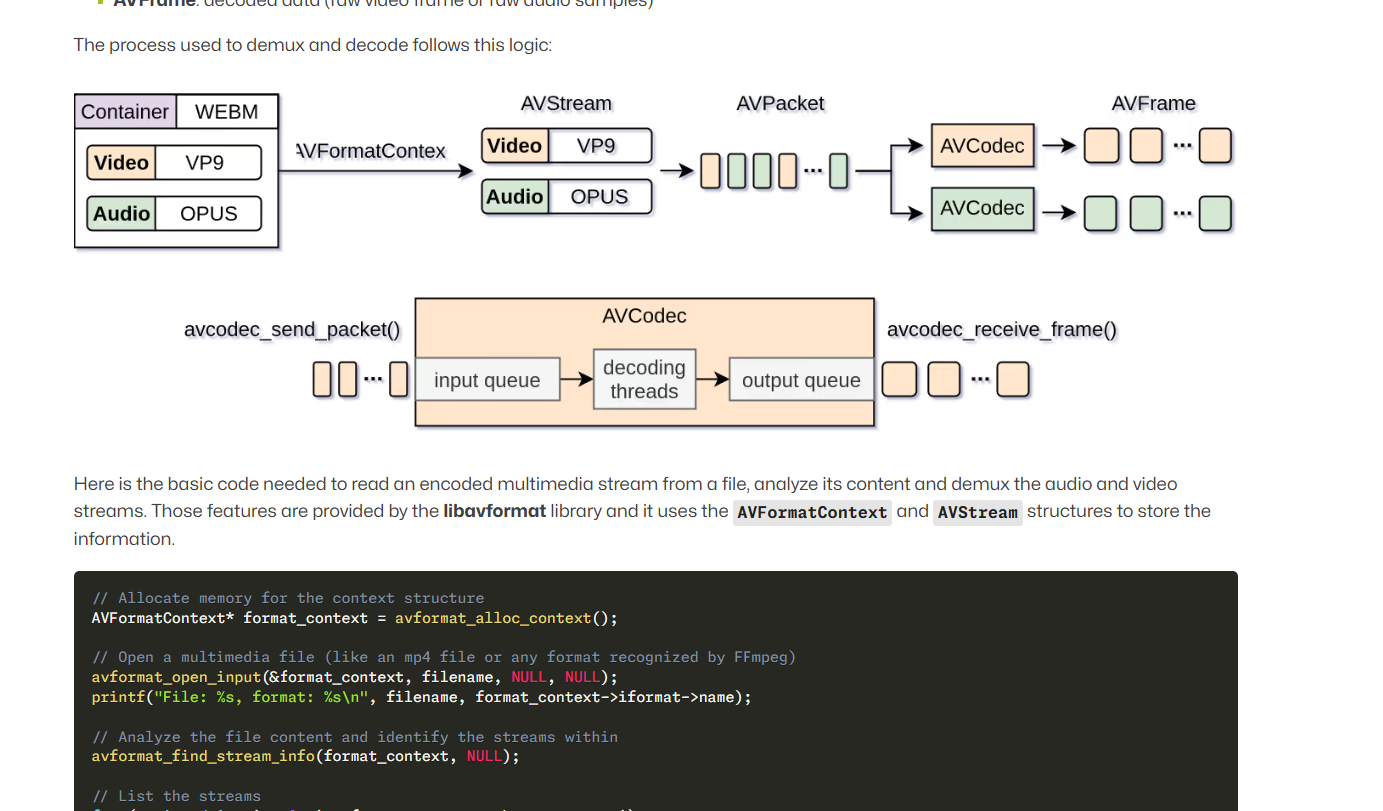
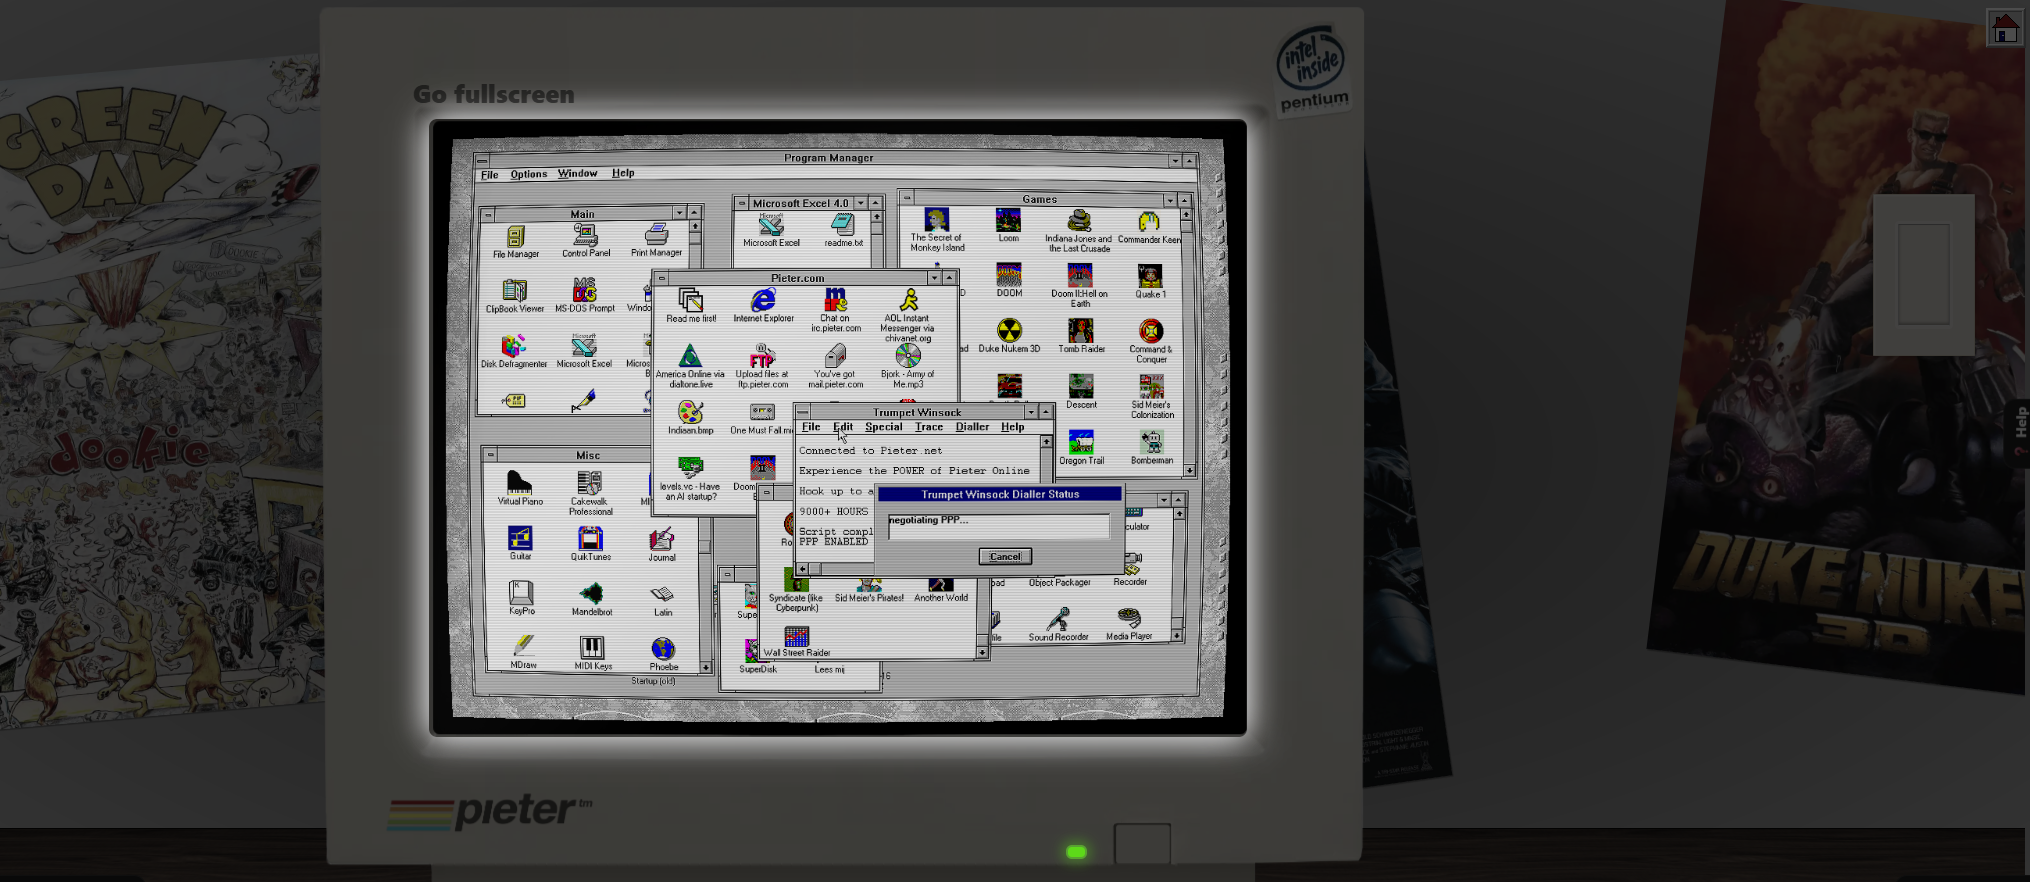
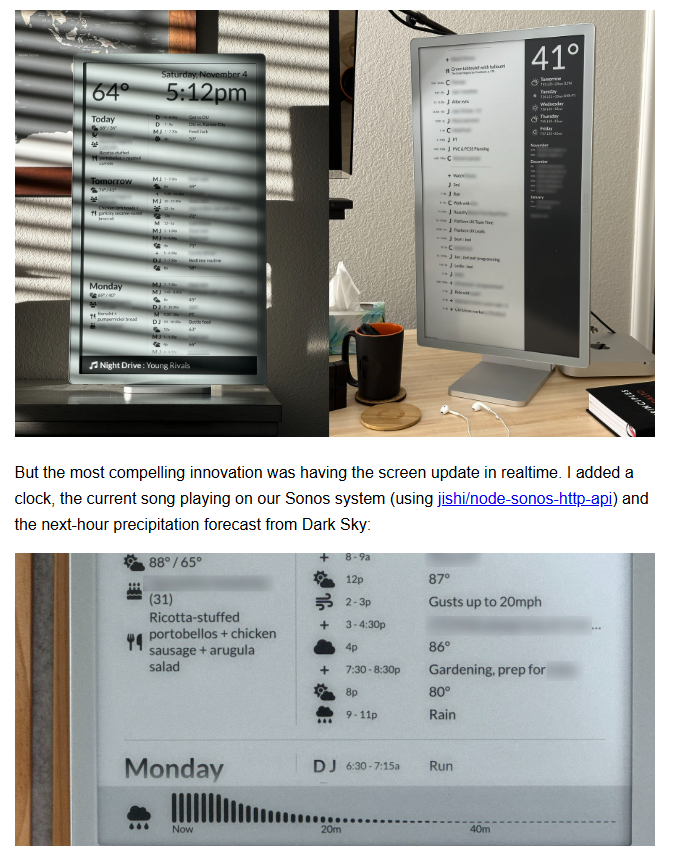
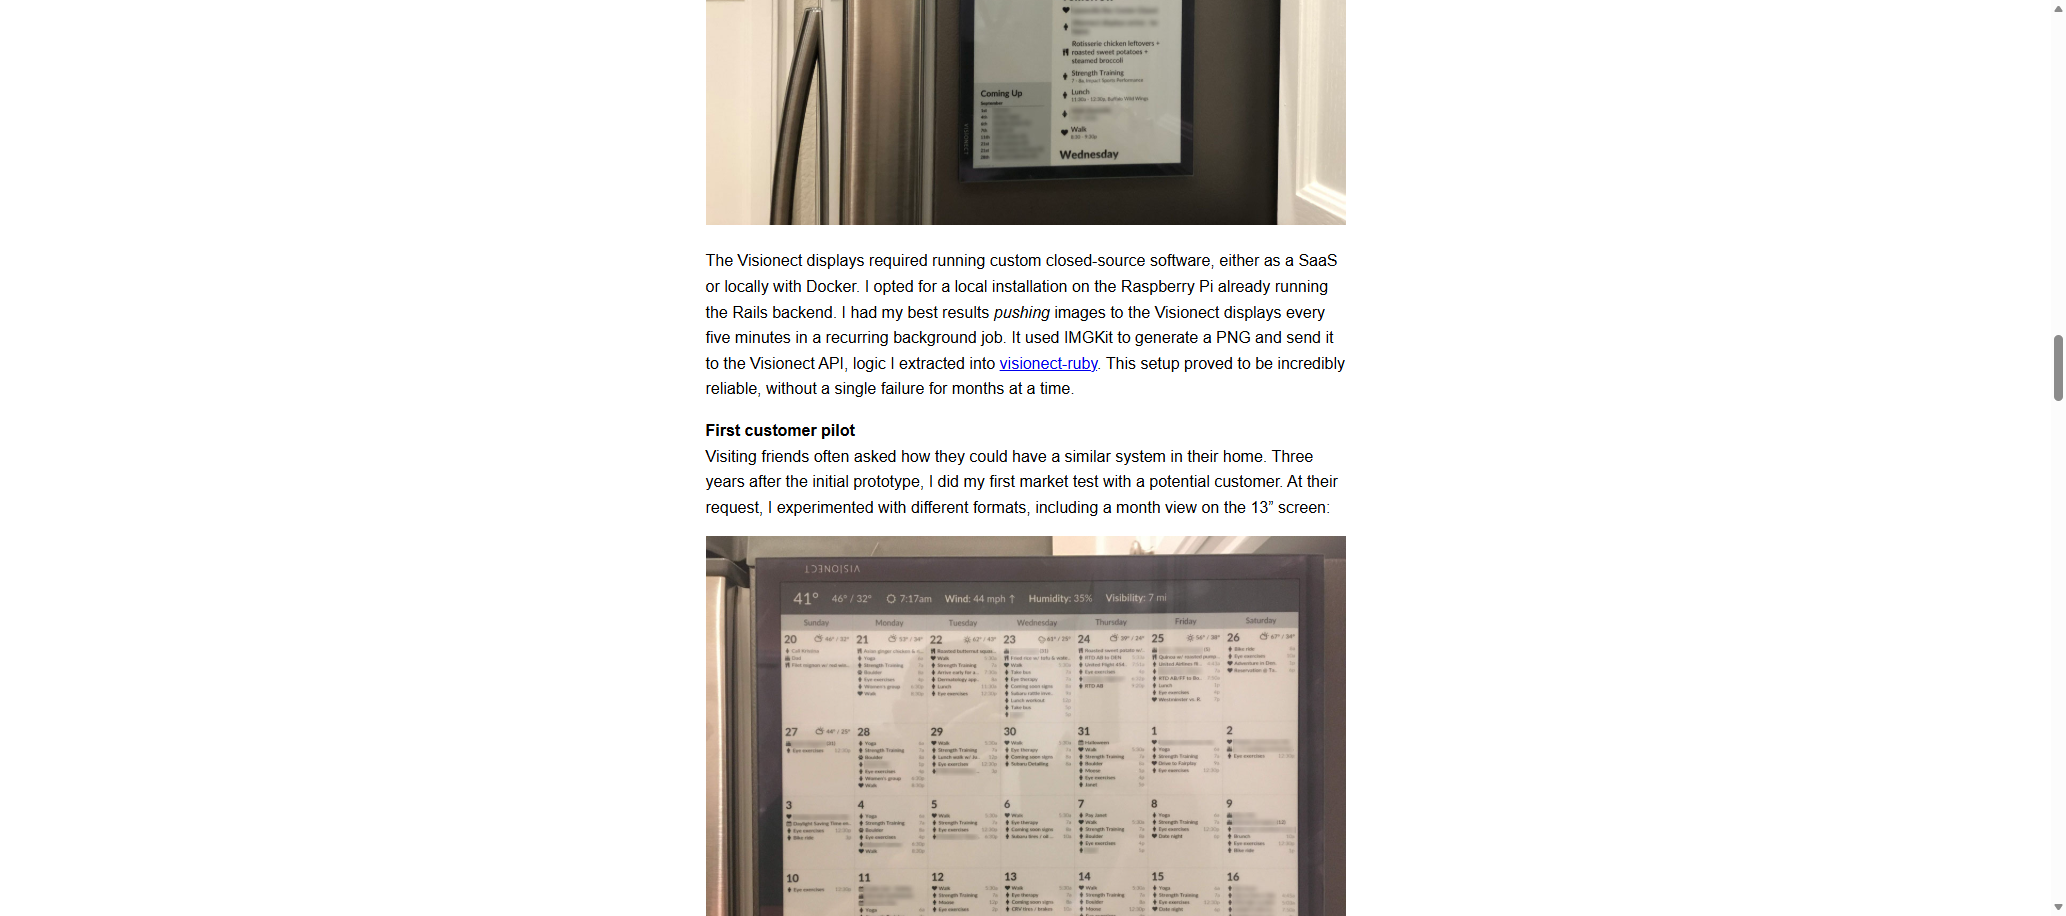
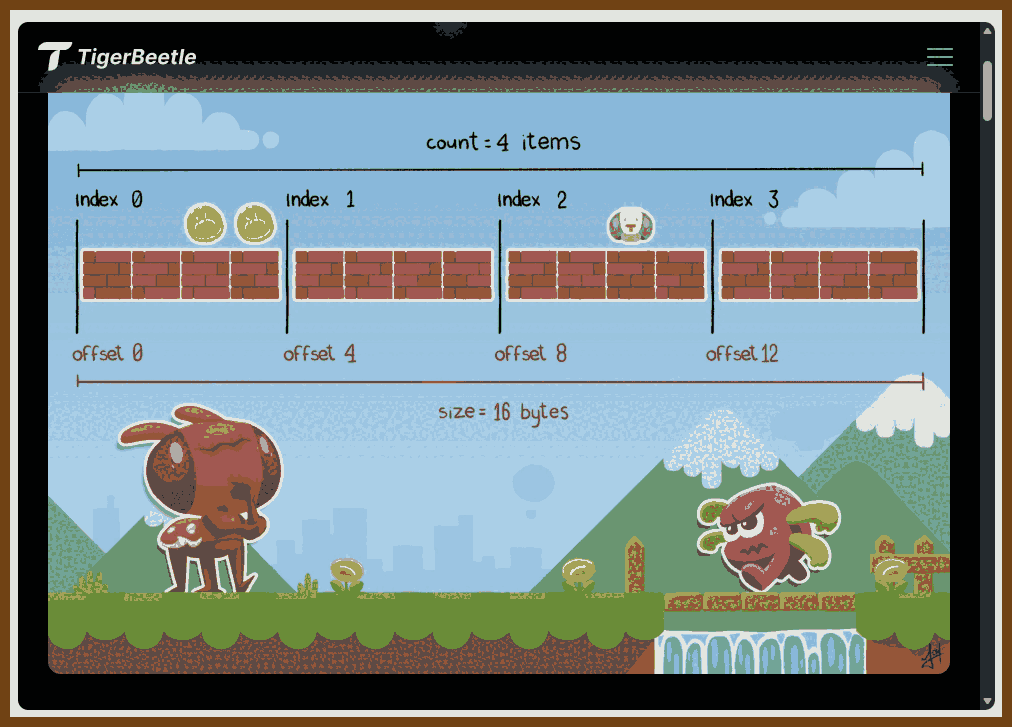
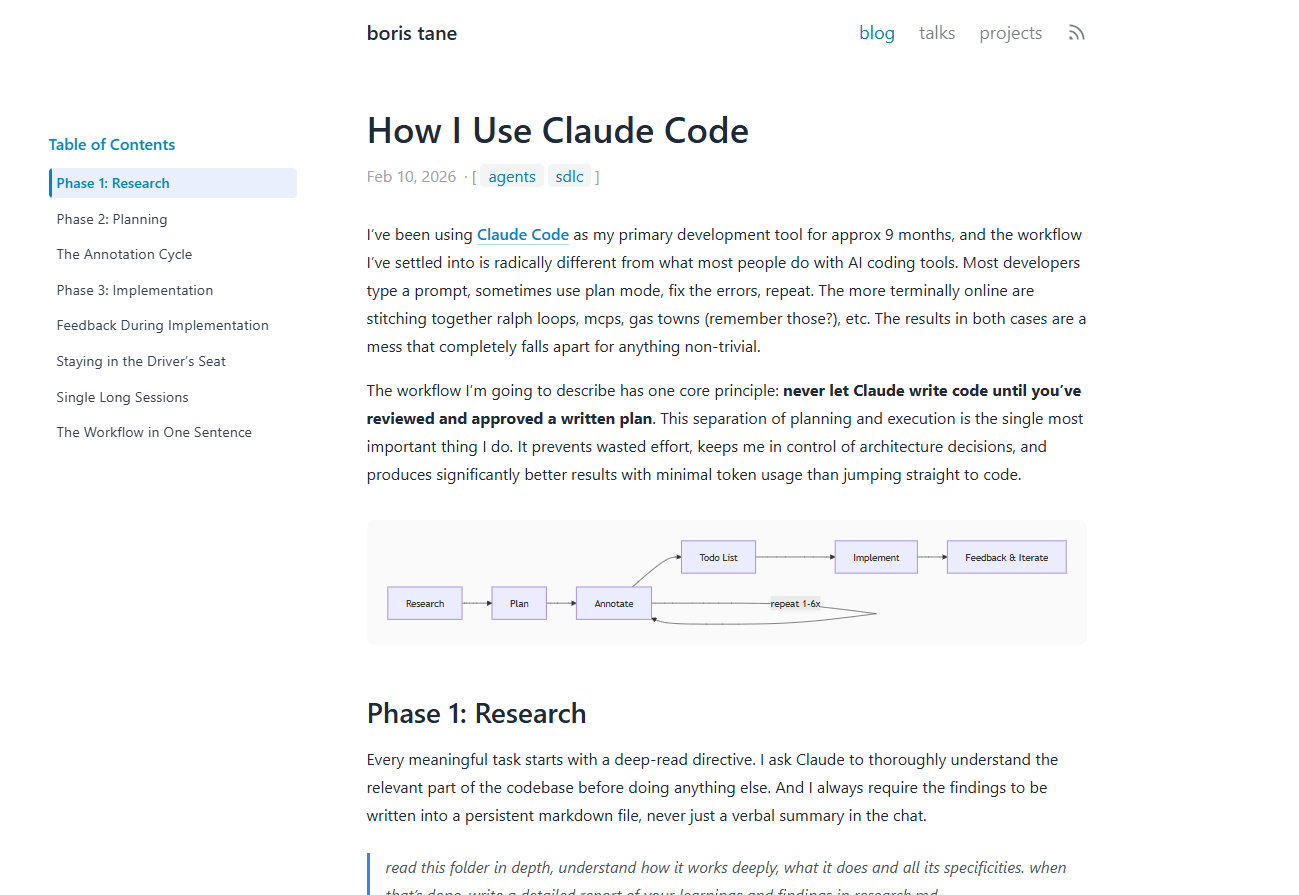 The workflow I’m going to describe has one core principle: never let Claude write code until you’ve reviewed and approved a written plan. This separation of planning and execution is the single most important thing I do. It prevents wasted effort, keeps me in control of architecture decisions, and produces significantly better results with minimal token usage than jumping straight to code.
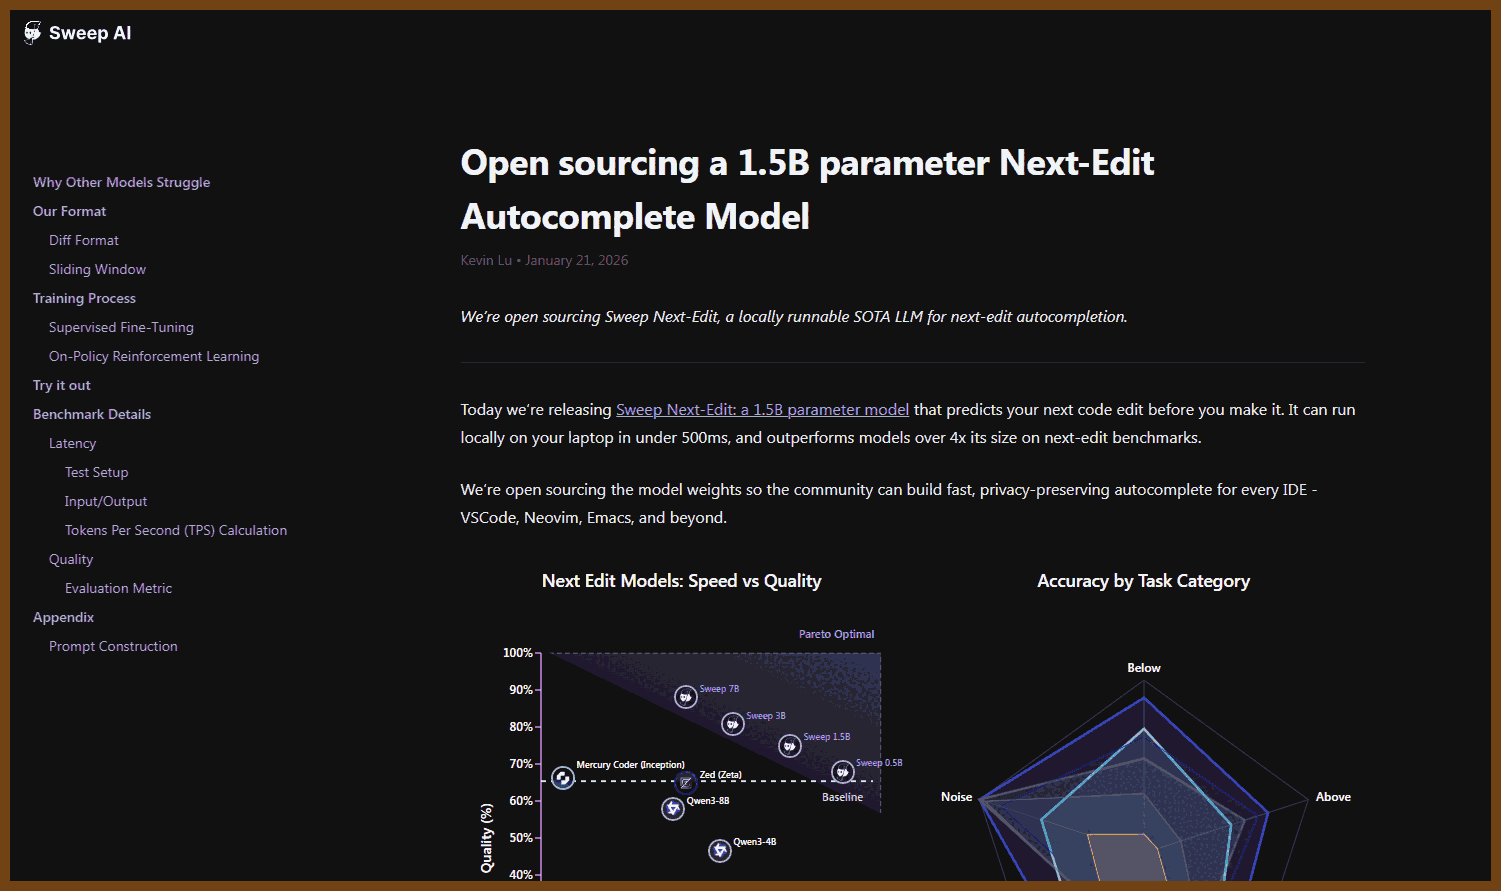
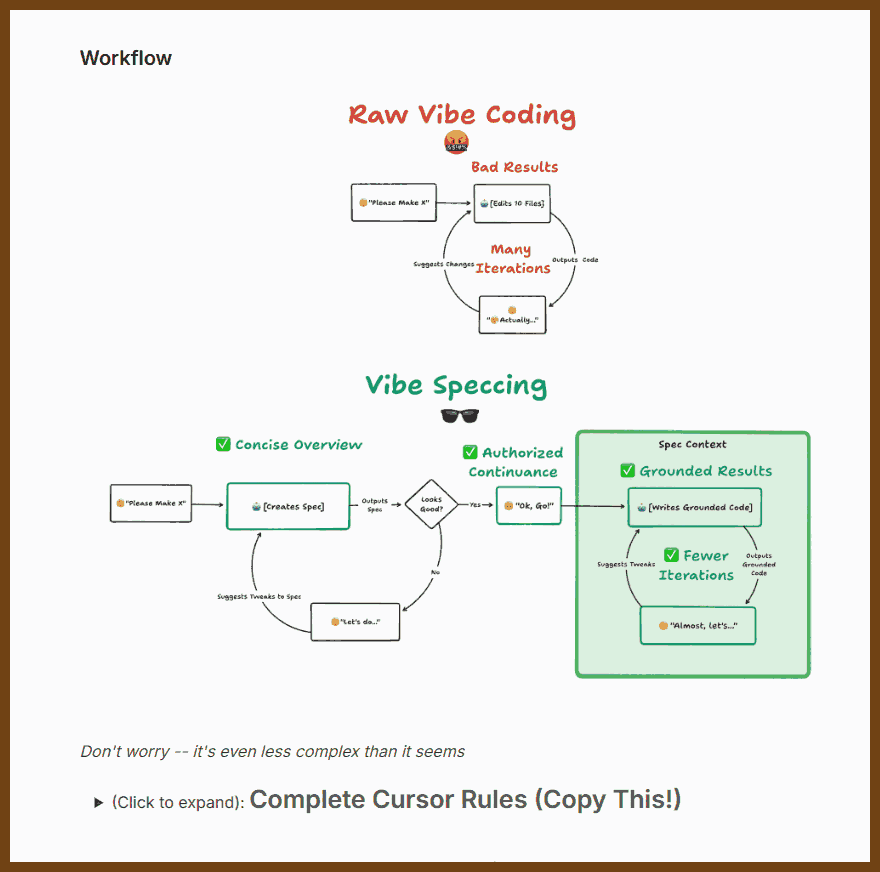 Speed does not matter if the result is wrong or unusable. The core claim is that AI-assisted coding often optimizes for fast output instead of correct intent, so the first priority should be locking down what "useful" means.
 In this talk we will discuss why CSS has such a bad reputation, why those complaints are often valid, and why it still matters because you cannot really build for the web without touching it.
 When someone asks for a timeline before you understand the work, giving a confident answer is risky because it turns into a promise you cannot reliably keep.
 Crafting Interpreters contains everything you need to implement a full-featured, efficient scripting language. You’ll learn both high-level concepts around parsing and semantics and gritty details like bytecode representation and garbage collection. Your brain will light up with new ideas, and your hands will get dirty and calloused. It’s a blast.